widemem.ai
开源AI记忆层,具备重要性评分、时间衰减、分层记忆及YMYL优先级排序功能
文档
widemem
Goldfish memory? ¬_¬ Fixed.


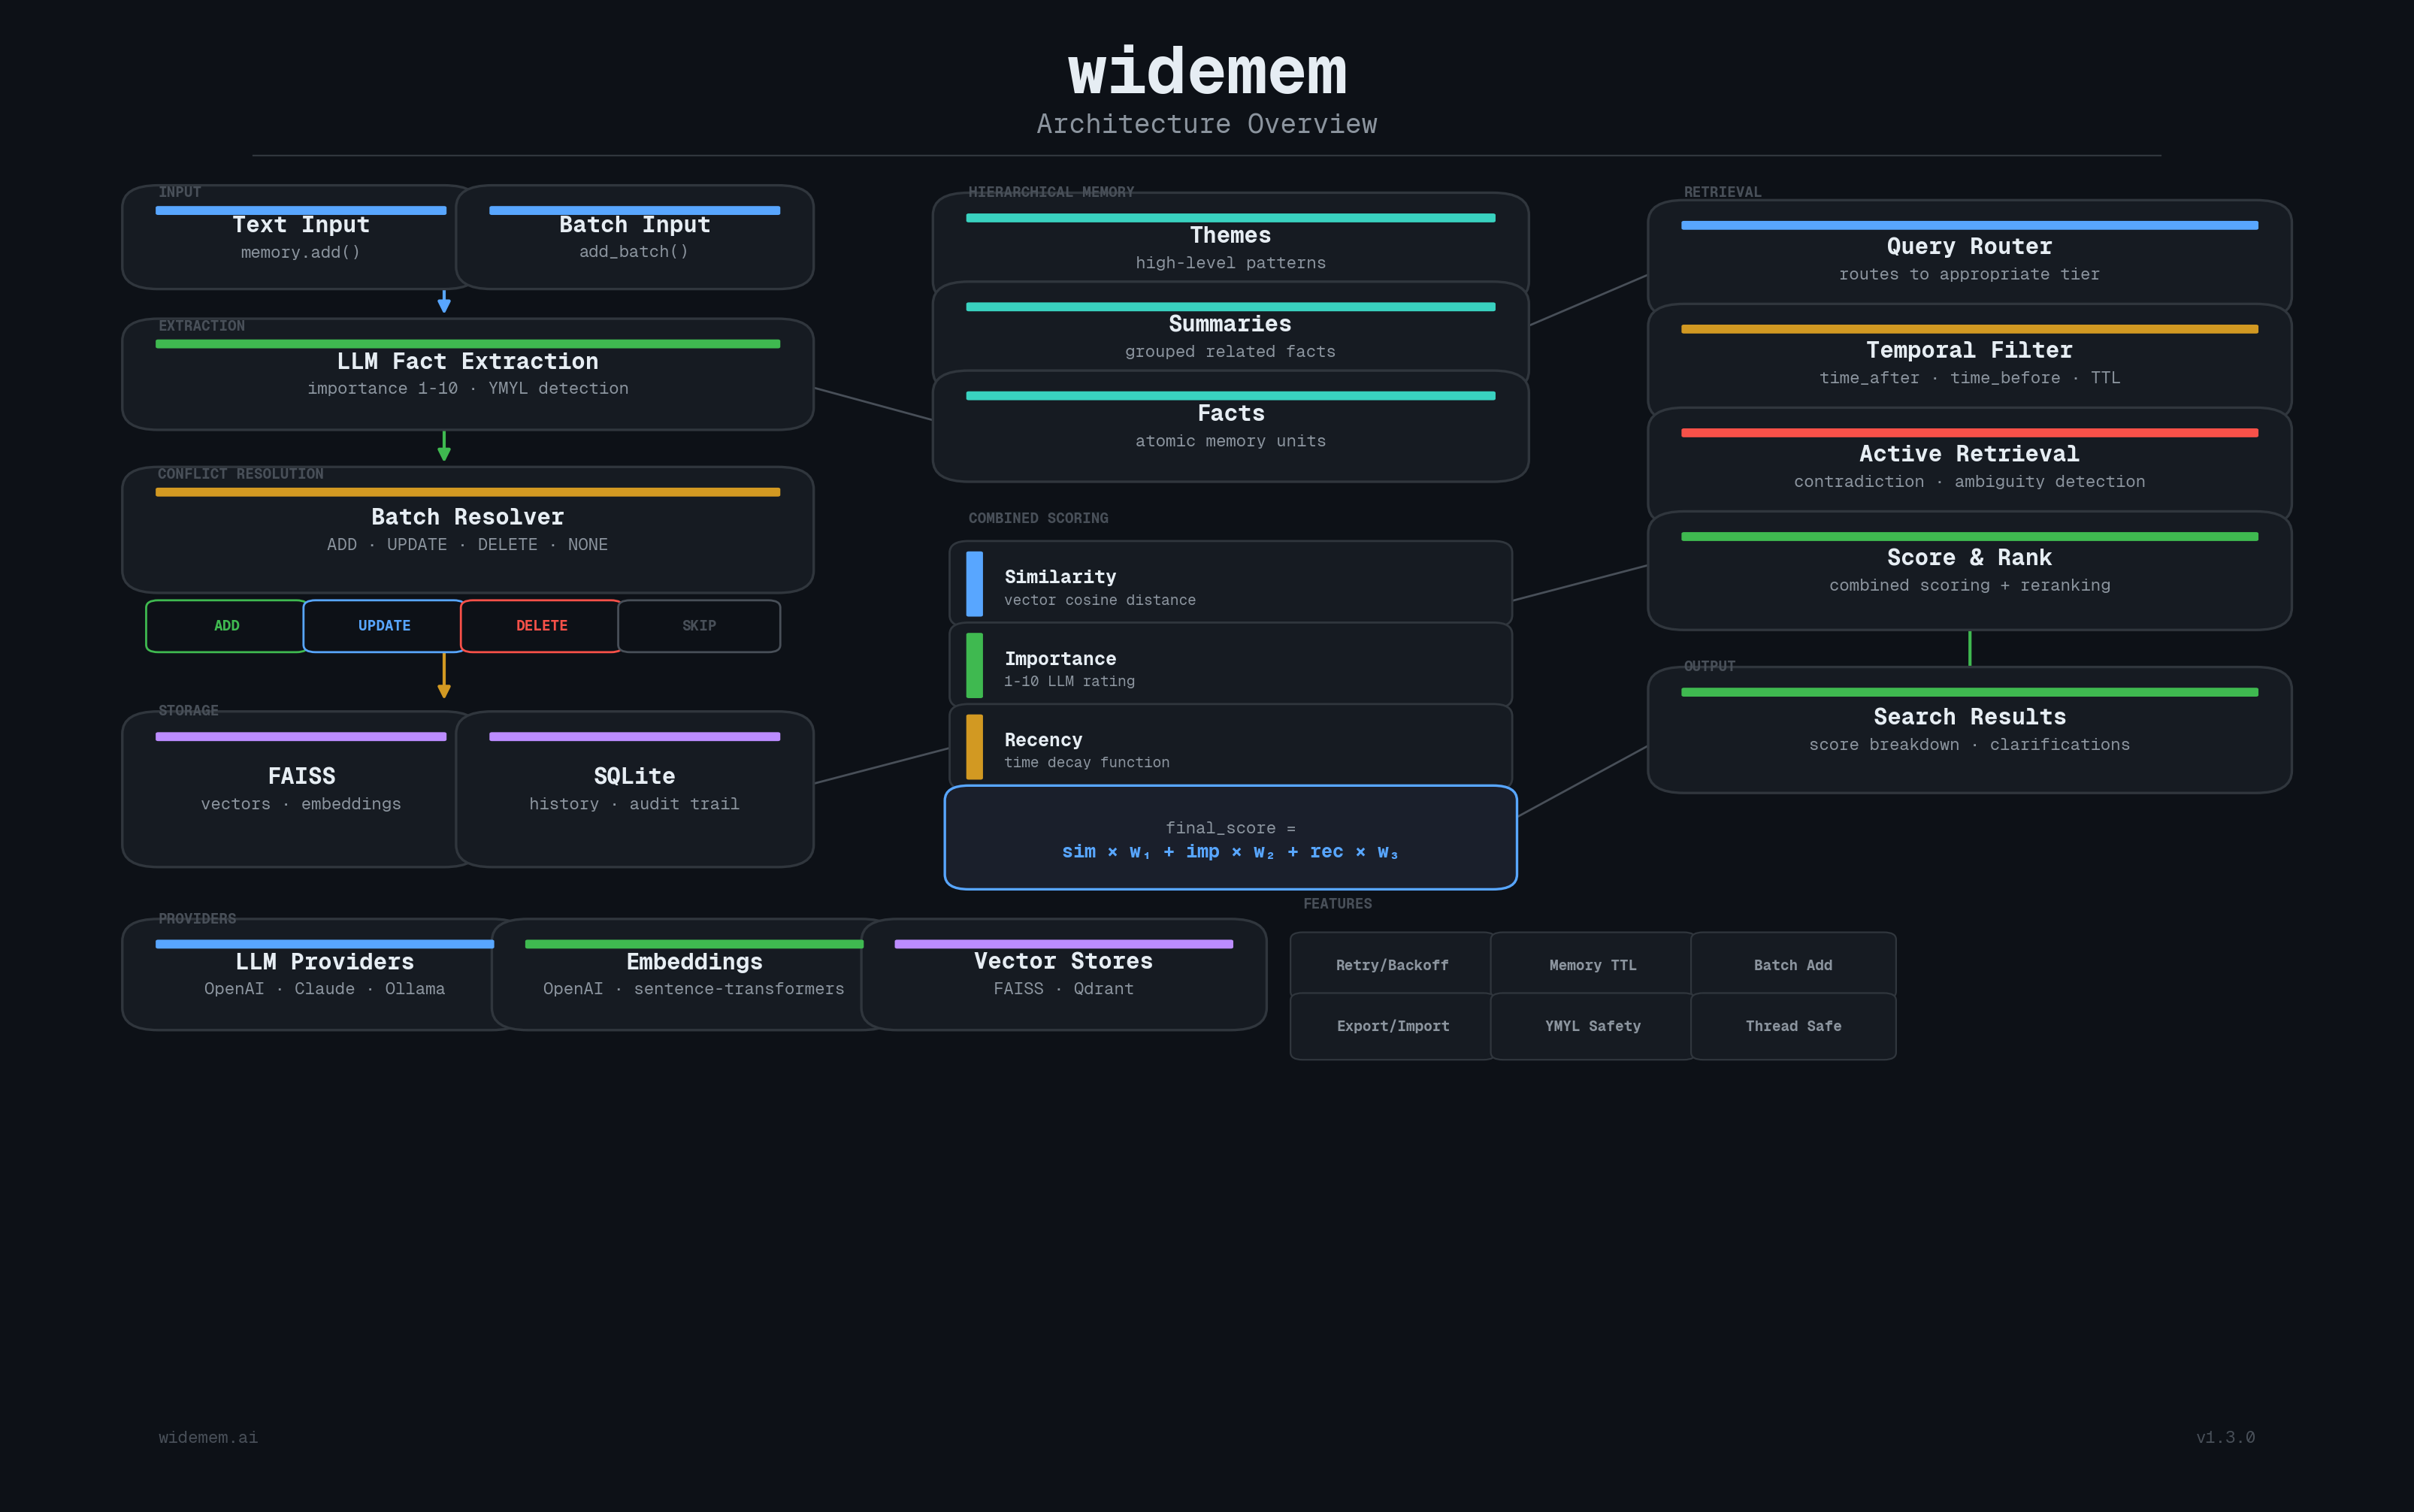
widemem is a local-first memory layer for LLM apps. It extracts facts from conversations, ranks them by importance and recency, resolves contradictions in one LLM call, and tells your agent how confident it is before it answers. By default everything runs on your machine: Ollama for the LLM, sentence-transformers for embeddings, FAISS and SQLite for storage. Cloud providers (OpenAI, Anthropic) are optional add-ons.
Install
pip install "widemem-ai[local]"   # FAISS, Ollama client, sentence-transformers
ollama pull llama3.1:8b           # the default local model, 4.9 GB
You need Ollama installed and running. The first run also downloads the all-MiniLM-L6-v2 embedding model (about 90 MB) from Hugging Face; after that, set HF_HUB_OFFLINE=1 and widemem runs fully offline. Python 3.10+.
What local costs: [local] pulls PyTorch through sentence-transformers (about 550 MB on macOS; more on Linux with CUDA wheels), and with the defaults each add() makes up to two LLM calls, extract then resolve. On an Apple M4 with 32 GB, an add() took 5 to 17 seconds and a search 0.04 seconds. The default is llama3.1:8b because llama3.2 (3B) kept the stale fact and split "I'm allergic to penicillin" into one fact per word in every one of our test runs.
Upgrading from 1.6 or earlier: the defaults moved from OpenAI to local, and a 1536-dimension FAISS index will not load under the 384-dimension default embedder. Set provider="openai" on both LLMConfig and EmbeddingConfig to keep the old behavior. Details in the changelog.
Quick start
from widemem import WideMemory, MemoryConfig
from widemem.core.types import VectorStoreConfig

memory = WideMemory(MemoryConfig(
    vector_store=VectorStoreConfig(provider="faiss", path="./widemem_data"),
))

memory.add("I live in San Francisco and work as a software engineer", user_id="alice")
memory.add("I just moved to Boston", user_id="alice")   # checked against stored facts: ADD, UPDATE or DELETE

results = memory.search("where does alice live", user_id="alice")
if results:
    print(results[0].memory.content)                   # results.confidence says how sure it is
    history = memory.get_history(results[0].memory.id) # every write is logged
Without a path, FAISS keeps vectors in RAM and they are gone when the process exits; the SQLite history persists either way. WideMemory also works as a context manager.
Cloud providers, if you want them
No memory, prompt or embedding leaves your machine unless you configure a cloud provider. Each provider picks its own default model.
pip install "widemem-ai[openai,faiss]" # or [anthropic,local] for Claude + local embeddings
from widemem import WideMemory, MemoryConfig
from widemem.core.types import EmbeddingConfig, LLMConfig

# OpenAI for both: gpt-4o-mini and text-embedding-3-small
memory = WideMemory(MemoryConfig(
    llm=LLMConfig(provider="openai"),
    embedding=EmbeddingConfig(provider="openai"),
))

# Claude for extraction; embeddings and vectors stay local
memory = WideMemory(MemoryConfig(llm=LLMConfig(provider="anthropic")))
Set OPENAI_API_KEY or ANTHROPIC_API_KEY. Mixing is fine: a cloud LLM with local embeddings keeps every vector on your machine.
| Layer | Default (local) | Options |
|---|---|---|
| LLM | Ollama llama3.1:8b | OpenAI, Anthropic, any Ollama model |
| Embeddings | sentence-transformers all-MiniLM-L6-v2 | Ollama nomic-embed-text, OpenAI |
| Vectors | FAISS | Qdrant (embedded, localhost:6333 or a remote url), pgvector |
| History | SQLite |
Every field and default: docs/configuration.md.
How widemem differs
| Feature | What it does |
|---|---|
| Importance and decay | The LLM rates each fact 1 to 10. Search blends similarity, importance and recency, with weights adapted to the question type. |
| Batch conflict resolution | New facts and the related stored memories go to the LLM in one call, which decides ADD, UPDATE, DELETE or no-op for each. |
| YMYL protection | Opt-in. Health, financial, legal and safety facts get an importance floor of 8, no decay, and forced contradiction checks. Regex catches the obvious cases; the extraction LLM tags the implied ones. |
| Confidence | Every search returns HIGH, MODERATE, LOW or NONE, so an agent can say "I don't have that" instead of guessing. |
| Hierarchy | summarize() rolls facts into summaries and themes (a no-op under 10 facts unless force=True). In balanced and deep mode, broad questions then get themes and specific ones get facts. |
| Retrieval modes | fast, balanced and deep retrieve 10, 25 or 50 memories. |
| Audit log | Adds, updates, deletes, imports and pins are logged to SQLite with the content on both sides. Entries record what changed and when, not who. |
How each one works, with snippets: docs/guide.md. YMYL details and limits: YMYL.md.
Benchmark
On LoCoMo's 1,540 answerable questions (the adversarial category excluded, as for every system on the comparison page), widemem 1.5.0 scored 55.15% with an independent GPT-4o judge (56.32% self-graded), using about 213 tokens of context per query. That run used OpenAI (gpt-4o-mini, text-embedding-3-small) with top_k=10 per speaker; the local default has not been benchmarked yet. It places widemem in the lower half of the eight systems on widemem.ai/benchmarks, at a small fraction of the context most of them use.
Per-category labels published before 2026-07-06 were wrong; the correction is in the corrections log.
The runner (benchmark/run_ws1.py) and question split are in this repo. To re-run it, clone snap-research/locomo into benchmark/locomo-data/ (the runner reads data/locomo10.json) and set OPENAI_API_KEY.
Integrations
MCP server for Claude Desktop, Cursor and other MCP clients. Runs on the local stack by default.
pip install "widemem-ai[mcp,local]"
python -m widemem.mcp_server
Tools exposed: widemem_add, widemem_search, widemem_delete, widemem_count, widemem_pin, widemem_export, widemem_health. Setup and environment variables: docs/mcp.md.
LangChain. widemem.integrations.langchain.WidememRetriever is a BaseRetriever. Install [langchain]; example in examples/langchain_retriever.py.
REST server. pip install "widemem-ai[server,local]", then python -m widemem.server. It refuses to start when WIDEMEM_HOST is non-local and WIDEMEM_API_KEY is unset. The check reads WIDEMEM_HOST, not the bind address, so set it even when you launch uvicorn yourself. In Docker, the image talks to Ollama for both the LLM and embeddings; point them at Ollama on the host with WIDEMEM_LLM_BASE_URL and WIDEMEM_EMBEDDING_BASE_URL (http://host.docker.internal:11434). (Linux Docker Engine: also pass --add-host=host.docker.internal:host-gateway)
API
| Method | Does |
|---|---|
add(text, user_id, ...) / add_batch(texts, ...) | Extract, resolve and store facts |
search(query, user_id, top_k, mode, explain, ...) | Ranked results with .confidence; explain=True returns a scored breakdown |
search_stream(...) | Async generator, approximate order |
pin(text, user_id, importance=9.0) | Store a fact the user flagged as important |
get, delete, count, get_history | The usual |
purge_expired(older_than_days, ...) | Delete old memories for good (YMYL kept unless asked) |
export_json / import_json | Move memories between stores |
summarize(user_id, force) | Build summaries and themes |
Full signatures: docs/api.md.
Scope and safety
widemem is developer infrastructure, provided under Apache 2.0 as is. It is not medical, legal, tax or financial advice, and not a medical device. YMYL handling is a best-effort heuristic, the prompt-injection sanitizer is a baseline defense on extraction input, and the history log does not record callers. Keep a human in the loop for high-stakes decisions. When you self-host, your data stays in your environment and we receive nothing. The software may be subject to export-control and sanctions laws (including the US EAR and OFAC lists).
Roadmap
Open issues; vote with reactions:
- #21 Source-message provenance: link each fact in the history log to the message that produced it
- #22 LangChain
BaseChatMessageHistoryadapter - #24 LangGraph
BaseStoreadapter
Managed hosting is available on request: hello@widemem.ai.
Not planned: more vector backends beyond FAISS, Qdrant and pgvector; a self-serve multi-tenant service; a web UI; a GraphQL API; a memory-management CLI.
Development
git clone https://github.com/remete618/widemem-ai
cd widemem-ai
pip install -e ".[all,dev]"
pytest
Further reading
- Why Context Windows Aren't Memory
- Your AI Memory Can't Tell a River Bank from a Savings Account
- Your AI Should Know When It Doesn't Know
- Whitepaper: How LLMs Handle Memory
Contact and license
hello@widemem.ai · widemem.ai · issues
Apache 2.0, see LICENSE. Website terms: widemem.ai/terms.