Agentic Document Parsing and Extraction (ADP)
ADP, yurt dışı faturaları, yurt içi belgeleri, satın alma sözleşmelerini, lojistik belgelerini, finansal tabloları ve ticaret sözleşmelerini otomatik olarak sınıflandırır ve anahtar alanları doğru bir şekilde çıkarır. Ayrıca tablo ayrıştırma, içerik doğrulama ve çok dilli tanımayı destekler. Şablon kurulumu, veri etiketleme veya sürekli kural bakımı gerektirmez ve yüksek hacimli belge işleme görevlerini verimli bir şekilde yönetir.
Dokümantasyon
About ADP MCP Server
ADP MCP Server connects MCP-compatible AI clients to Laiye's Agentic Document Processing (ADP) platform for document parsing, extraction and workflow applications. This Node.js package runs locally over stdio, letting clients discover tools, process documents and query results from the conversation.
ADP integrates Vision-Language Models (VLM), Large Language Models (LLM) and autonomous agent decision-making technologies. It reshapes traditional document processing by transforming conventional rule-based field extraction into goal-driven end-to-end intelligent automation. Focused on intelligent processing of business documents, ADP automatically classifies overseas invoices, domestic vouchers, procurement contracts, logistics documents, financial statements and trading contracts, and accurately extracts key fields. It also supports table parsing, content verification and multilingual recognition. Requiring no template setup, data labeling or ongoing rule maintenance, it efficiently handles high-volume document processing tasks.
Quick Start
1. Get Your API Key
Sign up at https://adp-global.laiye.com/ and retrieve your API Key from My MCP in personal settings.
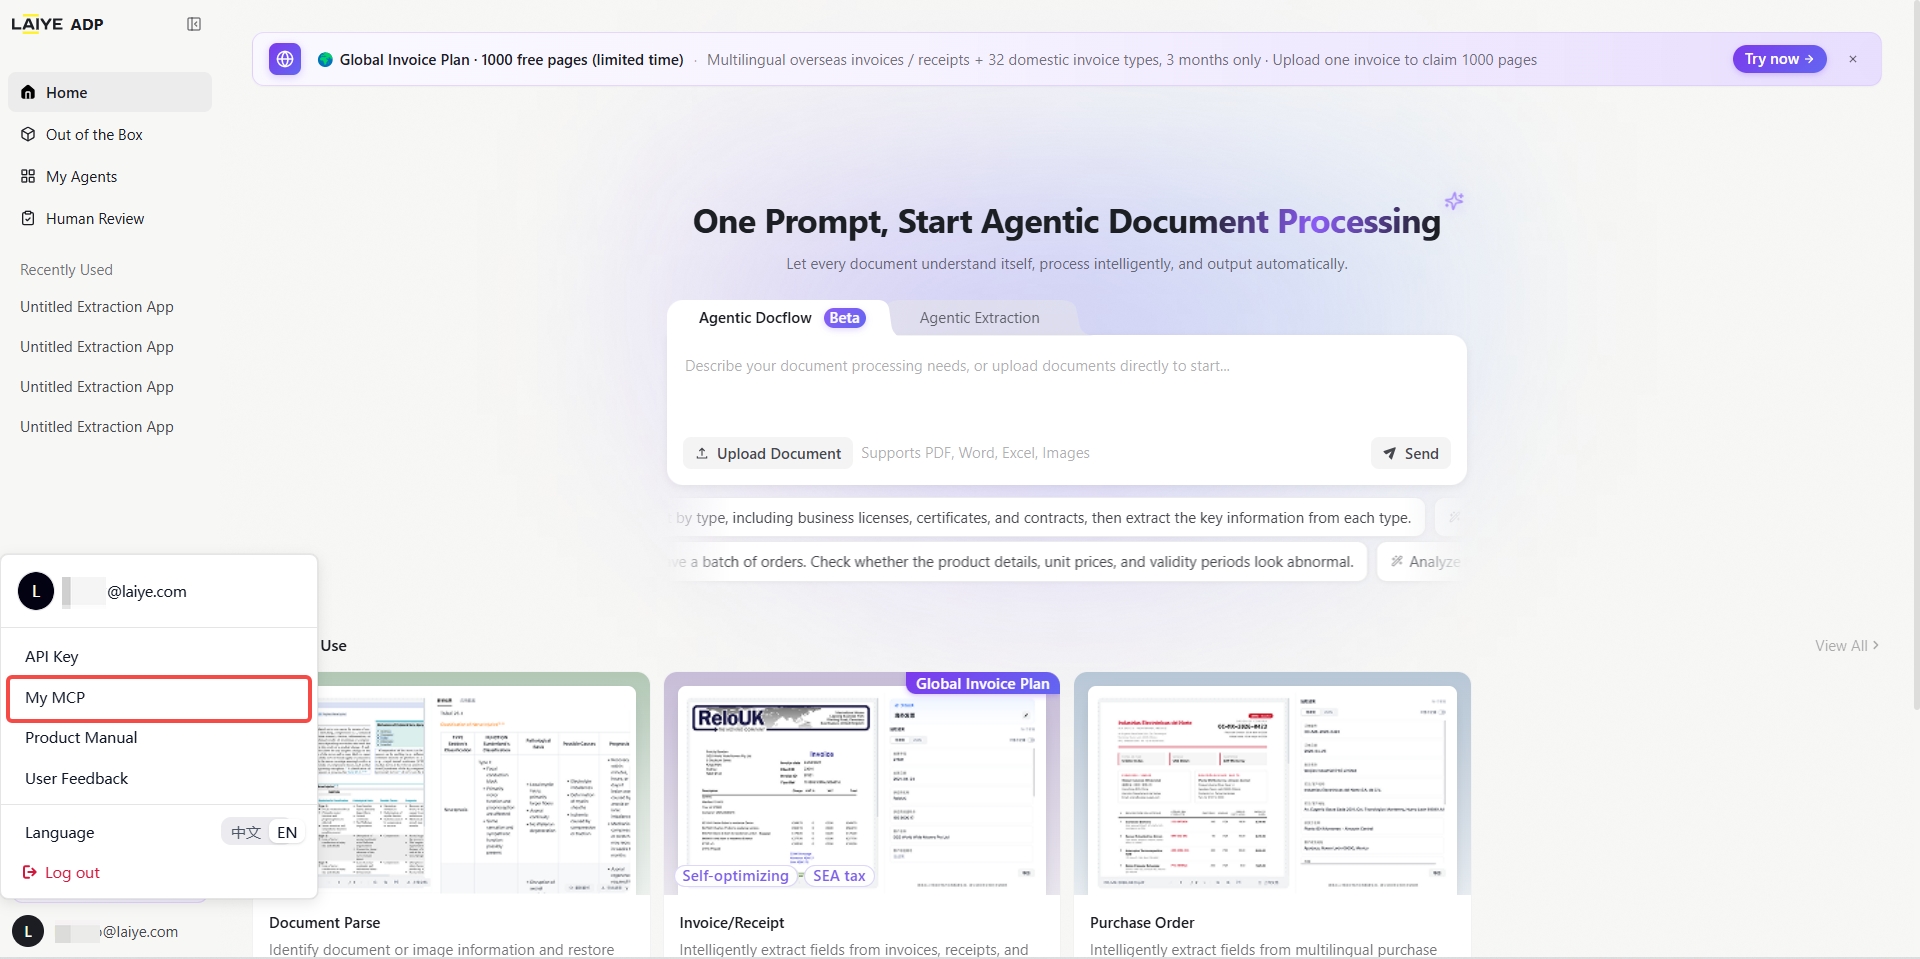
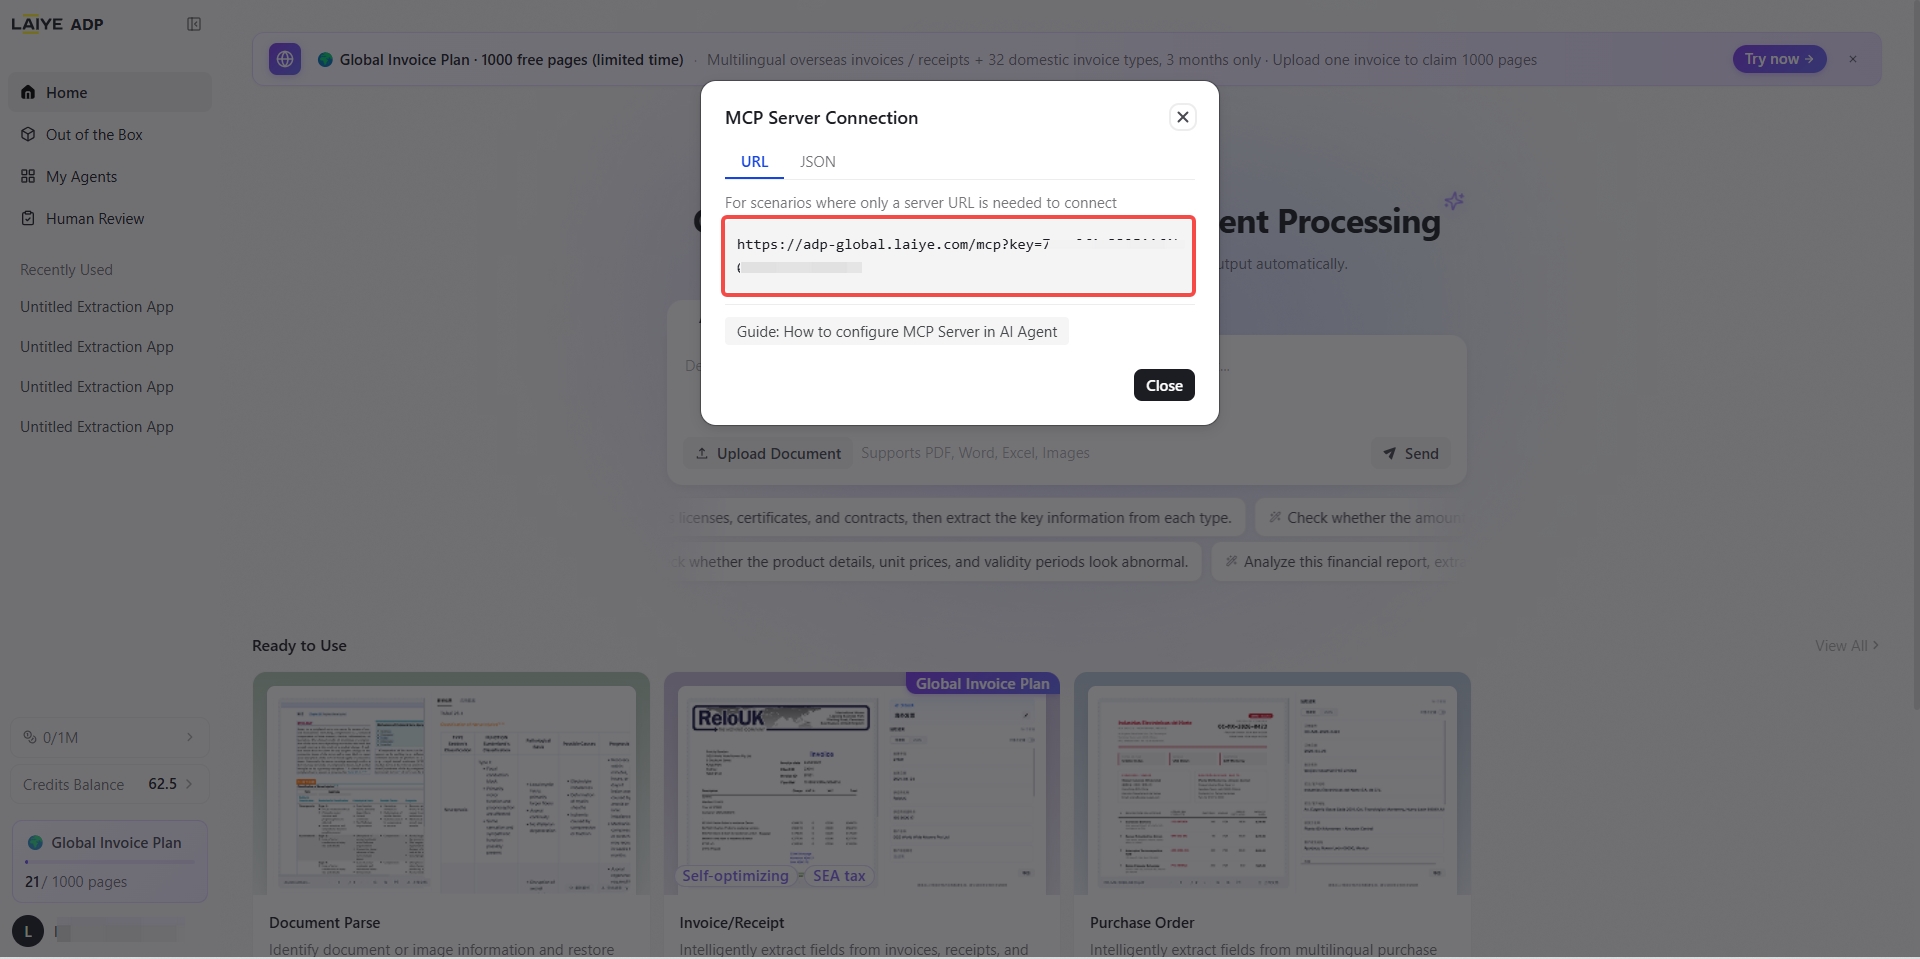
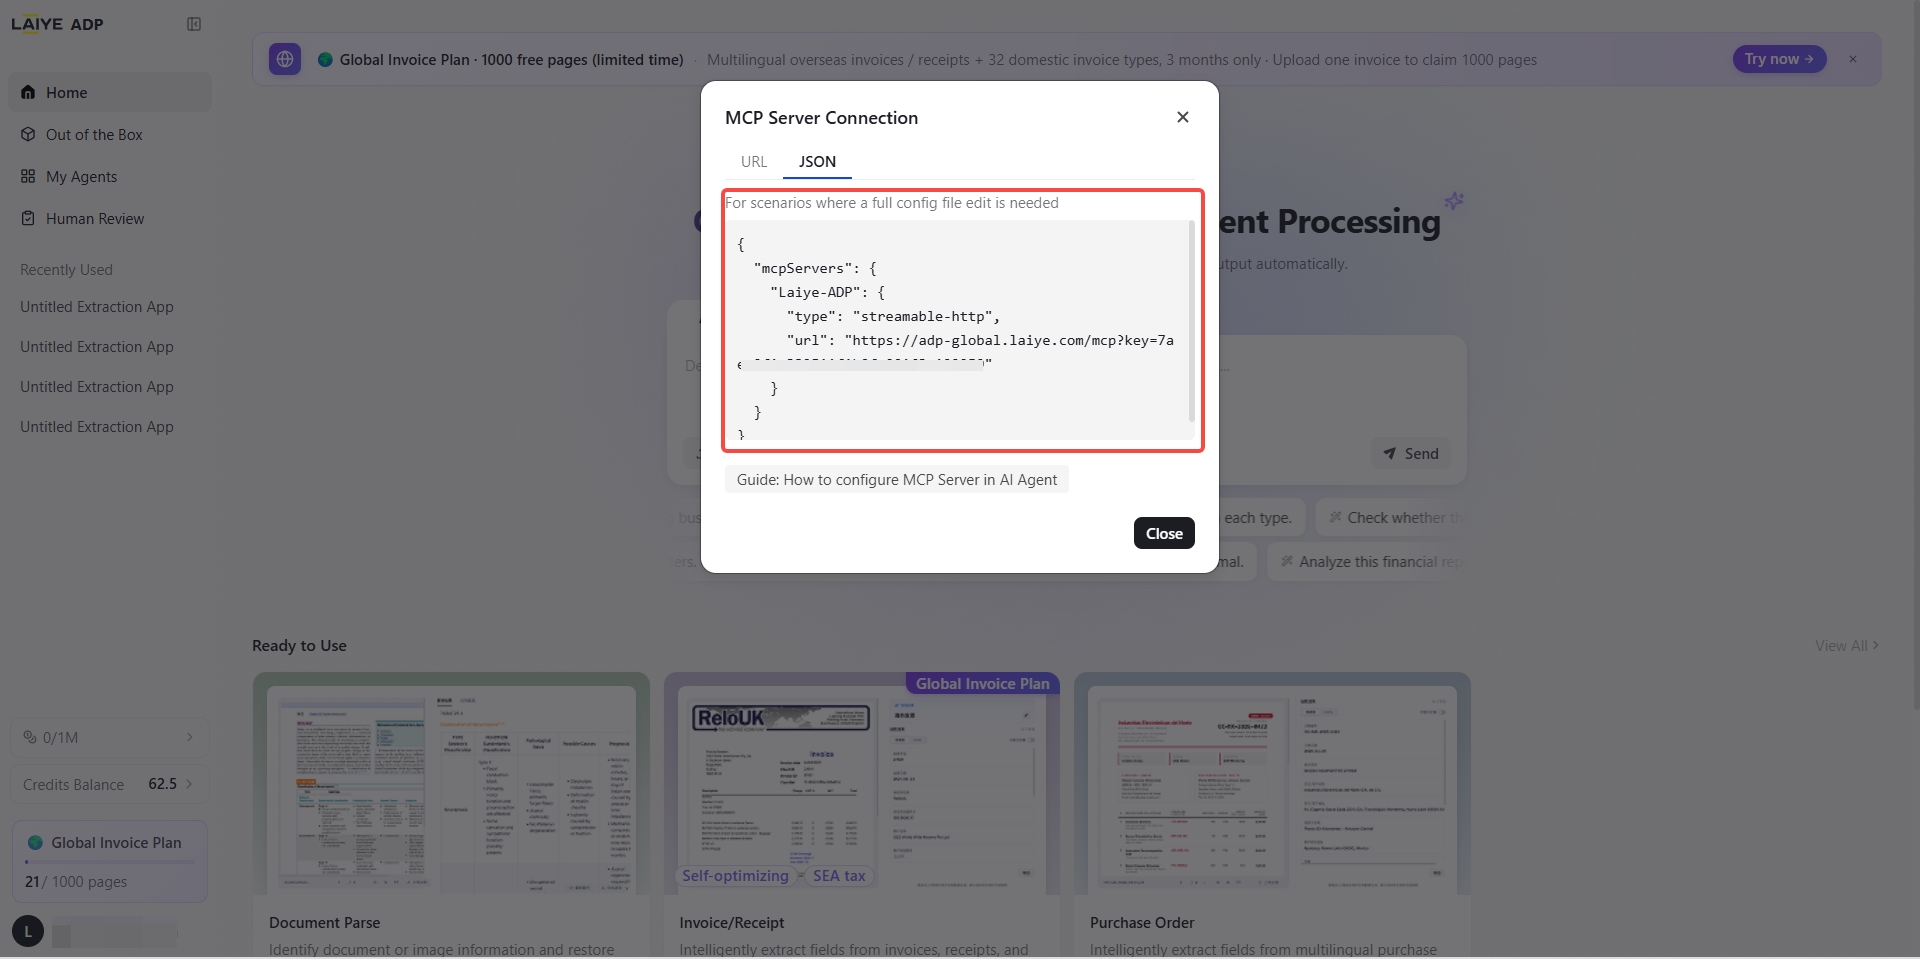
2. Configure Your MCP Client
The ADP MCP Server runs over stdio transport: the client launches a local process via npx and passes your API Key through an environment variable. Add the following to your client's MCP config file (e.g. Claude Desktop's claude_desktop_config.json, Cursor's mcp.json):
{
  "mcpServers": {
    "adp": {
      "command": "npx",
      "args": ["-y", "@laiye-adp/mcp"],
      "env": {
        "ADP_API_KEY": "<YOUR-ADP-API-Key>",
        "API_SOURCE": "npm-mcp"
      }
    }
  }
}
The same parameters apply to any MCP client:
| Parameter | Value |
|---|---|
| Command | npx |
| Args | ["-y", "@laiye-adp/mcp"] |
| Transport | stdio |
| Authentication | Environment variable ADP_API_KEY=<YOUR-ADP-API-Key> |
| Source marker | Optional environment variable API_SOURCE, default npm-mcp |
The optional environment variable
ADP_ACCEPT_LANGUAGE(zh/en, defaultzh) switches the API language and domain. The optional environment variableAPI_SOURCEsets the OpenAPI request headerX-Api-Source; the default isnpm-mcp. Requires Node.js 20+ installed locally.
3. Start Using
Once connected, your AI client will automatically discover all available ADP tools. Just describe what you need in natural language:
- "Upload this local file and extract fields from the returned URL"
- "Parse the structure of this PDF"
- "Extract the information from this ID card"
- "Pull the amount and date from this invoice"
Tool Catalog
Document Parsing
| Tool Name | Title | Description |
|---|---|---|
upload_temporary_file | Upload Temporary File | Upload chunk and return download_url. Pass data.download_url to parsing or extraction tools as the file parameter. |
parse_document | General Document Parsing | Parse PDF, image, Word, Excel, PPT and other documents for layout analysis, returning structured text blocks, tables, reading order and page coordinates. Use when the document type is unknown and you need raw structure for further processing; for invoices, ID cards or other specific types, prefer the dedicated extraction tool. |
Invoice & Order Extraction
| Tool Name | Title | Description |
|---|---|---|
extract_china_invoice | China Invoice / Bill | Covers 30+ common Chinese bill types: fully-digitalized e-invoices, general VAT invoices, special VAT invoices, taxi receipts, train tickets, air itineraries, fiscal invoices, etc. Extracts invoice number, date, amount, buyer, seller and other key fields; also supports invoice authenticity verification. |
extract_global_invoice | Global Invoice / Receipt | Extract key fields (invoice number, date, amount, tax, currency, line items, etc.) from overseas invoices, receipts or bills in PDF or image format. Ideal for cross-border trade, reimbursement and accounts-payable automation; for Chinese VAT invoices, use the dedicated China invoice tool. |
extract_purchase_order | Purchase / Sales Order | Extract key fields (order number, buyer/seller info, order date, item details, quantity, unit price, total amount, shipping address, etc.) from purchase or sales orders in PDF or image format. Suitable for e-commerce order entry, supply-chain reconciliation and warehouse management automation. |
Card & Certificate Extraction
| Tool Name | Title | Description |
|---|---|---|
extract_id_card | China ID Card | Extract key fields (name, gender, ethnicity, date of birth, ID number, address, issuing authority, validity period, etc.) from Chinese mainland resident ID card images. Supports both front and back sides. For HK/Macao/Taiwan permits or passports, use the corresponding tool. |
extract_bank_card | Bank Card | Extract key fields (card number, issuing bank, card type, expiration date, etc.) from the front side of a bank card image. Only public card-face information is recognized; sensitive fields such as CVV are not extracted. |
extract_vehicle_cert | Vehicle Certificate | Extract key fields (certificate number, vehicle brand, model, VIN, engine number, manufacturing date, etc.) from vehicle certificate of conformity images. Suitable for vehicle registration, used-car transactions and fleet management. |
extract_account_permit | Bank Account Permit | Extract key fields (company name, basic account number, bank name, approval number, issue date, etc.) from corporate bank-account opening permit images. |
extract_driver_license | China Driver License | Extract key fields (name, gender, nationality, date of birth, license number, permitted vehicle class, first issue date, validity period, etc.) from Chinese motor-vehicle driver license images. Supports both main and supplementary pages. |
extract_business_license | Business License | Extract key fields (company name, unified social credit code, legal representative, registered capital, establishment date, business scope, registered address, etc.) from Chinese business license images. |
extract_passport_cn | China Passport | Extract key fields (Chinese name, romanized name, gender, date of birth, passport number, nationality, issue date, validity period, issuing authority, etc.) from PRC passport images. Foreign passports are not supported. |
extract_vehicle_license | Vehicle License | Extract key fields (plate number, vehicle type, owner, VIN, engine number, registration date, issue date, etc.) from Chinese motor-vehicle license images. Supports both main and supplementary pages. |
extract_org_code_cert | Organization Code Certificate | Extract key fields (organization name, organization code, legal representative, address, issue date, validity period, etc.) from organization code certificate images. For newly registered enterprises, use the Business License tool instead. |
extract_household_book | Household Register | Extract key fields (household number, household type, address, family member list including name, ID number and relationship to head of household, etc.) from Chinese household register (Hukou) images. Supports both index and individual pages. |
extract_hk_macao_permit | HK/Macao Travel Permit | Extract key fields (name, gender, date of birth, permit number, issue date, validity period, issuing authority, etc.) from Exit-Entry Permit for Travelling to and from Hong Kong and Macao images. |
Custom Extraction
In addition to the out-of-the-box tools above, MCP provides two fixed tools for working with custom extraction apps you create on the ADP platform:
| Tool Name | Title | Description |
|---|---|---|
list_custom_extract_apps | List Custom Extraction Apps | Read every page of the current user's extraction apps: 1406/1423/1424/1425, including unpublished apps. output_schema only represents published configurations and may be null. |
execute_custom_extract_app | Execute Custom Extraction App | Process a file using a specified custom document extraction app. Use list_custom_extract_apps first to obtain the app_id. |
Workflow: Call list_custom_extract_apps to browse available apps and get the target app_id, then call execute_custom_extract_app with the app_id and file to perform extraction.
Standalone Classification, Routed Extraction and Export
| Tool | Purpose |
|---|---|
list_classification_apps | Explicitly select the current user's 1426 classification apps and read every page |
classify_document | Return document-instance categories and original pages; synchronous by default, or create an async task with wait=false |
query_classify_task | Query only standalone classification async tasks |
extract_routed_document | Classify by candidate app names/descriptions and extract each document instance; synchronous by default, or async with wait=false |
query_routed_task | Query only routed extraction async tasks |
export_workflow_runs | Export workflow results when explicitly requested by the user, returning a temporary download link; restricted preview, no administrator role required |
For classification, configure a 1426 app in ADP, discover its app_id with list_classification_apps, then call classify_document. For routing, select 1425/1423/1424 candidates through list_custom_extract_apps and pass their IDs as extract_routed_document.app_ids; no classification app ID is needed.
Classification and routing accept only PDF/PNG/JPEG, at most 100 MB and 260 original pages, even when selecting a subset. model_params.pages contains distinct original pages starting at 1. Routing accepts 1–10 distinct app IDs; trimmed app names must also be unique ignoring case. A page may match multiple apps.
{
  "app_ids": ["your-1425-app", "your-1423-app"],
  "file": "https://files.example.com/materials.pdf",
  "file_name": "materials.pdf",
  "wait": false,
  "model_params": {
    "pages": [1, 2],
    "enable_highlight": true,
    "enable_field_value_translation": false,
    "enable_confidence": null
  }
}
For routing, the three per-call switches are inside model_params alongside pages, affecting every child app. Omission/null inherits each app setting; false disables it without saving a configuration or version. Single-app extraction places these switches at the top level.
Classification returns segments. Routing groups extraction_result by app, with each object_values entry representing one document instance and pages referring to the original file. Failed instances retain error alongside successful results. partial_success and failed set MCP isError=true while preserving complete structuredContent and the original message. All-unmatched input may still be success with empty results. A synchronous task_id identifies the call and does not create a queryable async task.
Exports are limited to runs the current account may access in the current tenant for the specified application_id. Supplying an ID does not grant access to another user's data.
report_mode | format | Selection and result |
|---|---|---|
merged (default) | excel/word/markdown/html/json | One combined file; omitted/null/empty run_ids select matching runs for the current user |
per_run | excel/word/markdown/html/json | One file per run in a ZIP; supports the same selection filters |
task_data | excel/json | Exactly one nonblank run ID; saved business data without attachments |
task_package | Explicit word/markdown/html required | Exactly one nonblank run ID; report and authorized attachments in a ZIP |
General exports select at most 200 runs, default to successful runs, and may include others with include_failed_runs=true; the row limit is 500000. node_ids, node_types, variable_filters (input variable dot paths), primary_key_variable and max_text_length apply to general export; the last defaults to 10000 and ranges from 1–30000. Task modes reject nonempty node/type/variable filters and require a finished task with retained exportable business data. Task locale is zh-CN/en-US, defaulting to the saved display language; it does not rerun extraction or retranslate field values and differs from the account-region selector accept_language.
The 200-run limit applies to runs included in export. When selecting all eligible history, skipped_runs and the corresponding total_runs can exceed 200 without exceeding the export limit.
{"application_id":"your-workflow-app","run_ids":["your-run"],"report_mode":"task_package","format":"html","locale":"en-US"}
Exports return file_id, download_url, filename, file_size, format, mode, run statistics and summaries. Link lifetime depends on deployment. Do not resubmit automatically when acceptance is uncertain.
Workflow Applications
| Tool Name | Description |
|---|---|
list_workflow_templates | Query official templates by name with search, offset and size. |
create_workflow_application_from_template | Create and publish an account application, or reuse the corresponding runnable application. |
upload_temporary_file | Use an account application_id with sharing_scope="application"; before directly running a template, use sharing_scope="user" and omit application_id. |
execute_workflow_app | Run a published account application, or directly run one of the three official templates as an alternative. Synchronous by default; use wait=false for an explicitly requested async run. |
query_workflow_run | Query a workflow by run_id, preserving its complete output and error. |
Supported template keys:
| Template | template_key | Fixed template ID |
|---|---|---|
| Accounts payable | finance_payable | wftp_app_n8q4v2m7x5p1r9t6c3a0b8d2 |
| Expense reimbursement | expense_reimbursement | wftp_app_h3k9s1v6p4x8q2m7c5t0a9r1 |
| Financial report extraction | financial_report_extraction | wftp_app_y6p2m8q4v1c9t3x7n5r0h2k6 |
Recommended: use the matching template to create and publish an application first, then upload and run using the returned account application_id. Creation does not require can_run=true in the template catalog. Repeated creation reuses an existing runnable application and preserves its template version.
Call create_workflow_application_from_template:
{"template_key":"financial_report_extraction"}
Successful data contains template_key, template_version, application_id, application_name, release_version_id, application_status="published" and can_run=true. Save the returned IDs. Then call upload_temporary_file:
{"chunk":"/path/to/report.pdf","application_id":"<created application_id>","sharing_scope":"application"}
Call execute_workflow_app using the upload response's download_url, file_name, content_type and optional file_size:
{
  "application_id":"<created application_id>",
  "files":[{"url":"https://files.example.com/report.pdf","name":"report.pdf","mime_type":"application/pdf"}]
}
For async runs, add "wait":false, save data.run_id, and call query_workflow_run with {"run_id":"<returned run_id>"}. A run is successful only when status="succeeded"; also inspect the output against the user's request. Do not use document task_id query tools for workflow runs. If a creation, upload or run response is uncertain, do not automatically resubmit.
Alternative: directly run a workflow template. When the user chooses this option, call execute_workflow_app with either template_key or one of the fixed template IDs above as application_id, never both. The run request automatically creates and publishes a corresponding runnable account application when needed, or reuses an existing one. No separate catalog, application-list or create call is needed. Do not pass release_version_id in template mode; an actual account application's ID still supports an explicit published version.
For a local file, first call upload_temporary_file with user scope so that the account application created or reused by the run can access the file:
{"chunk":"/path/to/report.pdf","sharing_scope":"user"}
Then use the returned file fields with execute_workflow_app:
{
  "template_key":"financial_report_extraction",
  "files":[{"url":"https://files.example.com/report.pdf","name":"report.pdf","mime_type":"application/pdf"}]
}
The equivalent target is "application_id":"wftp_app_y6p2m8q4v1c9t3x7n5r0h2k6" instead of template_key. Add "wait":false for asynchronous execution, then query the returned run_id in the same way. Uploads do not accept fixed template IDs: omit application_id with user scope, or create the application first and use its real account ID with application scope.
Workflow changes currently require the ADP website interface. Test and republish there before running the application through the API again. These tools support creating an application from an official template; custom workflow creation and workflow editing remain website operations.
The workflow tools accept accept_language and timeout_seconds. Use the same account region for creation, upload, execution and query: zh selects the China service and en selects the global service, or configure ADP_ACCEPT_LANGUAGE consistently.
Async task queries
| Tool Name | Title | Description |
|---|---|---|
query_parse_task | Query Async Document Parsing Task | Query the task_id returned by parse_document with wait=false, using GET .../app/doc/recognize/query/task/{task_id}. |
query_extract_task | Query Async Document Extraction Task | Query async IDs from preset invoice/card tools or execute_custom_extract_app, using GET .../app/doc/extract/query/task/{task_id}; excludes routed tasks. |
query_classify_task | Query Async Document Classification Task | Query only async IDs from classify_document, using GET .../app/doc/classify/query/task/{task_id}. |
query_routed_task | Query Async Routed Extraction Task | Query only async IDs from extract_routed_document, using GET .../app/doc/extract/routed/query/task/{task_id}. |
All four query tools return current status and available results. If unfinished, query again with the same tool. Select the endpoint from the creating tool; IDs cannot cross task types, even after a failed query. Use the same account region for creation and query. Workflow run_id uses query_workflow_run.
Parsing/single-app extraction queries replace query_task and get_result. Refresh your client's tool list after upgrading.
Tool Input Parameters
query_parse_task / query_extract_task / query_classify_task / query_routed_task
| Parameter | Type | Required | Description |
|---|---|---|---|
task_id | string | Yes | Task ID returned when creating an async task of the corresponding type |
accept_language | string | No | API region and response language matching task creation: zh or en |
Document Parsing & OOTB Extraction Tools
Common input parameters for out-of-the-box tools:
| Parameter | Type | Required | Description |
|---|---|---|---|
file | string | Yes | File URL or Base64-encoded content |
file_name | string | No | File name (with extension) |
with_rec_result | boolean | No | Return document parsing results, default true; high-speed custom extraction does not return them |
model_params | object or null | No | Capability-specific pages, scale, keep_content, disable_collaboration, page_task_timeout_seconds, card_type and enable_multi_ticket |
wait | boolean | No | Whether to wait synchronously for the result, default true |
timeout_seconds | integer | No | Synchronous wait timeout in seconds, default 300, range 1–900 |
extract_china_invoice additionally supports:
| Parameter | Type | Required | Description |
|---|---|---|---|
enable_invoice_verify | boolean or null | No | Enable (true) or disable (false) verification for this extraction only. Omission or null uses the saved app configuration without changing it. |
extract_global_invoice, extract_global_invoice_fast, and extract_sea_invoice_fast additionally support:
| Parameter | Type | Required | Description |
|---|---|---|---|
enable_multi_ticket | boolean | No | Split multiple invoices in one file into separate results, default true. Applies only to international and Southeast Asia fast modes without changing app configuration. |
enable_field_value_translation | boolean or null | No | Enable (true) or disable (false) field-value translation for this extraction only. Omission or null uses the saved app configuration without changing it. The target language follows accept_language or ADP_ACCEPT_LANGUAGE. |
extract_global_invoice_fast, extract_sea_invoice_fast and execute_custom_extract_app also accept top-level enable_highlight and enable_confidence: true/false overrides only this call; omitted/null inherits app settings. Translation is written separately to field_value_translation without replacing the original value. Defaults returned with confidence evaluation disabled are not evaluated scores.
Single-app model_params.pages does not have the classification/routing limit of 260 entries. Native XLSX/Markdown availability for classic extraction, 1425 and 1423/1424 depends on deployment and authorization; Base64 requires the correct file_name extension. Markdown has logical page 1 only. XLSX spreadsheet_billing and preview manifest fields are retained unchanged. 1425 sync/async always disables human collaboration; keep_content does not make it return parsing results. page_task_timeout_seconds controls waiting for per-page result preparation, not the entire extraction timeout.
For overseas multi-ticket results, tickets and the invoice_tickets/receipt_tickets grouped projection represent the same batch. Consume one projection to avoid double counting. The routed API does not repeat results as tickets.
upload_temporary_file
| Parameter | Type | Required | Description |
|---|---|---|---|
chunk | string | Yes | File to upload. Local file path, file:// URL, or Base64-encoded content |
application_id | string | No | Created account workflow application ID; required when sharing_scope="application". Fixed template IDs are not accepted for uploads. |
sharing_scope | string | No | application with a created account app ID, or user without an app ID before directly running a template; user also supports temporary document files |
accept_language | string | No | Account region and response language, zh or en |
timeout_seconds | integer | No | Request timeout in seconds, default 300, range 1–900 |
The response contains data.download_url, which can be passed directly to parsing or extraction tools as file.
execute_custom_extract_app
In addition to the parameters above:
| Parameter | Type | Required | Description |
|---|---|---|---|
app_id | string | Yes | Custom extraction app ID (obtained from list_custom_extract_apps) |
list_custom_extract_apps
Optional ai_function is 1406/1423/1424/1425; omission reads all these extraction capabilities without defaulting to 1425. Also accepts accept_language and timeout_seconds. Discovery fixes app_type=1, owner_only=true, published_only=false, reads every page, filters other capabilities and recalculates the returned total. published_version_id identifies a publication record; output_schema describes published business fields and may be null. Unpublished does not mean uncallable.
Parsing/extraction file input methods:
- URL: pass a link starting with
http://orhttps://asfile - Base64: pass Base64-encoded file content as
file(auto-detected when not a URL) - Local files: call
upload_temporary_filefirst, then pass the returneddata.download_urlto the parsing or extraction tool.
Sync vs Async:
wait=true(default): blocks until processing completes, returns the result directlywait=false: returns atask_idimmediately; usequery_parse_taskfor parsing orquery_extract_taskfor extraction to query status and results
Tool Output
upload_temporary_file Output
{
  "code": "success",
  "message": "",
  "tips": null,
  "data": {
    "id": "ade6dcfd9b9c11f1be34d85ed35661fd",
    "file_name": "invoice.pdf",
    "file_size": 123,
    "content_type": "application/pdf",
    "download_url": "https://adp.laiye.com/web/agentic_doc_processor/laiye/file/ade6dcfd9b9c11f1be34d85ed35661fd",
    "status": "success"
  }
}
| Field | Type | Description |
|---|---|---|
code | string | Business status code. Success is usually success |
message | string | Response message |
tips | string | null | Additional message |
data.id | string | File ID |
data.file_name | string | File name |
data.file_size | integer | File size in bytes |
data.content_type | string | MIME type |
data.download_url | string | Download URL. Pass this value to parsing or extraction tools as file |
data.status | string | File status, returned when available |
parse_document Output
{
  "task_id": "fabd7f0a4e7211f1bbc4d85ed35661fd",
  "status": 4,
  "message": "",
  "doc_recognize_result": [
    {
      "page_num": 1,
      "document_content": "Full text content of this page...",
      "document_details": [
        {
          "type": "Text",
          "text": "Paragraph content...",
          "position": [{"points": [{"x": 311, "y": 50}, {"x": 500, "y": 50}, {"x": 500, "y": 80}, {"x": 311, "y": 80}]}],
          "ocr_confidence": {
            "ocr_mean_confidence": 0.999,
            "ocr_min_confidence": 0.998,
            "is_overall_confidence": 1
          }
        },
        {
          "type": "Table",
          "text": "Column A\tColumn B\nValue 1\tValue 2",
          "position": [{"points": [...]}],
          "ocr_confidence": {...}
        },
        {
          "type": "Picture",
          "text": "https://adp.laiye.com/web/.../file/abc123",
          "position": [{"points": [...]}],
          "ocr_confidence": {...}
        }
      ]
    }
  ]
}
| Field | Type | Description |
|---|---|---|
task_id | string | Task ID |
status | integer | Task status code |
message | string | Status message |
doc_recognize_result | array | Per-page recognition results |
doc_recognize_result[].page_num | integer | Page number (1-indexed) |
doc_recognize_result[].document_content | string | Full text of the page in reading order |
doc_recognize_result[].document_details | array | Element-level details |
document_details[].type | string | Element type: Text, Table, or Picture |
document_details[].text | string | Text content; image URL for Picture type |
document_details[].position | array | Bounding box coordinates (4 corner points) |
document_details[].ocr_confidence.ocr_mean_confidence | float | Average OCR confidence (0–1) |
document_details[].ocr_confidence.ocr_min_confidence | float | Minimum OCR confidence (0–1) |
extract Tool Output
{
  "task_id": "91283e544e7111f18cd6d85ed35661fd",
  "status": 4,
  "message": "",
  "extraction_result": [
    {
      "field_key": "invoice_number",
      "field_name": "Invoice Number",
      "field_values": [
        {
          "field_value": "24VLT0591617",
          "field_confidence": 1.0,
          "references": []
        }
      ]
    },
    {
      "field_key": "line_items",
      "field_name": "Product Details",
      "references": [],
      "field_confidence": 1.0,
      "table_values": [
        [
          {
            "field_name": "Description",
            "field_key": "line_items_description",
            "field_values": [
              {
                "field_value": "TESLA MODEL 3",
                "field_confidence": 1.0,
                "references": "Description: TESLA MODEL 3"
              }
            ]
          }
        ]
      ]
    }
  ]
}
Regular field (no table_values):
| Field | Type | Description |
|---|---|---|
field_key | string | Machine-readable field identifier |
field_name | string | Human-readable field name |
field_values | array | Extracted values |
field_values[].field_value | string | The extracted value |
field_values[].field_confidence | float | Confidence score (0–1) |
Table field (has table_values):
| Field | Type | Description |
|---|---|---|
field_key | string | Table identifier |
field_name | string | Table name |
table_values | array[array] | 2D array: rows of cells, each cell has field_name, field_key, field_values |
How to distinguish: Field object contains table_values → table field; only field_values → regular field.
Async Response (wait=false)
{
  "task_id": "fabd7f0a4e7211f1bbc4d85ed35661fd",
  "status": "running"
}
Task Status Codes
The numeric states below apply to legacy parsing/single-app extraction. Standalone classification uses pending/running/success/failed; routing also has partial_success. Do not poll these using numeric states. Original states/results are preserved; failed or partially failed results add MCP isError=true.
| Status Code | MCP Status | Description |
|---|---|---|
| 0 | running | Unknown |
| 1 | running | Ready / Queued |
| 2 | running | Processing |
| 4 | success | Success |
| 5 | failed | Failed |
| 6 | failed | Cancelled |
Supported File Formats
Availability in this table depends on the selected app and deployment; standalone classification and routing strictly accept PDF/PNG/JPEG only.
| Format | Extensions | Notes |
|---|---|---|
.pdf | Supports both scanned and electronic | |
| Image | .jpg .jpeg .png .bmp .tiff | Supports camera photos |
| Word | .doc .docx | - |
| Excel | .xls .xlsx | - |
| PPT | .ppt .pptx | - |
Authentication
ADP MCP Server uses API Key authentication, passed via the ADP_API_KEY environment variable:
"env": {
  "ADP_API_KEY": "<YOUR-ADP-API-Key>",
  "API_SOURCE": "npm-mcp"
}
- API Key is available from the My MCP page in the ADP console
- Each API Key is bound to a single user and can only access that user's apps and data
- The API Key is passed only as an environment variable to the local process and never appears in request bodies or responses
API_SOURCEis sent to OpenAPI as theX-Api-Sourcerequest header; when omitted it defaults tonpm-mcp
FAQ
Q: Some card/certificate tools don't appear after connecting?
A: The tool list is dynamically generated based on your initialized apps. On first connection, the system automatically initializes all out-of-the-box apps. Refresh the tool list once initialization completes to see all available tools.
Q: A card tool returns "extraction failed"?
A: Make sure the uploaded file matches the tool type (e.g., use extract_id_card for ID card images, not extract_vehicle_cert). The file must be in a supported image or PDF format.
Q: How to handle timeouts?
A: The default timeout is 300 seconds (5 minutes). You can adjust it via the timeout_seconds parameter (max 900). For large files or complex documents, use wait=false for async mode and query results later using the task_id.
Q: How does MCP compare to ADP CLI / OpenAPI?
A: All three provide equivalent functionality — the difference is in the integration method:
| Method | Best For |
|---|---|
| MCP Server | AI clients (Claude Desktop, Cursor, etc.) — no code required |
| ADP CLI | Terminal, scripting, AI Skill integration |
| OpenAPI | Business system integration, backend service calls |
License
- MCP Server: Free to connect, provided as part of the ADP platform
- ADP Service: Cloud-based AI document processing, usage-based billing
Free tier: new users receive 100 free credits per month upon registration
Support & Contact
- API Docs: Open API Guide
- Product Manual: Cloud Operations Manual
- Email: mkt@laiye.com
- Website: Laiye
Build the Future of Agentic AI with ❤️ Copyright © 2026 [Laiye Technology (Beijing) Co., Ltd.] All rights reserved.