MindForge
Production-grade lifelong memory for AI agents — 4-tier memory model (sensory/short/long/permanent), knowledge graph, AES-256-GCM encryption, federated P2P memory sharing. Local-first, SQLite + FTS5, hybrid retrieval.
Documentation
MindForge
A local-first, production-grade memory system for AI agents.
Maintainer — Xiao Gu (小顾), born in 2008 · GitHub: opok-ops · 抖音: shidianduo3116 · 小红书: 4406811524 · Feedback: 2638895480@qq.com
MindForge gives AI agents a persistent, structured long-term memory: a four-tier lifecycle model, knowledge graphs, hybrid retrieval, end-to-end encryption, and MCP / CLI / REST interfaces. All data stays on your machine.




English · 中文文档 · Live Demo · Documentation · Discussions
Overview
Agent memory solutions that rely on cloud backends introduce latency, cost, and privacy trade-offs. MindForge takes the opposite approach: memory is computed and stored locally, encrypted at rest, and exposed through standard interfaces your existing agents already speak.
Key design decisions:
- Local-first. No cloud dependency. Storage runs on SQLite + FTS5 with WAL, a single file that moves with you.
- Structured memory. Four tiers (sensory, short-term, long-term, permanent) with promotion and decay driven by the Ebbinghaus forgetting curve.
- Retrieval quality. Six complementary retrieval paths fused into one ranked result, instead of a single vector index.
- Encryption by default. AES-256-GCM at rest with PBKDF2 key derivation; encrypted backups you can export and trust.
- Open interfaces. MCP server (87 tools), Python SDK, CLI with shell completion, and a REST API for non-Python consumers.
Quick Start
Install from source, then start writing and reading memories in minutes:
git clone https://github.com/opok-ops/MindForge.git
cd MindForge
pip install -e .
from mindforge import MindForge

m = MindForge(db_path="./data/memory.db", encrypted=False)
m.add("User prefers type-hinted Python code", category="preferences", importance="HIGH")
result = m.search("coding preferences")
print(result.chunks[0].content)
CLI:
MindForge add "User likes cats" --category preferences --importance HIGH
MindForge search "what does user like"
MindForge stats
Features
v6.0.0 — released 2026-10-31
- Multi-agent memory spaces — shared spaces with three-tier roles (owner / editor / reader), last-write-wins conflict resolution, and PRIVATE / STRICT privacy guardrails. Promoted from experimental to a supported capability; available through the
multi_agentfacade, CLIspace-*, MCPspace_*, and the v6 port registry (statusAVAILABLE). - 6G AI memory preview — four capabilities on the preview port, each replacing a former stub: parallel Preview Channels (isolated SQLite stores that never touch the stable database), context distillation (
distill_contextranks memories HIGH / MEDIUM / LOW under a token budget), incremental index statistics (write-time indexing with near-real-time recall metrics), and per-memory timelines (versions, evolutions, and audit trail). Available through CLIpreview-*, REST/api/preview/*, and MCPpreview_*. - Agent workflow toolkit — eight features covering the full memory lifecycle: chat-history import for cold start, timeline visualization, shareable skill packs, memory evolution, outcome-based learning, memory passports for cross-model migration, explainable principled forgetting, and follow-up tracking. Each is exposed consistently across CLI, REST, and MCP.
- v6 port registry —
v6_status()reports capability readiness;v6_port(capability)injects a ready-to-use instance (multi-agent adapter or memory preview), so callers can depend on ports instead of concrete modules.
Retrieval
- Six-way hybrid search — vector, FTS5, TF-IDF, fuzzy, query expansion, and cross-encoder reranking fused into a single ranked result set.
- Knowledge graph — automatic entity and relation extraction, path finding, and associative recall.
- Weighted recall — multi-factor scoring (coverage, importance, access frequency, time decay) instead of similarity alone.
Memory lifecycle
- Four-tier memory — sensory buffer, short-term, long-term, and permanent tiers with Ebbinghaus-based decay and periodic consolidation.
- Conflict detection — antonym pairs, attribute inconsistencies, and timeline conflicts, with automatic decay.
- Procedural memory (Cases → Skills) —
record_experience()stores agent success cases,distill_skills()turns them into reusable skill templates (persisted, restart-safe),skill_match()/skill_render()reuse them on new tasks with parameterized steps (v5.8.0). - Knowledge-graph pipeline —
auto_extract_graphhooks intoadd();extract_graph()draws entities/relations into a persisted graph (survives restarts),graph_related/graph_pathquery it, STRICT-privacy memories are never extracted (v5.7.9). - Reproducible embedding eval —
benchmarks/embedding_eval.pycompares hybrid / vector / FTS5 / TF-IDF on a fixed multilingual set with fixed seeds (Recall@5 / MRR@10 / NDCG@10); deterministicfakebackend runs without any model for CI baselines (v5.7.8). - Agent memory governance —
agent_pinfreezes decay and pins key memories,agent_forgetsoft-deletes with a reason,agent_decay_boostaccelerates forgetting, andexpire_memorycloses a fact's validity window (v5.7.7). - Conflict auto-reconcile —
reconcile_conflictscloses the stale side ofkeep_newer/keep_higher_importanceconflicts (Bi-temporal expiry, never deletes), and routesmerge/review_neededto human review (v5.7.7). - Connector framework — pluggable
json/csv/markdown/file/urlconnectors with a registry and SSRF guard; extensible viaregister_connector(v5.7.7). - Bi-temporal facts —
valid_from/valid_towindows with as-of queries (valid_at) andsupersedefact replacement that expires the old fact instead of deleting it, keeping full version history (v5.7.6). - Skill extraction — clusters memories into reusable slots, steps, and trigger words.
Privacy and security
- Privacy engine — four isolation levels (PUBLIC / INTERNAL / PRIVATE / STRICT) with fine-grained access control.
- At-rest encryption — AES-256-GCM with PBKDF2-SHA256 key derivation.
- Encrypted export / import —
export-json --passwordandimport-json --passwordproduce encrypted backups that remain unreadable even if the file leaks (v5.7.3). - GDPR toolkit —
gdpr-report/gdpr-export-all/gdpr-erasefor data portability and the right to be forgotten, with automatic backup before erasure (v5.7.6). - Memory health report —
memory_report()aggregates four-tier counts, TTL expirations, trash, conflict events, FTS consistency, database health, and encryption status, without exposing any plaintext memory content (v5.9.0). - Audit export —
export_audit()returns machine-readable audit entries (limit / since / actor filters) for GDPR and forensics; exposed asGET /api/audit(v5.9.0). - Privacy health check —
privacy_report()aggregates privacy-tier distribution, STRICT count, trash, audit events, encryption / key-file state, and the federated sharing surface, without exposing any plaintext memory content (v5.9.2). - Knowledge-graph export —
export_graph()exports entities and relations as structured JSON (schemamindforge-knowledge-graph/1.0, memory IDs attached, no plaintext) for external visualization, audit, and migration (v5.9.2). - Privacy-filtered graph export —
export_graph(max_privacy="INTERNAL")drops edges sourced from STRICT/PRIVATE memories (fail-closed, isolated nodes pruned); CLI--privacyand RESTGET /api/meta/graph?max_privacy=support the same filter (v5.9.3). - Unknown-privacy grouping —
privacy_report()buckets unknown/malformed privacy levels intounknown_privacy_countinstead of leaking raw level names into the distribution (v5.9.3).
Integration
- MCP server — 87 tools, drop into Claude Code, OpenClaw, or any MCP client.
- Federated memory — P2P sharing between agents with trust levels, ACLs, and conflict resolution.
- REST API — standard HTTP endpoints for non-Python applications.
- CLI — 200+ commands with bash / zsh / fish completion.
- Embedding backends — sentence-transformers, OpenAI, Ollama, or a custom HTTP endpoint.
Architecture
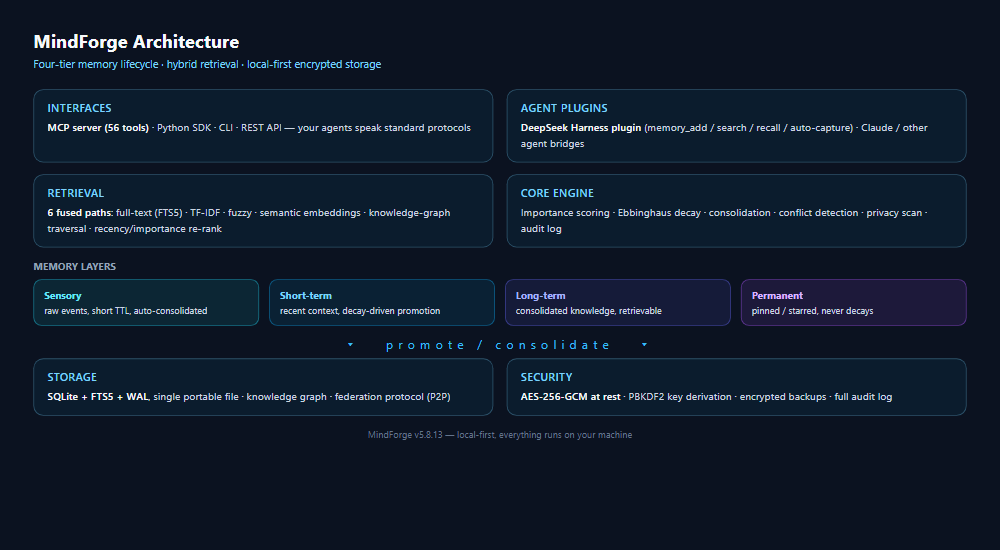
┌──────────────────────────────────────────────────────┐
│           MindForge v6.3.0            │
│  Cognitive Layer  Personality · KnowledgeGraph       │
│                   MemoryEvolution · FederatedMemory  │
├──────────────────────────────────────────────────────┤
│  Function Layer   RecallEngine · HybridSearch        │
│                   IntentRouter · ConflictDetector    │
│                   SkillExtractor · SessionFocus       │
├──────────────────────────────────────────────────────┤
│  Core Layer       Storage (SQLite+FTS5) · Index     │
│                   Encryption (AES-256-GCM) · Query  │
├──────────────────────────────────────────────────────┤
│  Adapter Layer    OpenClaw · Claude Code · MCP       │
│                   REST API · CLI · Python SDK        │
└──────────────────────────────────────────────────────┘
Four-Tier Memory Model
| Tier | Retention | Capacity | Purpose |
|---|---|---|---|
| Sensory | sec ~ min | ~50 | Input buffer, noise filtering |
| Short-term | hrs ~ days | ~100 | Working memory, active session |
| Long-term | wks ~ months | unlimited | Consolidated semantic memory |
| Permanent | forever | unlimited | Core knowledge, preferences, key experience |
High-value entries strengthen over time through consolidation; low-value entries decay naturally.
Performance
Benchmarked on i7-12700H / 32GB RAM / NVMe SSD / Python 3.12 / SQLite WAL.
| Operation | 1K | 10K | 100K |
|---|---|---|---|
| Write (plaintext) | 0.3 ms | 0.5 ms | 0.9 ms |
| Write (encrypted) | 0.8 ms | 1.2 ms | 2.1 ms |
| TF-IDF Search P50 | 4 ms | 12 ms | 38 ms |
| FTS5 Search P50 | 0.4 ms | 0.9 ms | 3.2 ms |
| Cross-Encoder Rerank P50 | 5 ms | 15 ms | 45 ms |
| Consolidate (100 entries) | 45 ms | 120 ms | 580 ms |
Retrieval quality (500 multi-domain memories, 50 annotated queries):
| Metric | TF-IDF | +FTS5+Fuzzy | +Cross-Encoder | +Query Expansion + Vector |
|---|---|---|---|---|
| MRR@10 | 0.62 | 0.71 | 0.82 | 0.85 |
| NDCG@10 | 0.60 | 0.69 | 0.80 | 0.84 |
| Recall@10 | 0.70 | 0.80 | 0.88 | 0.92 |
Integration
Claude Code
from adapters import ClaudeCodeAdapter

adapter = ClaudeCodeAdapter.from_env()
adapter.remember("User prefers concise code style", ["preferences"])
context = adapter.get_context("database optimization")
MCP Server
MindForge-mcp --db-path ./data/memory.db
REST API
MindForge serve --api --port 9000
# GET  /api/memories
# POST /api/memories
# GET  /api/search?q=...
# GET  /api/stats
OpenClaw
memory:
  adapter: MindForge
  adapter_config:
    db_path: ~/.MindForge/data/memory.db
    encrypted: true
    auto_consolidate: true
Security
- Encrypted databases: when a key file is present, set
MINDFORGE_PASSWORDso the process can unlock the store. This is required for the dsh-mindforge bridge and any non-interactive integration (MCP / REST API / scripts) accessing an encrypted store. - API authentication: if
MINDFORGE_API_KEYis configured, unauthenticated callers are treated asanonymousand can only reach PUBLIC memories. All read/write paths carry actor identity for authorization and audit. - Access logs are sanitized: search terms and memory IDs are stripped from logs.
- Upgrade note: v5.5.7 removed the experimental HMAC-XOR downgrade path (config flag
EXPERIMENTAL_HMAC_XOR, 即「降级加密」). Blobs created under that flag can no longer be decrypted — back up your database before upgrading if you enabled it.
See SECURITY.md for the full security policy.
Roadmap
- v6.0 — multi-agent memory spaces and the 6G AI memory preview, both promoted from experimental ports to supported capabilities, alongside an eight-feature agent workflow toolkit (released 2026-10-31)
- Vector database backend (Qdrant / Chroma)
- Web UI dashboard
- Plugin ecosystem
Documentation
License
MIT — Copyright (c) 2026 MindForge Project. If MindForge is useful to you, consider starring it on GitHub — it helps the project stay active and visible.