Gulliver
Dress rehearsal for agent SQL: cost preflight, scale lint with same-rows autofix, 1%/3%/10% sample rehearsal that predicts the full run, and budget-gated execution with receipts. DuckDB, Postgres, BigQuery, Snowflake.
Documentation
Gulliver
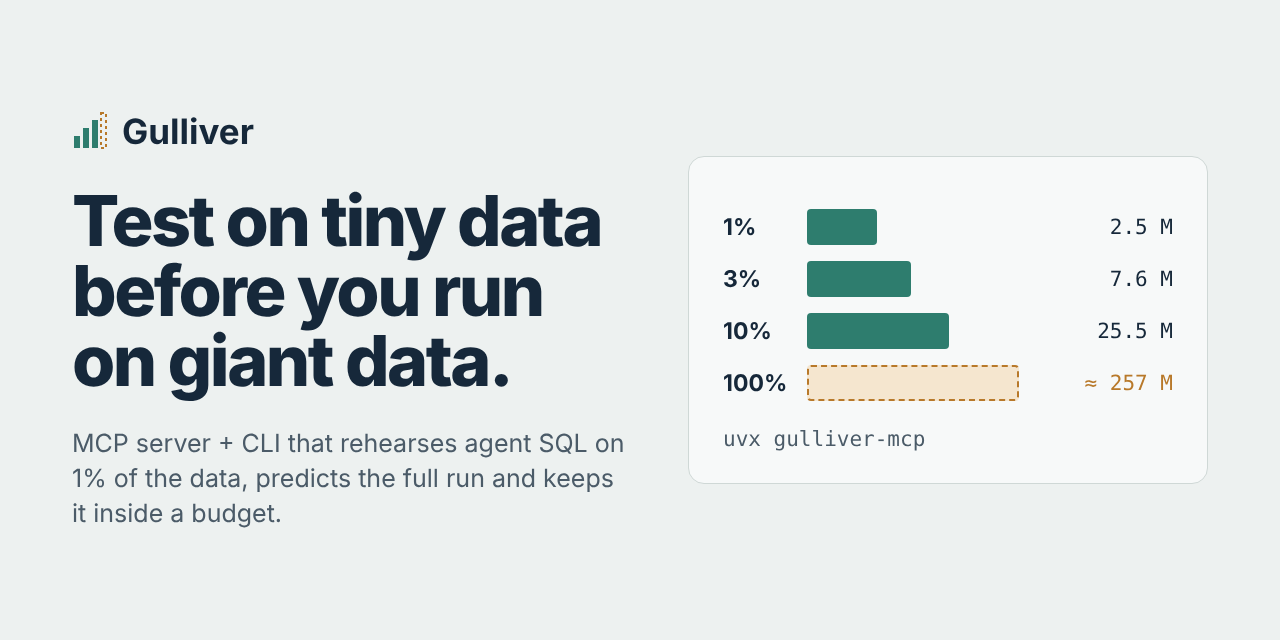
Test on tiny data before you run on giant data.
An open-source MCP server and CLI that gives AI agents a dress rehearsal for SQL: estimate the cost, fix the slow parts, rehearse on 1% → 3% → 10% of the data, predict what 100% will do, and only run the full query inside a budget.




Website · Quick start · Install · Auto-fix · Guards · CI · Compare · FAQ · Roadmap
Works with Claude Code, Codex, Cursor, Gemini CLI, Claude Desktop, VS Code, Windsurf and any MCP client, on DuckDB, Postgres, BigQuery and Snowflake.
New in 0.3.0: a read-only gate that also blocks side-effect functions, SQL hidden in strings and file access, with DuckDB sandboxed in the engine. A result guard for personal data and prompt injection in rows. A runaway guard for loops and per-agent budgets. Lint for CI (SARIF, pre-commit),
gulliver fix --verify,gulliver top, andgulliver reviewwith a GitHub Action. One breaking change: DuckDB can no longer read files outside the database folder and the current folder unless you allow them (details). See the changelog.
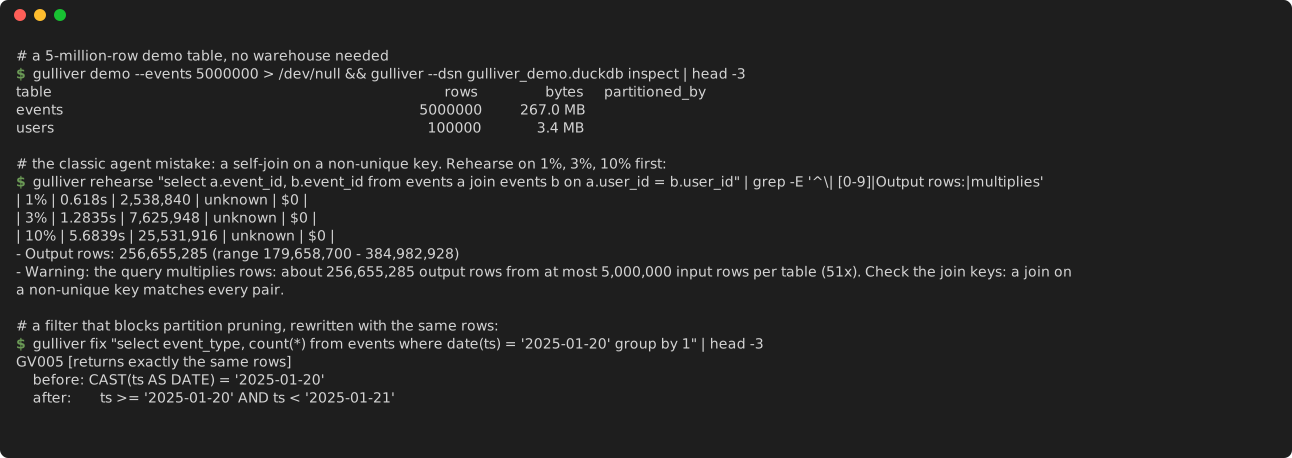
A real recording of the CLI on the demo database (script: docs/demo.sh).
In Gulliver's Travels, Gulliver visits Lilliput, a land of tiny people, and Brobdingnag, a land of giants. Gulliver does the same with your data: it tries your query in Lilliput first, and only walks into Brobdingnag when it knows what will happen there.
Why
Agents write SQL that works on a small table and breaks on a big one. They do not know that events has
5 billion rows, that a join multiplies rows, or that a forgotten partition filter scans every day since 2019.
Benchmarks score agents on is the answer right, never on what did it cost or does it still work at 100x.
One unlucky query can burn a monthly budget.
Gulliver sits between the agent and the warehouse:
| Step | Tool | What happens |
|---|---|---|
| 1 | gulliver_inspect | Which tables are big? Rows, bytes, partitions, columns. Metadata only, free. |
| 2 | gulliver_preflight | Bytes, rows and money before running, plus scale lint (15 rules), the read-only gate and the budget gate. When a safe rewrite exists, the answer already contains the fixed SQL (autofix). |
| 3 | gulliver_rehearse | Runs the query on 1%, 3% and 10% samples, fits a growth curve and predicts the full run with a confidence range. Catches joins that multiply rows. |
| 4 | gulliver_run | Runs the full query only inside the budget. Otherwise answers needs_rehearsal or needs_approval. The rows come back marked as untrusted data, with secrets masked and personal data flagged. |
| 5 | gulliver_receipt | Markdown proof for the human: what was estimated, rehearsed, approved and run, and predicted vs actual. |
Every answer has a status and a next_step, so even small models know what to do next.
Gulliver does not only say no. gulliver_fix rewrites the SQL for the agent and labels every change.
same (exactly the same rows) is only claimed when Gulliver has checked the column types on the connection;
everything else (assumes, nulls, changes) needs mode=all and says what may differ. With a connection it
estimates the old and the new query side by side, so nobody has to trust the saving blindly. With --verify it
also tests every rewrite on generated edge-case data and shows a counterexample when the rows differ.
Agents also fail in ways that have nothing to do with size. Gulliver guards those too (details in Guards for agents):
| Guard | Problem it solves |
|---|---|
| Read-only gate | "Only SELECT" is not read-only: a SELECT can stop sessions, run SQL hidden in a string, or read ~/.aws/credentials. Refused with codes GS001-GS004; DuckDB is also sandboxed in the engine. |
| Result guard | Rows with emails, card numbers or API keys land in the model's context, and text in a row can carry instructions. Secrets are masked, personal data is flagged, rows are marked untrusted: true. |
| Runaway guard | An agent re-runs the same expensive query in a loop, or one agent spends the team's daily budget. Loops are stopped, and each agent and session can get its own budget. |
And for the pipeline around the query (details in Pipeline tools and In CI and on pull requests):
| Tool | Problem it solves |
|---|---|
gulliver_impact | "If I change or drop this column, what breaks?" Column-level lineage over SQL models or a dbt manifest. |
gulliver_drift | Schema changed under you: columns removed, retyped or added since the last snapshot, plus the models they break. |
gulliver_diff | "Does my refactored / migrated / incremental model return the same rows?" Key-based data diff inside the engine, also across engines. |
gulliver_translate | SQL between DuckDB, Postgres, BigQuery and Snowflake, with warnings and an optional preflight on the target. |
gulliver_incremental | A model rebuilds everything every run. Is incremental safe, what is the SQL / dbt config, and how many rows does it skip? |
gulliver_check | Data quality in one cheap scan: unique keys, not null, accepted values, ranges, freshness, row-count jumps. |
gulliver_top | "Which repeated queries cost the most, and how do I fix them?" Query history grouped by shape, with same-rows fixes priced per month. |
gulliver_review | "Is this pull request safe to merge?" New lint, breaking changes, downstream impact and cost per month of the changed models. |
Quick start (2 minutes, no warehouse needed)
pip install gulliver-mcp
gulliver demo                       # creates gulliver_demo.duckdb with 5M events
export GULLIVER_DSN=gulliver_demo.duckdb

gulliver inspect
gulliver preflight "select country, count(*) from events e join users u on e.user_id = u.user_id group by 1"
gulliver lint "select * from events e, users u"           # GV003: join without a condition -> blocked
gulliver preflight "select * from read_csv('/etc/passwd')" # GS004: a file outside the allowed folders -> blocked
gulliver rehearse "select a.event_id, b.event_id from events a join events b on a.user_id = b.user_id"
The last one is the classic agent mistake: a self-join on a non-unique key. The rehearsal predicts the full result (about 255 million rows from a 5-million-row table) and warns that the query multiplies rows, before you run it.
| Sample | Runtime  | Output rows |
|--------|----------|-------------|
| 1%     | 0.4955s  | 2,538,840   |
| 3%     | 1.2153s  | 7,625,948   |
| 10%    | 4.0825s  | 25,531,916  |

Prediction for 100%: output rows 256,655,285 (range 179,658,700 - 384,982,928), confidence high
Warning: the query multiplies rows: about 256,655,285 output rows from at most 5,000,000 input rows per table (51x)
The real full run returns 254,966,150 rows.
Add --json to any command for machine-readable output. Exit codes: 0 ok, 1 error, 2 blocked,
3 needs rehearsal or approval, 4 a data check failed, so it also works as a CI check.
Install the MCP server
Gulliver is an MCP server (stdio or Streamable HTTP), published on PyPI and npm. Run it with uv, or through npx (which uses uv under the hood):
uvx gulliver-mcp --dsn path/to/warehouse.duckdb
npx -y gulliver-mcp --dsn path/to/warehouse.duckdb
Point it at a database with --dsn, or at a gulliver.toml with connections and budgets
(--config). No warehouse yet? Run gulliver demo and use gulliver_demo.duckdb.
Claude Code
claude mcp add gulliver -- uvx gulliver-mcp --dsn /abs/path/data.duckdb
Or install it as a plugin, which adds the MCP server and a skill with the rehearsal workflow:
/plugin marketplace add laaielichter/gulliver
/plugin install gulliver@gulliver
Claude Desktop, Cursor and Windsurf
Add this to the client's MCP config (claude_desktop_config.json, ~/.cursor/mcp.json or
~/.codeium/windsurf/mcp_config.json):
{
  "mcpServers": {
    "gulliver": {
      "command": "uvx",
      "args": ["gulliver-mcp", "--config", "/abs/path/gulliver.toml"]
    }
  }
}
VS Code
In .vscode/mcp.json:
{
  "servers": {
    "gulliver": {
      "type": "stdio",
      "command": "uvx",
      "args": ["gulliver-mcp", "--config", "/abs/path/gulliver.toml"]
    }
  }
}
Codex CLI
In ~/.codex/config.toml:
[mcp_servers.gulliver]
command = "uvx"
args = ["gulliver-mcp", "--config", "/abs/path/gulliver.toml"]
Gemini CLI
In ~/.gemini/settings.json, the same mcpServers block as for Claude Desktop above.
Any HTTP client or remote agent
gulliver-mcp --http --port 8765 serves http://127.0.0.1:8765/mcp (Streamable HTTP).
Without MCP: OpenAI and Gemini function calling
Every tool is also a CLI command with --json, and gulliver tools --format openai or --format gemini prints
ready-made function-calling definitions for the OpenAI or Gemini APIs.
More of MCP than tools
All 16 tool schemas take about 25.6 KB of the agent's context. gulliver-mcp --toolset core loads only the
8 query tools (about 10.9 KB); --toolset pipeline loads the pipeline tools; a comma list mixes sets and tool
names. The server also offers resources (gulliver://rules, gulliver://status, table metadata, receipts),
prompts (safe-query-loop, refactor-and-prove, make-incremental), progress during a rehearsal, and a typed
outputSchema on every tool.
A human can let approvals happen in the MCP client instead of the terminal: with
[approval] channel = "elicitation" in gulliver.toml, gulliver_run shows the human a form (the statement,
cost and SQL) before it answers needs_approval. It is off by default, and the agent cannot fill the form.
Turn it on only for clients that show these forms to a person. Details:
docs/features/mcp-native.md.
How it compares
Based on each project's public docs and READMEs in November 2026 (sources below). Gulliver's own numbers were measured in this repository. Open an issue if something here is wrong or out of date.
MCP servers that let agents query databases
| Gulliver 0.3 | cost-guard-mcp | Postgres MCP Pro | MCP Toolbox / BigQuery MCP | DBHub | Supabase MCP | Altimate Code | |
|---|---|---|---|---|---|---|---|
| Cost estimate before running | ✓ labeled exact (BigQuery), upper bound (Snowflake), heuristic (DuckDB, Postgres) | ✓ labeled precise / upper bound / heuristic | EXPLAIN only | – (row and time limits) | – | – | FinOps history (Snowflake-first) |
| Enforced budget | ✓ per query, day, bytes, runtime, agent, session | ✓ per call | time limit | – | rows, timeout | – | – |
| Rehearse on samples, predict the full run | ✓ | – | – | – | – | – | – |
| Auto-fix with a same-rows guarantee | ✓ checked against column types, tested with --verify | – | – | – | – | – | anti-pattern rules, no same-rows label |
| Human approval outside the agent | ✓ CLI, or a form in the MCP client (opt-in) | – | – | – | – | – | for writes |
| How read-only is enforced | parser + function and file denylist (GS001-GS004), engine sandbox on DuckDB, read-only session | one read-only statement | read-only transaction + parser | read-only tool / IAM | keyword allowlist | a real read-only database user (strongest) | read-only mode |
| Personal data / prompt injection in results | ✓ mask or flag, untrusted envelope, injection scan (patterns) | – | – | – | – | results wrapped with a warning | PII detection before running |
| Loop and runaway detection | ✓ | – | – | – | – | – | – |
| Index tuning, health checks | – | – | ✓ | Postgres observability tools | opt-in health check | – | – |
| Lineage, data diff, drift, incremental, quality checks | ✓ | – | – | – | – | – | lineage and many more tools |
| Engines | DuckDB, Postgres (tested in CI); BigQuery, Snowflake (beta, tested with fakes) | BigQuery, Snowflake, Databricks | Postgres | many | Postgres, MySQL, MariaDB, SQL Server, Oracle, SQLite | Supabase Postgres | about 10 warehouses |
| Tool schema in the agent's context | 16 tools, 25.6 KB; --toolset core 10.9 KB | 4 tools | 9 tools | ≈19k tokens for 28 tools (measured by DBHub) | ≈1.4k tokens (its own claim) | ≈19k tokens (measured by DBHub) | 100+ tools |
| Open source | ✓ MIT | ✓ MIT | ✓ MIT | ✓ | ✓ | ✓ | ✓ MIT |
SQL in CI and on pull requests
| Gulliver 0.3 | SQLFluff | Squawk | dbt-costgate | Recce | Datafold | |
|---|---|---|---|---|---|---|
| Knows table size, partitions and cost | ✓ with a connection | – | – | BigQuery bytes | – | – |
| SARIF / PR annotations | ✓ SARIF, GitHub, GitLab, JUnit | ✓ SARIF, GitHub, GitLab | ✓ GitHub | Markdown comment | PR comment | PR comment |
| Inline ignores, per-rule severity | ✓ | ✓ | ✓ | – | – | – |
| Autofix that keeps the same rows | ✓ same-rows only, checked by re-parsing | style fixes | – | – | – | – |
| Cost change per PR | ✓ BigQuery exact, other engines estimated | – | – | ✓ BigQuery | – | – |
| Row growth (fan-out) per PR | ✓ with --rehearse | – | – | – | – | – |
| Downstream impact | ✓ column-level, SQL models and dbt | – | – | – | ✓ lineage diff | ✓ including BI tools |
| Data diff | ✓ CLI, also across engines | – | – | – | ✓ two builds | ✓ |
| Price | free | free | free | free | open source + paid cloud | paid |
Where others are ahead today: Postgres MCP Pro does index tuning and health checks; a real read-only database user (as Supabase uses) is a stronger guarantee than any parser; SQLFluff checks style and many more dialects; Recce and Datafold diff two real builds and Datafold follows lineage into BI tools; DBHub's tool schema is much smaller. Gulliver has no Databricks or ClickHouse engine yet, and BigQuery and Snowflake have only been tested against fakes.
What Gulliver does not do: run your pipelines, replace dbt, or give you a hosted service.
Sources
cost-guard-mcp · Postgres MCP Pro · MCP Toolbox · BigQuery MCP · DBHub and its schema-size review · Supabase MCP and defense in depth · Altimate Code · SQLFluff releases · Squawk · dbt-costgate · Recce · Datafold
Engines
| Engine | Estimate before running | Sampling | Money model | Status |
|---|---|---|---|---|
| DuckDB (files, Parquet, CSV, in-memory) | EXPLAIN + metadata (heuristic) | TABLESAMPLE system/bernoulli, seeded | free (time is the budget) | tested in CI |
| BigQuery | dry run: exact bytes | TABLESAMPLE SYSTEM | on-demand $/TiB, plus a hard maximum_bytes_billed cap | beta, tested with fakes |
| Snowflake | EXPLAIN USING JSON: bytes and partitions (upper bound) | SAMPLE SYSTEM ... SEED | warehouse credits x runtime | beta, tested with fakes |
| PostgreSQL | EXPLAIN (FORMAT JSON) (heuristic), partition-aware sizes | TABLESAMPLE ... REPEATABLE | self-hosted (time and bytes are the budget) | tested in CI against a live Postgres 16 |
Install the drivers you need: pip install "gulliver-mcp[bigquery]", [snowflake], [postgres] or [all].
Every estimate says how much to trust it: exact, upper_bound or heuristic. A heuristic is never called exact.
Configuration
Copy gulliver.example.toml to gulliver.toml:
default_connection = "local"

[connections.local]
engine = "duckdb"
path = "warehouse.duckdb"

[connections.bq]
dsn = "bigquery://my-project?location=EU"
dataset = "analytics"
price_per_tib_usd = 6.25

[budget]
max_query_usd = 1.00        # hard stop for one query
approval_over_usd = 0.25    # above this a human runs `gulliver approve <receipt_id>`
rehearse_over_usd = 0.10    # above this a rehearsal is required first
day_usd = 10.00             # total per day (local ledger)
max_runtime_s = 900
max_output_rows = 200       # rows handed back to the agent
session_usd = 3             # per agent session (optional)
agent_day_usd = 5           # per agent per day (optional)
The example file also shows the settings for the read-only gate (allowed_paths, allow_remote,
allow_functions), the result guard (policy), the runaway guard, [lint], [review] and [approval].
A read-only Postgres role
Gulliver refuses writes itself, but a role that can only read is a good second layer. Run this once as an admin
and put gulliver_ro in the DSN:
CREATE ROLE gulliver_ro LOGIN PASSWORD 'change-me';
GRANT CONNECT ON DATABASE app TO gulliver_ro;
GRANT USAGE ON SCHEMA public TO gulliver_ro;
GRANT SELECT ON ALL TABLES IN SCHEMA public TO gulliver_ro;
ALTER DEFAULT PRIVILEGES IN SCHEMA public GRANT SELECT ON TABLES TO gulliver_ro;  -- tables created later
ALTER ROLE gulliver_ro SET statement_timeout = '15min';           -- the server stops runaway queries too
ALTER ROLE gulliver_ro SET default_transaction_read_only = on;
Or skip the file: GULLIVER_DSN, GULLIVER_MAX_QUERY_USD, GULLIVER_DAY_USD and friends.
Credentials never go in the config: Gulliver uses each engine's own environment variables and credential chains
(Google ADC, SNOWFLAKE_PASSWORD, PGPASSWORD, ...). The agent only ever sees connection names.
Safety model
- Read-first. Only
SELECT(andWITH ... SELECT) runs by default.DELETE,UPDATE,DROP,TRUNCATE,ALTER,MERGE, several statements at once and unparsable SQL are refused by a parser, not a regex. - A SELECT is not automatically safe. Functions with side effects (
pg_terminate_backend,set_config,nextval), SQL hidden in a string (dblink_exec, DuckDBquery(), BigQueryEXTERNAL_QUERY) and file or URL access (pg_read_file,read_csv('~/.aws/credentials')) are refused with codes GS001-GS004, anywhere in the statement. - DuckDB is sandboxed in the engine. Every DuckDB connection runs with
allowed_directoriesset to the database folder and the current folder (orallowed_paths), external access off, extension auto-loading off and the configuration locked, so the agent cannotSETit back. For Postgres, BigQuery and Snowflake the parser is Gulliver's only check, so also use a read-only role.gulliver selftest securityruns the bypass test set that ships with Gulliver (151 cases) and checks the sandbox live. - Writes need two keys.
CREATE TABLE ... AS SELECTandINSERT ... SELECTrun only when the call saysallow_writeand a human setallow_write = trueon that connection. Rehearsals never write. - Budgets fail closed. Over the per-query, per-day, per-session, per-agent, bytes or runtime limit means
block. Money above the approval limit needsgulliver approve <receipt_id>, a CLI command for humans that is not exposed as an MCP tool (or, when the human turned it on, a form in the MCP client that the agent cannot fill). - Rows are data, not instructions. Run results are marked
untrusted: true, secrets are masked, personal data is flagged, and text that reads like instructions to an AI is listed indata_warnings. - Engine-side caps where they exist: BigQuery
maximum_bytes_billed, Snowflake and Postgres statement timeouts, a DuckDB interrupt timer. - Local state only. Receipts, the spend ledger and approvals live in
./.gulliver/as JSON, hash-chained sogulliver audit verifycan detect edits. No telemetry.
The threat model is in SECURITY.md; the full list of what the gate refuses is in docs/features/security.md.
Breaking change in 0.3.0. DuckDB connections can no longer read files outside the database folder and the current folder, read remote URLs, or auto-load extensions. If you read Parquet or CSV files elsewhere, add the folder to
allowed_paths(or the bucket toallow_remote) on the connection ingulliver.toml. When the database folder or the current folder is/, your home folder or above it, it is left out of the default; setallowed_pathsthen.sandbox = falseturns the engine sandbox off (the parser still checks). Queries that call the refused functions getblock;allow_functionslifts that per connection.
How the prediction works
Each rung measures runtime, output rows and (where the engine reports it) bytes. Gulliver fits
metric = a * fraction^k in log-log space and reads off the value at 100%.
k ≈ 1: grows with the data (scans, filters, key joins against a full table).k ≈ 0: flat (aggregations). Group counts saturate, so grouped results are capped by what was observed and the planner estimate.k > 1.3: grows faster than the data: a big sort, or (with--sample all) a join between two sampled sides that multiplies rows. Flagged. In the default mode a multiplying join keepsk ≈ 1and is flagged by size instead: output much larger than the biggest input table.
Runtime first subtracts the fixed per-query overhead (measured with SELECT 1). Confidence is high, medium
or low, with a range of x0.7-1.5, x0.5-2 or x0.25-4. After a real run, the receipt shows predicted vs actual.
By default only the largest table is sampled and the others stay complete, which keeps key joins honest.
When the query reads that table more than once (a self-join, an IN (SELECT ...) on the same table, a CTE used
twice), only the first occurrence is sampled and the others are read in full on every rung. Two samples of one
table drawn with the same seed would hold the same rows, so every row would meet itself and small rungs would come
out too big. With one side sampled the output grows linearly and the prediction stays unbiased; the price is a full
read of the other side per rung. A result much larger than the biggest input table is flagged as a join that
multiplies rows. On the 5M-row demo self-join, five seeds predicted 252M-257M rows against 254,966,150 real ones.
--sample all samples every table and every occurrence, each with its own seed. That is cheaper, but a join
between two sampled sides grows with fraction² and the noise of both samples multiplies, so those predictions get
low confidence. When a table is read more than once, --method auto uses row (bernoulli) sampling. When the
smallest rung reads fewer than 2,000 rows, the range is widened one level. For BigQuery the money prediction uses
the exact dry-run bytes of the full query.
Limits, honestly: block (system) sampling is cheap but can be skewed on clustered data; use --method bernoulli
when that matters. On DuckDB a system sample takes whole 2,048-row vectors and is not repeatable even with a seed,
so --method auto always uses bernoulli on DuckDB (a local scan costs nothing); on BigQuery and Snowflake it keeps
the cheap system sample for tables of a million rows or more. Extrapolating 10x always has uncertainty; Gulliver shows it instead of hiding it. Databricks,
ClickHouse and Spark are not supported yet.
Pipeline tools
These reuse the same connections, budget gate and receipts. Every query they run is generated, parsed, estimated and gated like your own queries.
Impact: what breaks if a column changes
gulliver impact raw.events.amount --models models/ # or --manifest target/manifest.json
Changing raw.events.amount affects 4 model(s):
  stg_events: amount  <- raw.events.amount
    fct_revenue: revenue  <- stg_events.amount
    user_ltv: ltv  <- stg_events.amount
      country_report: revenue  <- fct_revenue.revenue
Plain *.sql files and dbt models ({{ ref() }}, {{ source() }}, {{ config() }}, {% if %}) both work.
Columns used only in filters or joins are reported too, and SELECT * models are flagged because their shape
follows the source. gulliver lineage --models models/ prints the whole graph.
Drift: schema changes since last time
gulliver snapshot                          # remember tables, columns and row counts
gulliver drift --models models/            # later: what changed, and which models it breaks
gulliver drift --save                      # accept the new schema
Removed and retyped columns are warn and are mapped to impacted models; row counts that move more than 20%
are listed too.
Diff: prove two queries return the same rows
gulliver diff --left "select * from fct_orders" --right "select * from fct_orders_v2" --key order_id
gulliver diff --left orders --right orders --key id -c postgres_prod --right-connection snowflake_new
Each side is reduced inside its engine to 256 buckets of (row count, sum of MD5 row hashes) keyed by the key's hash, so it scales to billions of rows and costs about one scan per side. Only buckets that differ are opened (with a finer second pass when they are big) to list keys that are missing, extra or changed. MD5 is the same on every engine, so you can diff across engines; values are compared as text, so cast or round in your queries where engines format numbers or timestamps differently. Use it after a refactor, a migration or an incremental switch.
Translate: SQL between dialects
gulliver translate --from snowflake --to bigquery -f model.sql
gulliver translate --from duckdb --to postgres --check -c pg "select ..."   # also preflight on the target
Functions the translator does not know are copied as-is and listed as warnings, so nothing is silently wrong.
Incremental: stop rebuilding everything
gulliver incremental -f models/user_ltv.sql --time-column ts --unique-key user_id --period 1d
| Strategy | When | What it generates |
|---|---|---|
append | no aggregation | read only rows newer than the target's max (merge on unique_key for late updates) |
partition_overwrite | grouped by a time grain | dbt microbatch config: recompute the recent periods (+ lookback) |
merge_recompute | grouped (or windowed) by an entity key | recompute only the keys that got new rows, merge on the key |
not_safe | LIMIT, totals over everything, windows without PARTITION BY | keeps the full rebuild and says why |
It also measures the saving on the real source ("each run would read about 172,800 of 5,000,000 rows, 96.5% fewer")
and, on billed engines, compares dry-run bytes, telling you when you need to partition or cluster the source to
turn fewer rows into less money. Prove the result with gulliver diff.
Check: data quality in one scan
gulliver check events --unique event_id --not-null user_id,amount \
  --accepted "event_type=view|click|cart|buy" --range "amount=0:10000" --fresh ts=24h --max-change 30
All checks become one aggregate query (one scan), budget-gated like any other. Status fail (exit code 4)
when a check fails, so it drops into CI or an orchestrator. Row-count history is kept per target, so
--max-change catches a load that suddenly lost half its rows.
Top: the most expensive repeated queries
gulliver top                                # the connection's own query history
gulliver top --source csv:history.csv --days 30
It reads Gulliver's receipts, pg_stat_statements, BigQuery JOBS_BY_PROJECT, Snowflake QUERY_HISTORY or a
CSV/JSONL export, groups the queries by shape (literals become ?), and ranks them by cost or runtime. The top
groups get lint, a rewrite that returns exactly the same rows, and a saving per month labeled exact (both
estimates are BigQuery dry runs) or heuristic. Repeated aggregates that could read a summary table are listed
too. Reading the history is a query like any other, so it goes through the budget gate. Details and limits:
docs/features/top.md.
Auto-fix
gulliver fix "select event_type, count(*) from events where date(ts) = '2025-01-02' group by 1"
GV005 [returns exactly the same rows]
  before: CAST(ts AS DATE) = '2025-01-02'
  after:  ts >= '2025-01-02' AND ts < '2025-01-03'
  why:    Filters the raw column ts by range, so partitions, indexes and min/max statistics can skip data. ts is TIMESTAMP, so the rows are the same.
| Rewrite | Rule | Guarantee | Default |
|---|---|---|---|
DATE(ts) = d, ts::date, TO_DATE(ts), DATE_TRUNC(day/month/quarter/year, ts), YEAR(ts), EXTRACT(YEAR ...) with =, <, <=, >, >=, BETWEEN → a range on the raw column | GV005 | same when the connection shows the column is a DATE or a TIMESTAMP without time zone | yes |
| the same, when the column type is unknown | GV005 | assumes (same rows only if it is such a column) | mode=all |
a.x NOT IN (SELECT y ...) → NOT EXISTS | GV012 | nulls: same rows unless the subquery returns NULL | mode=all |
COUNT(DISTINCT x) → approximate distinct count | GV007 | changes (approximate) | mode=all |
UNION → UNION ALL | GV009 | changes (keeps duplicates) | mode=all |
unbounded SELECT → LIMIT n | GV002 | changes (fewer rows) | mode=all |
same is a promise, so Gulliver keeps it narrow. It never rewrites a date filter on text columns,
TIMESTAMP WITH TIME ZONE (a day can start twice when the clocks change at midnight), intervals, TRY_ and
BETWEEN SYMMETRIC variants, filters with a time-zone or format argument, or periods that run past year 9999.
A column only counts as typed when it clearly comes from one table with metadata, not from a CTE or subquery
that could redefine it. Every same rewrite is tested against real data: DATE and TIMESTAMP columns, NULLs,
infinity, the last microsecond of a day and leap days.
What it will not do: guess a date range for a missing partition filter (GV004) or a join key for a
cartesian join (GV003). Those need a decision, so they stay in remaining.
Where it pays off: Postgres cannot use a plain index or range partitions on ts for ts::date = ..., and
BigQuery, Snowflake and Parquet readers prune best on the raw column. DuckDB already optimizes this case on its
own tables, so there the estimate stays the same.
Test every rewrite: --verify
Labels are reasoning; --verify adds evidence. It runs the original and each rewrite on small generated tables
full of the data that breaks rewrites (NULLs, duplicates, date boundaries, infinity, daylight-saving jumps) in a
private in-memory DuckDB, and shows the rows when they disagree, shrunk to a repro you can paste:
$ gulliver fix --mode all --verify "select o.id from orders o where o.customer_id not in (select customer_id from blocked)"
GV012 [same rows unless a NULL is involved (in the subquery, or in the outer column)]
  tested: rows differ in 112 of 200 generated cases
  repro:  CREATE TABLE "orders" ("id" INTEGER, "customer_id" INTEGER);
          INSERT INTO "orders" VALUES (0, NULL);
          ...
A test is not a proof, so labels never move up: an assumes change with no counterexample stays assumes. A
counterexample against a same rewrite drops that change and says so (that would be a Gulliver bug). It reads
none of your data and costs nothing. gulliver_preflight runs a quick version on the autofix it hands over.
Details: docs/features/verify.md.
Guards for agents
These run on every query, with no extra tool call. The settings live in gulliver.toml, so only the human
can change them.
Read-only gate
$ gulliver preflight "select * from read_csv('/etc/passwd')" --json
  "status": "block",
  "statement": {"kind": "block", "code": "GS004",
                "reason": "GS004 file-access: read_csv() reads '/etc/passwd', which is outside the allowed folders (/home/me/project). ..."}
| Code | Refuses |
|---|---|
GS001 server-control | pg_terminate_backend, pg_reload_conf, SYSTEM$CANCEL_QUERY, Snowflake SYSTEM$ functions not known to be read-only |
GS002 session-state | set_config, advisory locks, nextval/setval, large-object writes, SELECT ... FOR UPDATE |
GS003 dynamic-sql | dblink*, query_to_xml*, DuckDB query / query_table / postgres_query, BigQuery EXTERNAL_QUERY |
GS004 file-access | pg_read_file, lo_import, DuckDB read_text, getenv, http_get; any DuckDB path or URL outside the allowed folders, hidden files (.env, .gulliver/, also as a glob), ../ and symlinks that lead out |
Names are matched in every part of the statement (CTEs, subqueries, UNION branches, the SELECT of a write),
after removing quotes, schemas and escapes. On top of that, DuckDB runs in an engine sandbox (see the
Safety model). It is a denylist plus a path allowlist, not a proof: functions defined in the
database can call anything. Settings per connection: allowed_paths, allow_remote, allow_functions,
sandbox. Details: docs/features/security.md.
Result guard: personal data, untrusted rows and output size
Every gulliver_run preview is checked before the agent or the receipt on disk sees it:
- Sensitive columns by name (
email,iban,card_number,password,api_key, Dutch names too), through your SQL (aliases, CTEs,SELECT *, a whole row as one value), and by validated value patterns (email, phone, IBAN mod-97, Luhn card numbers, BSN 11-check, IP, JWT, API-key shapes). - Untrusted envelope. The result has
untrusted: true. Text that reads like instructions to an AI ("ignore previous instructions",gulliver_*tool names, hidden Unicode, base64) is listed ininjectionanddata_warnings. - Output size. Long cells are cut (
max_cell_chars, default 1,000) and a preview overmax_output_chars(default 50,000) keeps fewer rows plus acolumn_summary, so one wide result does not fill the context.
By default secrets are masked and personal data is shown but flagged (status: warn), so existing queries keep
returning the same values. A policy per connection can allow, warn, mask, hash, last4 or deny by
kind, category or column; deny blocks at preflight. gulliver inspect --sensitive lists the columns that look
sensitive, and lint rule GV014 flags them without a database. This is a mitigation, not a data-loss prevention
product: the injection scan uses patterns, so the agent must still treat rows as data. Details:
docs/features/guard.md.
Runaway guard: loops, per-agent and per-session budgets
| Guard | Default | When it trips |
|---|---|---|
max_repeats / repeat_window_min | 5 runs / 30 min | the same query runs again on tables that did not change: block, reason loop, with the last result in cached (free). When Gulliver cannot tell if the data changed: needs_approval, reason repeat |
velocity_usd / velocity_window_min | $2 / 10 min | one agent or session spends faster than this: needs_approval, reason velocity |
session_usd | off | one session spent its budget: block, reason session_budget |
agent_day_usd | off | one agent spent its budget for today: block, reason agent_budget |
Cheap repeats (under $0.01 and under 1 GB) never count as a loop. The agent comes from MCP clientInfo,
--agent or GULLIVER_AGENT (set by the human, it wins). Names are self-reported, so per-agent budgets are
accounting, not a security boundary; the per-query and per-day limits always apply. Queries are tagged in the
warehouse (Postgres application_name, Snowflake QUERY_TAG, BigQuery job labels), gulliver spend --by agent
(or day, table, session, task) shows who spent what, and gulliver audit verify checks the hash chain over
the ledger, receipts and approvals. Details:
docs/features/runaway.md.
In CI and on pull requests
Lint every SQL file
gulliver lint models/ queries/                          # every *.sql file, dbt Jinja included, with line:col
gulliver lint models/ --format sarif -o gulliver.sarif  # GitHub Code Scanning; also github, gitlab, junit, json
gulliver lint models/ --fail-on warn                    # exit 2 on warnings too (default: errors)
gulliver fix --check models/ -c warehouse               # exit 2 when a same-rows rewrite exists
gulliver fix --write models/ -c warehouse               # apply only same-rows rewrites, in place
gulliver rules                                          # every rule with its severity and autofix
Accept a pattern on purpose with -- gulliver: ignore GV001 reason (or ignore-file); a typo in the rule list
ignores nothing and is reported as GV901. Rules, severities and excludes go in [lint] in gulliver.toml.
A pre-commit hook ships with the repo:
repos:
  - repo: https://github.com/laaielichter/Gulliver
    rev: main            # or a release tag
    hooks:
      - id: gulliver-lint
      - id: gulliver-fix
        args: [--dsn, warehouse.duckdb]   # column types are needed to prove same-rows rewrites
Fixes are applied as small text edits (comments, line endings and Jinja stay) and are only accepted when the edited statement re-parses to exactly the rewritten tree. Details: docs/features/lint-ci.md.
gulliver review and the GitHub Action
gulliver review --models models --base origin/main                        # lint + change type + impact
gulliver --dsn bigquery://my-project review --models models --rehearse    # + cost per month and row growth
gulliver review --manifest-base prod/manifest.json --manifest-head target/manifest.json
For every changed model it reports new lint, the change type (cosmetic, non_breaking, breaking), the
downstream models that use a removed or changed column, the scan and money per run and per month before vs
after, and with --rehearse a superlinear flag when output rows now grow faster than the data. A [review]
policy maps the flags to ok, warn or block (exit code 2). A missing base ref or base manifest blocks instead of
reviewing everything.
on: pull_request
permissions: { contents: read, pull-requests: write }
jobs:
  review:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v4
        with: { fetch-depth: 0 }
      - uses: laaielichter/Gulliver@main   # pin a release tag or commit
        with:
          models: models
          # dsn: bigquery://my-project     # cost estimates; credentials come from the job env
The action posts one PR comment and updates it on every push, writes the job summary, and fails the job on
block. Classification is static, so a new LEFT JOIN on a unique key is still called breaking; prove it with
gulliver diff. Details: docs/features/review.md.
Scale lint rules
| Rule | Name | Severity |
|---|---|---|
| GV001 | select-star | warn |
| GV002 | unbounded-output | warn |
| GV003 | cartesian-join | error (no condition) / warn (CROSS JOIN) |
| GV004 | missing-partition-filter | error |
| GV005 | function-on-filter-column | warn |
| GV006 | order-without-limit | warn |
| GV007 | exact-count-distinct | info |
| GV008 | non-equi-join | warn |
| GV009 | union-distinct | info |
| GV010 | scalar-subquery-in-select | info |
| GV011 | window-without-partition | warn |
| GV012 | not-in-subquery | info |
| GV013 | leading-wildcard-like | info |
| GV014 | sensitive-column-in-output | info (personal data, masked secret) / warn (unmasked secret) |
| GV015 | fan-trap | warn |
| GV016 | order-by-random | warn |
| GV900 | parse-error (file lint only) | warn |
| GV901 | unused-ignore (an unreadable or unused gulliver: ignore) | warn |
gulliver lint works without any database; gulliver rules prints the list with descriptions. GV015 flags
SUM, AVG or COUNT of a column from the one side of a join like orders.id = order_items.order_id, which
repeats each order once per item; it only fires in that naming pattern, to keep false alarms rare.
The read-only gate uses its own codes. A GS finding is always a block with the code in statement.code:
| Code | Name | Refuses |
|---|---|---|
| GS001 | server-control | functions that stop sessions or change the server |
| GS002 | session-state | functions that change settings, locks or sequences, and FOR UPDATE |
| GS003 | dynamic-sql | functions that run SQL text the parser never sees |
| GS004 | file-access | file and URL readers outside the allowed folders, hidden files, environment variables |
CLI reference
gulliver status                       connections, budget, spend today (and your own, under caller)
gulliver inspect [TABLE] [--sensitive] [--scan N]   biggest tables, one table's columns, or sensitive columns
gulliver lint SQL [--dialect D]       scale lint of one query
gulliver lint PATH... [--format text|json|sarif|github|gitlab|junit] [--fail-on error|warn|info|never]
                      [--exclude GLOB] [--warn-unused-ignores] [--metadata] [-o PATH]   files and folders (CI)
gulliver rules                        every lint rule: id, name, severity, autofix
gulliver fix SQL [--dialect D] [--mode safe|all] [--limit N] [-o PATH]   rewrite SQL, say what changes
gulliver fix SQL --verify [--cases 200] [--seed 0] [--timezone TZ]      test every rewrite on generated data
gulliver fix --check | --write PATH...                                  same-rows rewrites in files (CI)
gulliver preflight SQL                estimate + lint + gate, no execution
gulliver rehearse SQL [--fractions 0.01,0.03,0.1] [--sample largest|all] [--method auto|system|bernoulli]
gulliver run SQL [--max-rows N] [--allow-write]
gulliver receipt [ID|latest] [--format markdown|json] [-o PATH]
gulliver approve ID [--note TEXT]     (human only)
gulliver demo [PATH]                  create a demo DuckDB database
gulliver lineage --models DIR | --manifest FILE
gulliver impact TABLE[.COLUMN] --models DIR | --manifest FILE
gulliver snapshot | drift [--models DIR] [--save]
gulliver diff --left SQL --right SQL --key k1,k2 [--right-connection NAME] [--columns a,b]
gulliver translate SQL --to D [--from D] [--check] [-o PATH]
gulliver incremental SQL [--time-column C] [--unique-key K] [--period 1d] [--lookback 1]
gulliver check TARGET [--where W] [--unique K] [--not-null C] [--accepted C=a|b] [--range C=min:max] [--fresh C=24h] [--min-rows N] [--max-change PCT]
gulliver top [--source auto|receipts|pg_stat_statements|bigquery_jobs|snowflake_history|csv:FILE|jsonl:FILE]
             [--file PATH] [--days 7] [--limit 20] [--analyze 10] [--rank-by auto|cost|runtime|bytes|calls]
gulliver review [--models DIR] [--base REF] [--head REF] | [--manifest-base FILE --manifest-head FILE]
                [--rehearse] [--fail-on KINDS] [--max-increase-pct N] [--max-increase-usd N] [--runs-per-day N]
                [--format markdown|json] [-o PATH]
gulliver selftest security [--corpus FILE]   the bypass test set and the DuckDB sandbox
gulliver spend [--by agent|day|table|session|task|connection|kind] [--days 7] [--format markdown|csv]
gulliver audit verify [--head HASH]   check the hash chain over ledger, receipts and approvals
gulliver tools --format mcp|openai|gemini [--toolset core|pipeline|all|NAMES]
gulliver mcp [--http] [--toolset core|pipeline|all|NAMES]   start the MCP server
Exit codes: 0 ok, 1 error, 2 blocked (also: a lint finding at --fail-on, a rewrite found by
fix --check, a review that says do not merge), 3 needs rehearsal or approval, 4 a check failed (data
checks, selftest, audit verify).
SQL can be an argument, -f file.sql, or - for stdin. Global flags: --dsn, --config, -c NAME,
--agent NAME, --json.
FAQ
Does Gulliver send my data or my SQL anywhere?
No. It runs on your machine and only talks to the databases you configure. Receipts, the spend ledger and
approvals are JSON files in ./.gulliver/. There is no telemetry.
Do I need a warehouse to try it?
No. gulliver demo builds a DuckDB database with 5 million events in seconds, and gulliver lint works without
any database at all.
Which agents and models does it work with?
Any MCP client: Claude Code, Codex, Cursor, Gemini CLI, Claude Desktop, VS Code, Windsurf. Without MCP, use the CLI
with --json, or gulliver tools --format openai|gemini for function calling. Every answer is short JSON with a
status and a next_step, so smaller models can follow the loop too.
How accurate is the prediction? It is a growth curve fitted on three samples, so it comes with a confidence level and a range (x0.7-1.5 when confidence is high, up to x0.25-4 when it is low). On BigQuery the money estimate uses the exact dry-run bytes of the full query. After a real run, the receipt shows predicted versus actual. Joins and skewed data can grow faster than the data; Gulliver flags that (growth exponent above 1.3) instead of hiding it.
Can the agent change or delete data?
Not by default. Only SELECT runs. Writes (CREATE TABLE ... AS SELECT, INSERT ... SELECT) need both the call
and a human-set allow_write = true on the connection, and the agent cannot approve its own runs.
How is this different from EXPLAIN or a BigQuery dry run?
Gulliver uses those for the preflight. On top of that it rehearses on samples to show how runtime and output rows
grow, rewrites slow SQL with a stated guarantee, enforces a budget, and writes a receipt, in one JSON format across
four engines.
Is the read-only gate enough on its own?
On DuckDB the engine sandbox does not depend on function names, so a file outside the allowed folders is refused
by DuckDB itself. On Postgres, BigQuery and Snowflake the parser is Gulliver's only check, and functions or views
defined in the database can call anything, so keep a read-only database role as well. Run
gulliver selftest security to see the bypass test set pass on your install.
Will the agent see personal data from my tables?
Secrets (passwords, tokens, API keys) are masked by default. Personal data such as emails is shown but flagged
in data_warnings, so queries like "find the customer with this email" keep working. Set a policy per
connection to mask, hash or deny it. Masking happens on the preview after the query ran; the engine still reads
and bills the data.
Can text in my data hijack the agent?
It can try. Gulliver marks every result untrusted: true, lists text that reads like instructions in
data_warnings, and can redact it (injection = "redact"). The scan uses patterns, so a determined attacker can
get past it; the envelope tells the agent to treat rows as data, never as instructions.
My agent keeps re-running the same query. Can Gulliver stop it?
Yes. After max_repeats identical runs on tables that did not change, gulliver_run returns block with
reason loop and the last result for free. Budgets per session and per agent stop one agent from spending the
whole day's budget.
Can I use it in CI without a warehouse?
Yes. gulliver lint models/ and gulliver review (without --dsn) need no database. Add a connection to get
partition checks, same-rows fixes and cost per pull request.
Is it ready for production on BigQuery and Snowflake? Not yet. Both are beta and have been tested against fakes, not live accounts. DuckDB and Postgres are tested in CI, Postgres against a live server. Reports from real warehouses are very welcome.
Roadmap
Ideas for what comes next, not promises. Each one is open for help:
- Live tests for BigQuery and Snowflake, so they can leave beta. The new query tags, history reads for
gulliver topand review cost estimates on those engines are also tested only against fakes so far. - GS005: look up the user functions a Postgres query calls in
pg_proc, and block those in untrusted languages or withSECURITY DEFINER. It needs a live-server test setup. - More same-rows rewrites in
gulliver_fix, and more--verifycoverage (window functions with ties are skipped today). - Stopping the engine job when a rehearsal is cancelled from the MCP client.
- Databricks and ClickHouse engines.
Have a case where an agent's SQL went wrong at scale? Open an issue. Real examples shape the next lint rules.
Contributing
git clone https://github.com/laaielichter/Gulliver && cd Gulliver
pip install -e ".[dev]"
pytest
Contributions are welcome. Start with a good first issue, and read CONTRIBUTING.md and the Code of Conduct. See AGENTS.md for the agent-facing guide and SECURITY.md to report a vulnerability.
Thanks to everyone who helps:
License
MIT, see LICENSE.