CuratorSearch
Museum, gallery and curatorial jobs gathered daily from 400+ institutions' own careers pages, with every advertised salary kept on record. No auth, no key.
Hosted MCP Server
npx add-mcp 'https://curatorsearch.com/mcp'Installs into Claude Code, Codex, Cursor and more
Documentation
Data & API
An independent record of museum and curatorial employment: vacancies gathered daily from 400+ institutions' own careers pages, and every advertised salary kept permanently. Every role, institution and advertised salary on the site is also available in a form a program or an AI assistant can read. This page lists all of it, with how often it changes, which URLs to cite, and what attribution asks.
Query the live board
- MCP server https://curatorsearch.com/mcp
A Model Context Protocol endpoint (stateless Streamable HTTP, POST) with four read-only tools:
search_jobs,get_job,institution_jobsandsalary_transparency. Point any MCP-capable assistant at the URL; no key needed. - JSON API https://curatorsearch.com/api/jobs
?q=&category=®ion=&limit=over the live board, up to 20 linked results per call; one listing in full at/api/jobs/<slug>. Described in openapi.json. Rate-limited per client; send a User-Agent that names your project. - RSS https://curatorsearch.com/feed.xml
The newest roles, filterable exactly like the site: append
?category=and/or?region=with the values used on the board. - llms.txt https://curatorsearch.com/llms.txt A short plain-text description of the site for language models, with the one figure worth quoting computed fresh on each request. llms-full.txt carries every live role in one file, grouped by category.
Download the data
- Curatorial Pay Archive https://curatorsearch.com/data/curatorial-salaries.csv Every advertised salary the board has carried since August 2026, exactly as stated — currency, range, pay period, category, institution, location. Also as JSON. Persistent identifier: DOI 10.5281/zenodo.22544232 (always resolves to the newest snapshot). Mirrors on GitHub, figshare and Hugging Face.
- Museum Pay Transparency Index https://curatorsearch.com/pay-transparency-index Institutions ranked by the share of their own postings that stated a salary, plus a by-country table; recomputed per request, ItemList + Dataset markup. The rows themselves are at CSV and JSON; the JSON carries its own method, caveat and citation line.
- Museum Hiring Index https://curatorsearch.com/hiring-index Monthly: roles advertised, share stating pay, annualised median. Past months are final and never change; the current month accrues daily. A live SVG card at /hiring-index.svg.
- Embeddable badge https://curatorsearch.com/embed A live open-roles count or pay-transparency rate for any site or intranet.
- Sitemap https://curatorsearch.com/sitemap.xml Every indexable page: roles, institutions, cities, salary and comparison pages, the index editions.
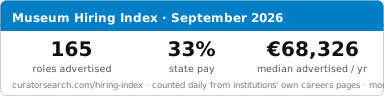
Structured data on the pages themselves
Each role page carries schema.org JobPosting with structured salary where stated and a validThrough date; when a role closes the page stays online as a record, but the markup stops presenting it as open. Institution pages declare Organization and a CollectionPage listing the open roles. /salaries is a Dataset, /faq a FAQPage. The German and Dutch boards are linked by hreflang.
How often it changes
All sources are re-checked once a day at 06:00 UTC. A role is marked closed after two consecutive daily runs no longer find it. Counts, medians and the pay-transparency rate are computed on each request from the current board — never cached — so a figure you read is current as of the page's stated date. The full method is on About & methodology.
Which URLs to cite
Role pages, /opportunities/<slug>, are permanent. Institutions live at /institutions/<slug>, cities at /cities/<slug>, salary pages at /salaries/<slug>. Category and region views are /?category= and /?region=. Search (?q=) and sort views are UI states — noindex — so link to the facet, not to a search.
Attribution
The Curatorial Pay Archive and the Hiring Index are published under CC BY 4.0: free for any purpose, with attribution. Cite as “CuratorSearch Curatorial Pay Archive, curatorsearch.com/salaries” with the date, or by DOI 10.5281/zenodo.22544232. For the method in citable form: Samman, N. (2026). How often do museum job postings state pay? A data note from one month of live listings, August–September 2026. Zenodo. https://doi.org/10.5281/zenodo.22791747.
Job descriptions belong to the institutions that wrote them. Link to the role page rather than republishing the text.
Crawling
Search engines and the main assistant crawlers are welcome and the sitemap is complete. Bulk scrapers that republish listings are blocked in robots.txt and at the edge. If you run a service that needs the full feed rather than the public API, write to support@curatorsearch.com — a keyed partner feed exists for that.