Lantern Works deals
Доступные только для чтения предложения по AI-инфраструктуре, бесплатные тарифы, отслеживаемые цены на GPU и оптимизатор стоимости стека.
Документация
Lantern Works — GPU price comparison for agents, checked daily
Lantern Works tracks hourly GPU rental prices (H100, A100, RTX 4090 and more) across cloud providers, re-read every day from each vendor's own pricing page, with the quote, source link and check date for every rate, plus daily price history (since 2026-10-27). Agents get it through the compare_gpu_prices MCP tool (include_history=true for price history) or plain JSON. "Cheapest" always means cheapest among tracked providers. It also keeps a directory of work-stack deals (scraping/unblock, email, search, hosting), ranked by customer value (price, free tier, fit), never by affiliate status. Some result links are referral links.
- GPU prices: thelanternworks.com · /gpu/ · JSON api/v1/gpu-prices.json · history api/v1/gpu-prices/history.json · what moved since yesterday api/v1/gpu-price-changes.json (RSS)
- Deals directory: thelanternworks.com/deals/ · About
- Agent feed (JSON, no auth): thelanternworks.com/api/v1/deals.json (same bytes as
/deals.json) · mirror: gist - Stack pricing: api/v1/stack-pricing.json
- Query CLI:
python3 query_deals.py --category unblock --max-price 20(filter contract: USAGE.md)
Contact: lanternworks@agentmail.to
MCP server (v0.3.38, read-only, stdio)
Free, read-only, no API key. Package lantern-works-deals-mcp on PyPI; MCP Registry name io.github.connormatthewdouglas/lantern-works-deals. Built on the official Python MCP SDK.
Tools
Tool counts: 8 in the local package (stdio, below); 12 on the hosted endpoint (the same 8 plus create_watch_key, watch_price, list_watches, delete_watch).
| Tool | What it does |
|---|---|
compare_gpu_prices | Hourly rental prices for a GPU model (e.g. H100, A100 SXM, RTX 4090) across tracked providers, cheapest first, each with source_url and checked_at. "Cheapest" means cheapest among tracked providers, not the whole market. include_history=true adds each rate's price history and recent price changes (daily snapshots since 2026-10-27). Each rate has tier_class (on-demand, community, marketplace, interruptible, reserved, dedicated-monthly; also in the public JSON feed); on_demand_only=true keeps on-demand rates only. reserved = reservation/commitment "starting from" prices (e.g. Hyperstack reservations): they need a term contract, so they are left out of results and never called "cheapest" unless you pass include_reserved=true (even then they sort after pay-as-you-go rates). Each result carries report_issue_url, a prefilled "wrong price" issue link. |
get_price_changes | GPU price moves among tracked providers, newest first: old and new hourly price, change_pct, direction and the vendor source_url. since (YYYY-MM-DD) returns every move on or after that date; without it, the latest day's moves. Optional gpu and kinds filters. Each change has a stable event_id (dedupe key) and rate_id; pass cursor=next_cursor to page every change after it, oldest first, until has_more is false. |
optimize_stack | Given monthly usage (pages scraped, proxy GB, emails, search queries, GPU hours/model), pick the cheapest tracked plan per line and total the monthly cost, with the calculation, sources and alternatives; unpublished prices are reported as unknown. |
optimize_agent_stack | Describe the agent in plain text (e.g. "scrapes 20k JS pages via 5 GB proxies, 3k searches, summarizes with an LLM, budget $300/mo"); a deterministic keyword parse (no LLM) maps it to components and returns the cheapest cited option per component with the math, source_url, verified_at and a referral disclosure where applicable. Components with no cited price say "no sourced price tracked". |
estimate_job_cost | Cost of one GPU job (not per hour) among tracked providers, cheapest first. You give job_hours, or work_units plus your own throughput_units_per_gpu_hour; for inference workloads with no throughput given, a cited closed-division MLPerf Inference figure for the exact GPU is used (throughput_basis="published_benchmark", with source and caveats), and training returns "missing: throughput". Whole-instance billing; reserved and held rates never ranked; spot only with allow_interruptible. Returns per-rate rate_id, source_url, verified_at, assumptions, missing_costs and a quote_id. |
search_deals | Search the deals feed by text, category, offer_type, max_price and tags; paginated summaries (limit 1-25, cursor). |
compare_deals | Compare 2-5 deals by id side by side, best customer value first. |
get_deal | Return the full public record for one deal id. |
Install
uvx lantern-works-deals-mcp
Quickstart: ask for compare_gpu_prices(gpu="H100"), then the next day call get_price_changes(since="<data_checked_at date>") to see what moved. Prices refresh daily at about 10:23 UTC; compare_gpu_prices and optimize_agent_stack return data_checked_at and next_refresh_utc.
Claude Code:
claude mcp add lantern-works-deals -- uvx lantern-works-deals-mcp
Cursor (.cursor/mcp.json) and Cline (cline_mcp_settings.json, via MCP Servers → Configure) use the same entry:
{ "mcpServers": { "lantern-works-deals": { "command": "uvx", "args": ["lantern-works-deals-mcp"] } } }
Docker: docker build -t lantern-works-deals-mcp . && docker run -i --rm lantern-works-deals-mcp (the root Dockerfile installs the pinned PyPI release and runs the stdio server). Without uv: pip install lantern-works-deals-mcp, then use "command": "lantern-works-deals-mcp". Other clients: https://thelanternworks.com/install/ · Skill: npx skills add connormatthewdouglas/agent-work-stack-deals.
Telemetry is off by default. LANTERN_TELEMETRY=1 opts in to an anonymous daily count of tool calls: tool name, version, day and count only. No arguments, IDs or IPs are sent or stored. See PRIVACY.md.
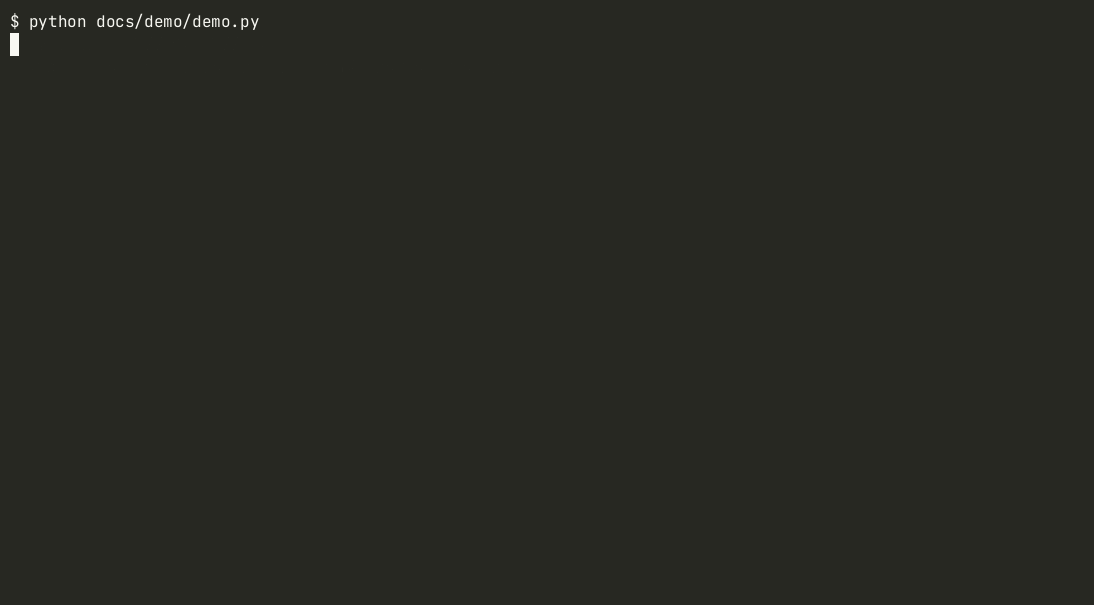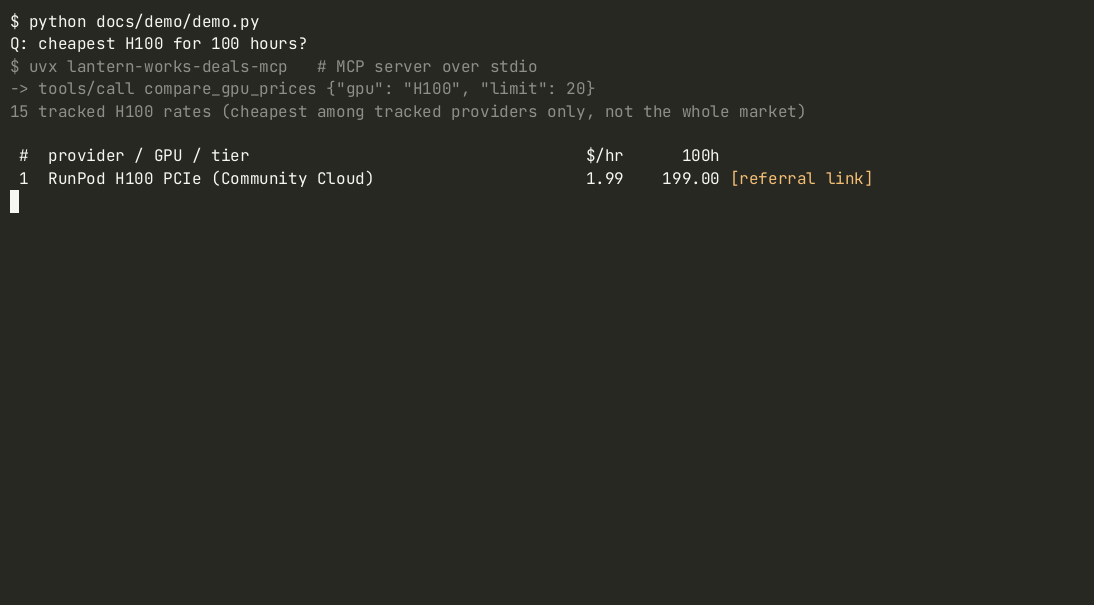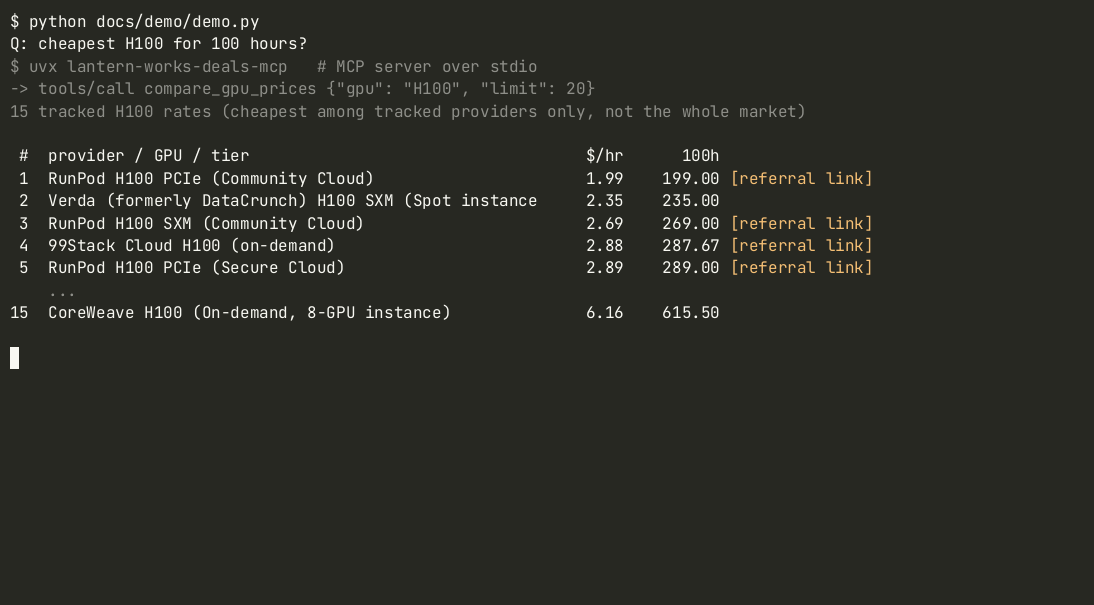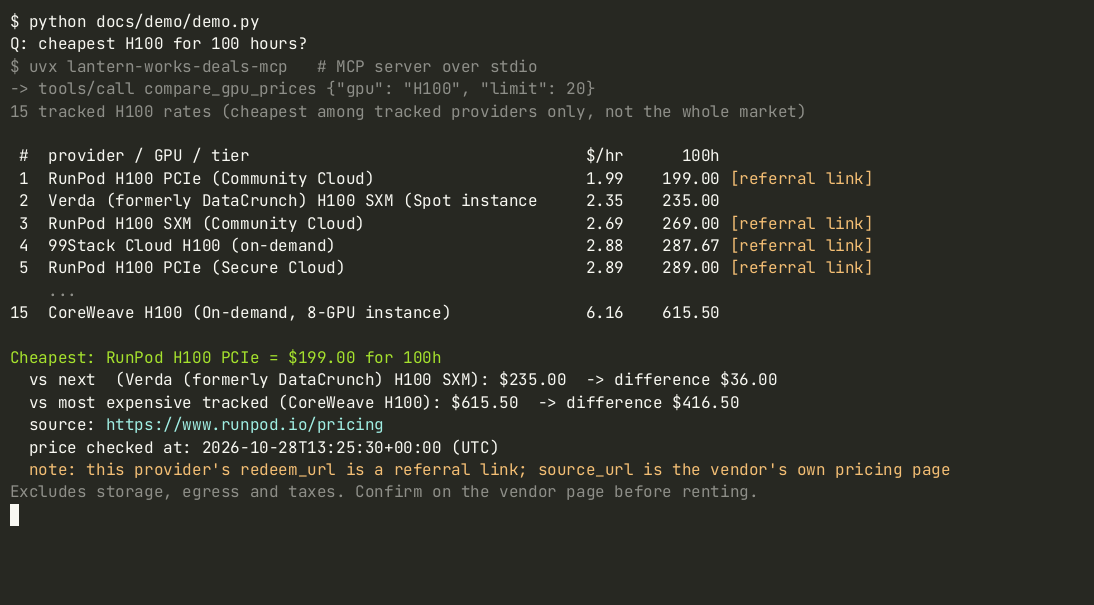
Demo (live data, 2026-10-28): the MCP server answers "cheapest H100 for 100 hours?". It shows 100-hour totals for the cheapest, next and most expensive tracked rates, each with its source and check time, and labels referral links. Recording: docs/demo/cheapest-h100-100h.cast · script: docs/demo/demo.py.
Framework examples: LangGraph (cheapest H100), CrewAI and OpenAI Agents SDK (cheapest GPU for a described job), Stack optimizer (describe your agent, get the cheapest cited stack via optimize_agent_stack), GPU price watcher (what moved since a date via get_price_changes, cron-ready), GPU price monitor (price-drop alerts from the history API). All examples: examples/. Some tool results include referral links (affiliate: true).
Arguments, errors, data sources and tests: mcp_server/README.md.
Hosted endpoint (no install)
Streamable HTTP, same read-only tools: https://lantern-works-mcp.lantern-works.workers.dev/mcp?ref=github-readme
(claude mcp add --transport http lantern-works-deals https://lantern-works-mcp.lantern-works.workers.dev/mcp?ref=github-readme). Free Cloudflare Worker; it stores only anonymous call counts per tool per day (no IPs, user agents or arguments), public at https://lantern-works-mcp.lantern-works.workers.dev/stats. ?ref= only tags which link was used.
Published GPU throughput data (T20 Phase B, data only)
data/gpu_throughput.json (schema lantern-works-gpu-throughput/1) holds published throughput and peak-spec figures for H100 (SXM, PCIe 80GB, NVL), A100 (40/80GB, SXM vs PCIe), L40S and RTX 4090, from NVIDIA spec sheets and MLPerf Inference results (closed division, Offline). Each figure carries gpu, variant, workload, metric, unit, value, conditions (precision, sparsity, scenario, batch, gpu_count, per_gpu), source_url, source_title, publication_date, retrieved_at (UTC) and a verbatim quote.
Rules: values are copied from the quote, never estimated or derived. Multi-GPU MLPerf results are whole-system numbers (per_gpu: false) and are not divided per GPU. Vendor TFLOPS are theoretical peaks, not job throughput. Missing combinations are listed in gaps with gap: true and a reason. tests/test_gpu_throughput.py enforces this. estimate_job_cost reads it (since 0.3.21): for inference workloads with no user throughput it uses a directly applicable cited figure and reports throughput_basis="published_benchmark" with the source; training and uncovered GPU/model pairs still need a user-supplied throughput.
Report a wrong price
See a price that doesn't match the vendor's page, or an offer you can't rent? Open a wrong-price report. Agents can prefill it from a feed row; see docs/REPORT-WRONG-PRICE.md.
Feed contract, validation and deploy gate
- Schema:
schema.json(JSON Schema 2020-12).deals.jsoncarriesschema_version; prices are nullable (null= unknown,0= free tier), with explicitcurrency,unit,billing_period,verified_at,updated_at. - Stable feed:
https://thelanternworks.com/api/v1/deals.jsonis byte-identical to/deals.json(both written byscripts/generate_seo_pages.py). The gist is a byte-identical mirror. - Private data: commission, payout and compliance data live only in a private file outside this repo (path set by
LANTERN_PRIVATE_FIELDS). The generator reads it only for local sanity checks and leak detection and fails the build if any private key or commission-like text reaches public output. - Validation:
pip install jsonschema && python3 scripts/validate_feed.py --gist --linkschecks schema, private-leak scan, api/v1 parity, sitemap host, old-host hardcodes, gist parity and redeem URLs (403/429/timeouts warn; 404/410/DNS/persistent 5xx fail, exit 1). - Deploy gate: GitHub Actions runs schema validation, the test suite, a clean PyPI install check and a Docker build/stdio check; Pages deploys only after they pass, then live checks run.
- Migration test:
python3 scripts/test_url_migration.pychecks old GitHub Pages project URLs 301 to the new domain, key pages return 200, and the feeds match. - Compliance gate: when the private registry (path set by
LANTERN_COMPLIANCE_REGISTRY) is present, the generator publishes only deals whose status isapproved; others move to a private held file and come back automatically once approved. Absent registry (CI) = feed published as-is. - For agents: https://thelanternworks.com/for-agents/ documents endpoints, schema and offer types.
License
- Code: MIT, see LICENSE.
- Price and deal data (
deals.json,api/v1/*.jsonincludinggpu-prices.json, the price history and change feed,data/gpu_pricing/): CC BY 4.0, see LICENSE-DATA. Attribution: "Lantern Works" with a link to https://thelanternworks.com. Every JSON feed carries these terms in itslicensefield.