Unified AI System
Gateway MCP e de IA auto-hospedado que transforma linguagem natural bruta em prompts estruturados com roteamento governado e verificação reproduzível para Codex, Cursor e Cline.
Documentação
Unified AI System: Self-Hosted AI Gateway & MCP Server
Open-source AI gateway for deterministic prompt enhancement, governed execution, and reproducible verification.
English | zh-CN | Project Site



Unified AI System turns a rough request into a structured, reviewable prompt before execution. It gives teams one self-hosted surface for OpenAI-compatible SDKs, MCP, A2A, CLI, and HTTP while keeping provider calls explicit — with virtual keys and token budgets, exact response caching plus an opt-in lexical-approximate similarity layer, reverse MCP governance with REST→MCP generation, a terminal-first JSON operations overview, and operations-focused observability.
Where this README makes a claim about MCP servers in the wild, it is measured rather than asserted: nine measurements of the public MCP ecosystem (40 registry-advertised servers, asked anonymously, every page naming its own denominator) and the same results as machine-readable data (nine questions in ten measurement legs, 400 rows, 2026-09-28).
Current maturity: hardened Public Preview. The credential-free path is reproducible and CI-gated; production deployment still requires your own provider staging, HA/DR drills, security review, and operating evidence.
Try It in 60 Seconds
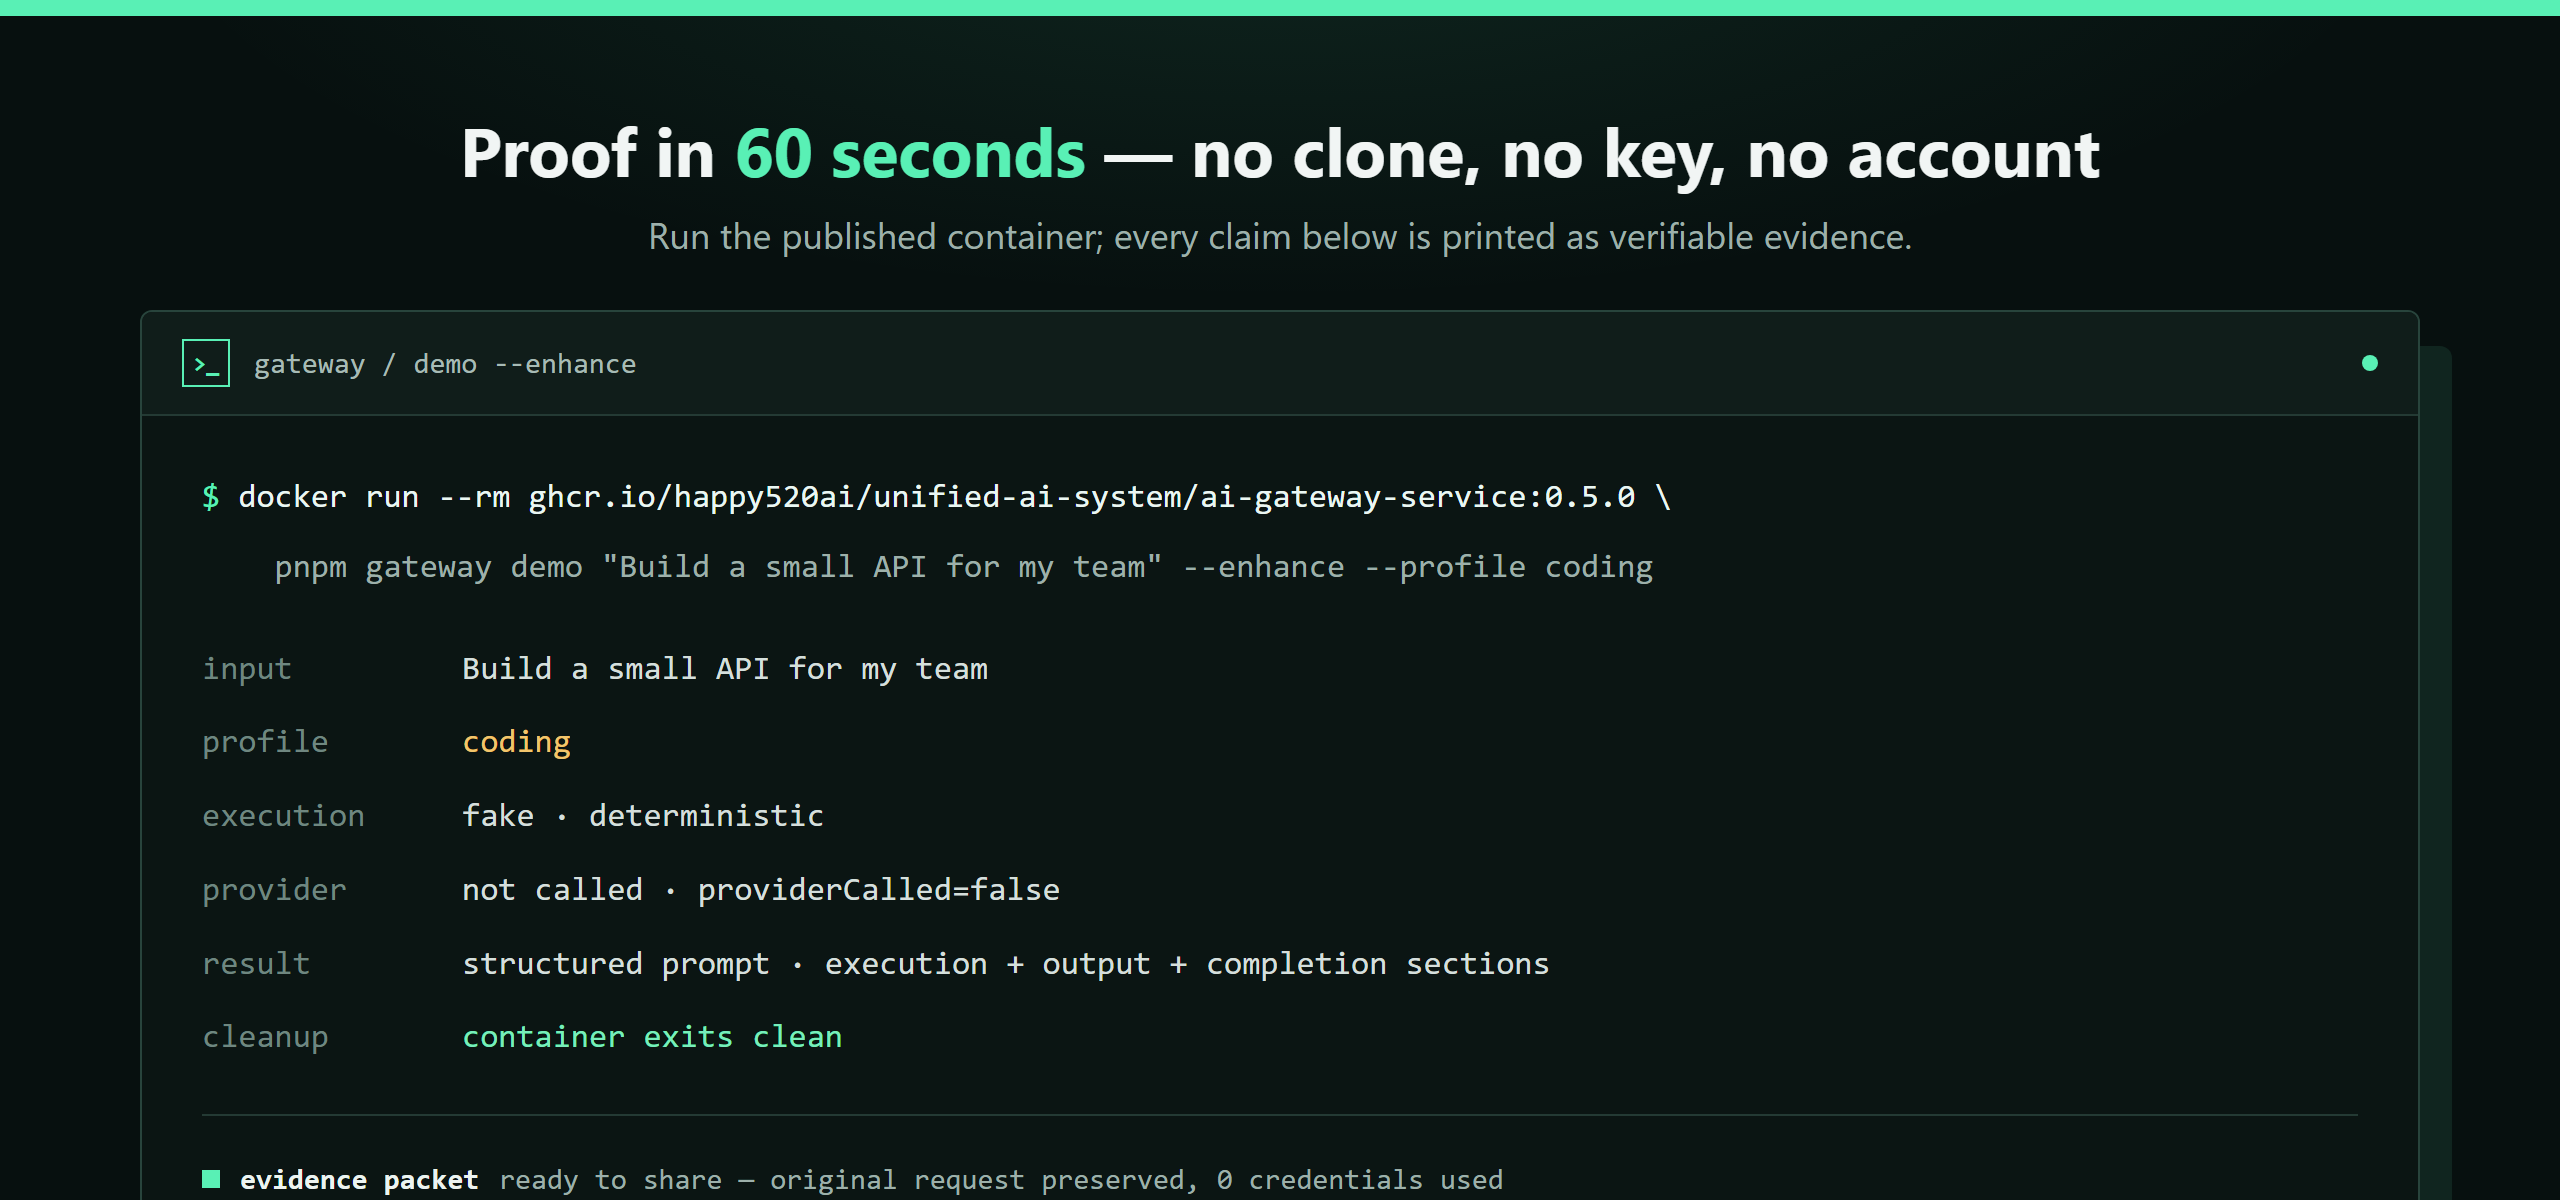
Verify the project without signing in:
docker run --rm ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0 pnpm gateway demo
On Apple Silicon, put --platform linux/amd64 before the image name. Both published arm64 tags - the gateway
and the MCP server - carry x86-64 native modules, so this demo fails there today
(#190, with the reading and the command that
reproduces it).
No Docker daemon, or an Apple Silicon machine where the line above is known to fail? The same proof runs from a source checkout, and with dependencies already installed the demo itself takes seconds rather than minutes: the one run we captured measured 14.0 s of wall time on a single laptop, and that page says plainly it is one run, not a benchmark:
git clone https://github.com/happy520ai/unified-ai-system.git
cd unified-ai-system
corepack enable && pnpm install --frozen-lockfile    # prerequisites: Node 22.18.0+, pnpm 11.19.0
pnpm gateway demo "Build a small API for my team" --enhance --profile coding --evidence
Measured on this machine - Windows, Node v25.8.1, no Docker engine installed - exit 0, "mode": "fake",
"providerCalled": false, "credentialRequired": false, 4,787 bytes, and three consecutive runs came out
byte-identical. The install line in front of the demo is the part that is not sixty seconds;
pnpm verify:public-clone, further down, is a longer optional check and not a prerequisite for this run.
Expected behavior:
- local fake-provider execution
- visible
execution: fake - deterministic output
- no API key or account needed
- container exits automatically
One-command natural-language enhancement preview:
docker run --rm ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0 \
  pnpm gateway demo "Build a small API for my team" --enhance --profile coding --evidence
This starts an isolated fake-provider gateway, enhances the request locally, prints the structured prompt, and cleans up without an API key.
Check the tool roster of a published image without installing it (from a clone):
node tools/verify-image-roster.mjs 0.8.0
It reads MCP_TOOL_NAMES out of the container layer over plain HTTPS and verifies every
blob against the digest its manifest names — no Docker daemon, no registry login. Expected:
a line reading tools 15. The same command against 0.4.0 reports nine, so the number
tracks the artifact rather than the prose written about it. The eight-tag history behind
those counts — including why latest and 0.8.0 ship the same interface as different
bytes — is in the
image roster note.
Try Before Installing
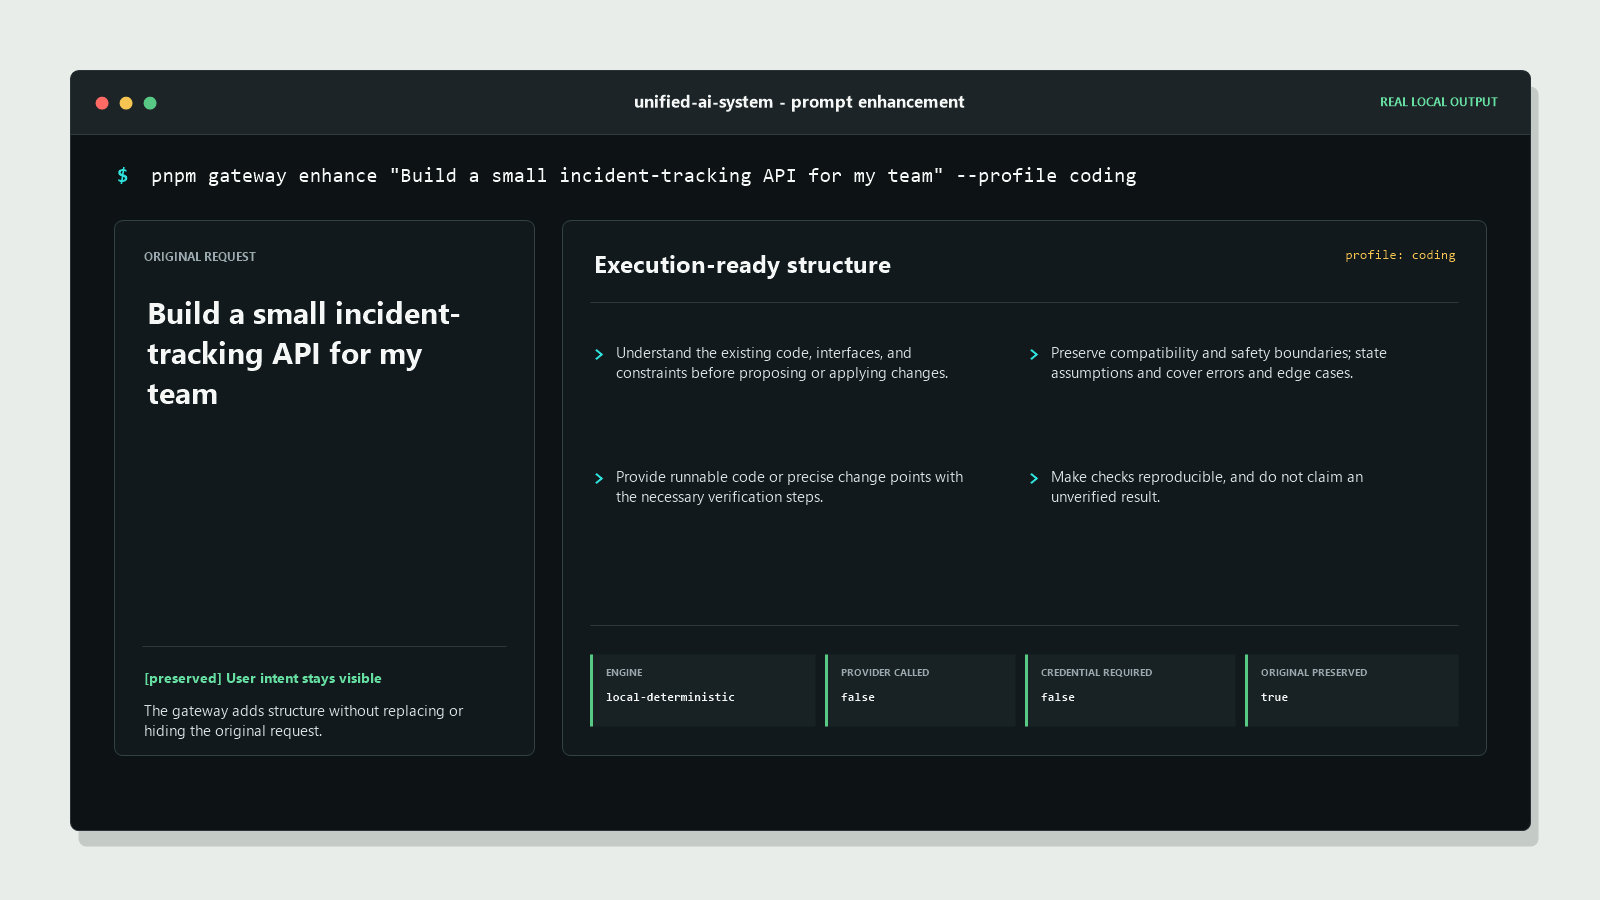
The original request stays visible. The local enhancer adds execution requirements, output requirements, and completion criteria.
Open a ready-to-run coding example in the browser Prompt Lab
The link loads a real request and renders the enhanced prompt locally. No account, API key, or provider call is required.
Run the same proof against the published container:
docker run --rm ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0 pnpm gateway demo "Build a small API for my team" --enhance --profile coding --evidence
The evidence confirms that the original request was preserved, the result is
deterministic, and providerCalled=false. Codex, VS Code, Claude Code, Gemini
CLI, OpenCode, Cursor, Cline, Continue, and generic stdio clients can reach the
same gateway through authenticated, permission-scoped MCP tools (15 in the current source build;
inspect the tool list of your installed image). The source build also provides a
protocol-tested MCP Streamable HTTP endpoint for clients that connect by URL.
Useful in a real workflow? Star the repository or share one reproducible result.
The Gateway at a Glance
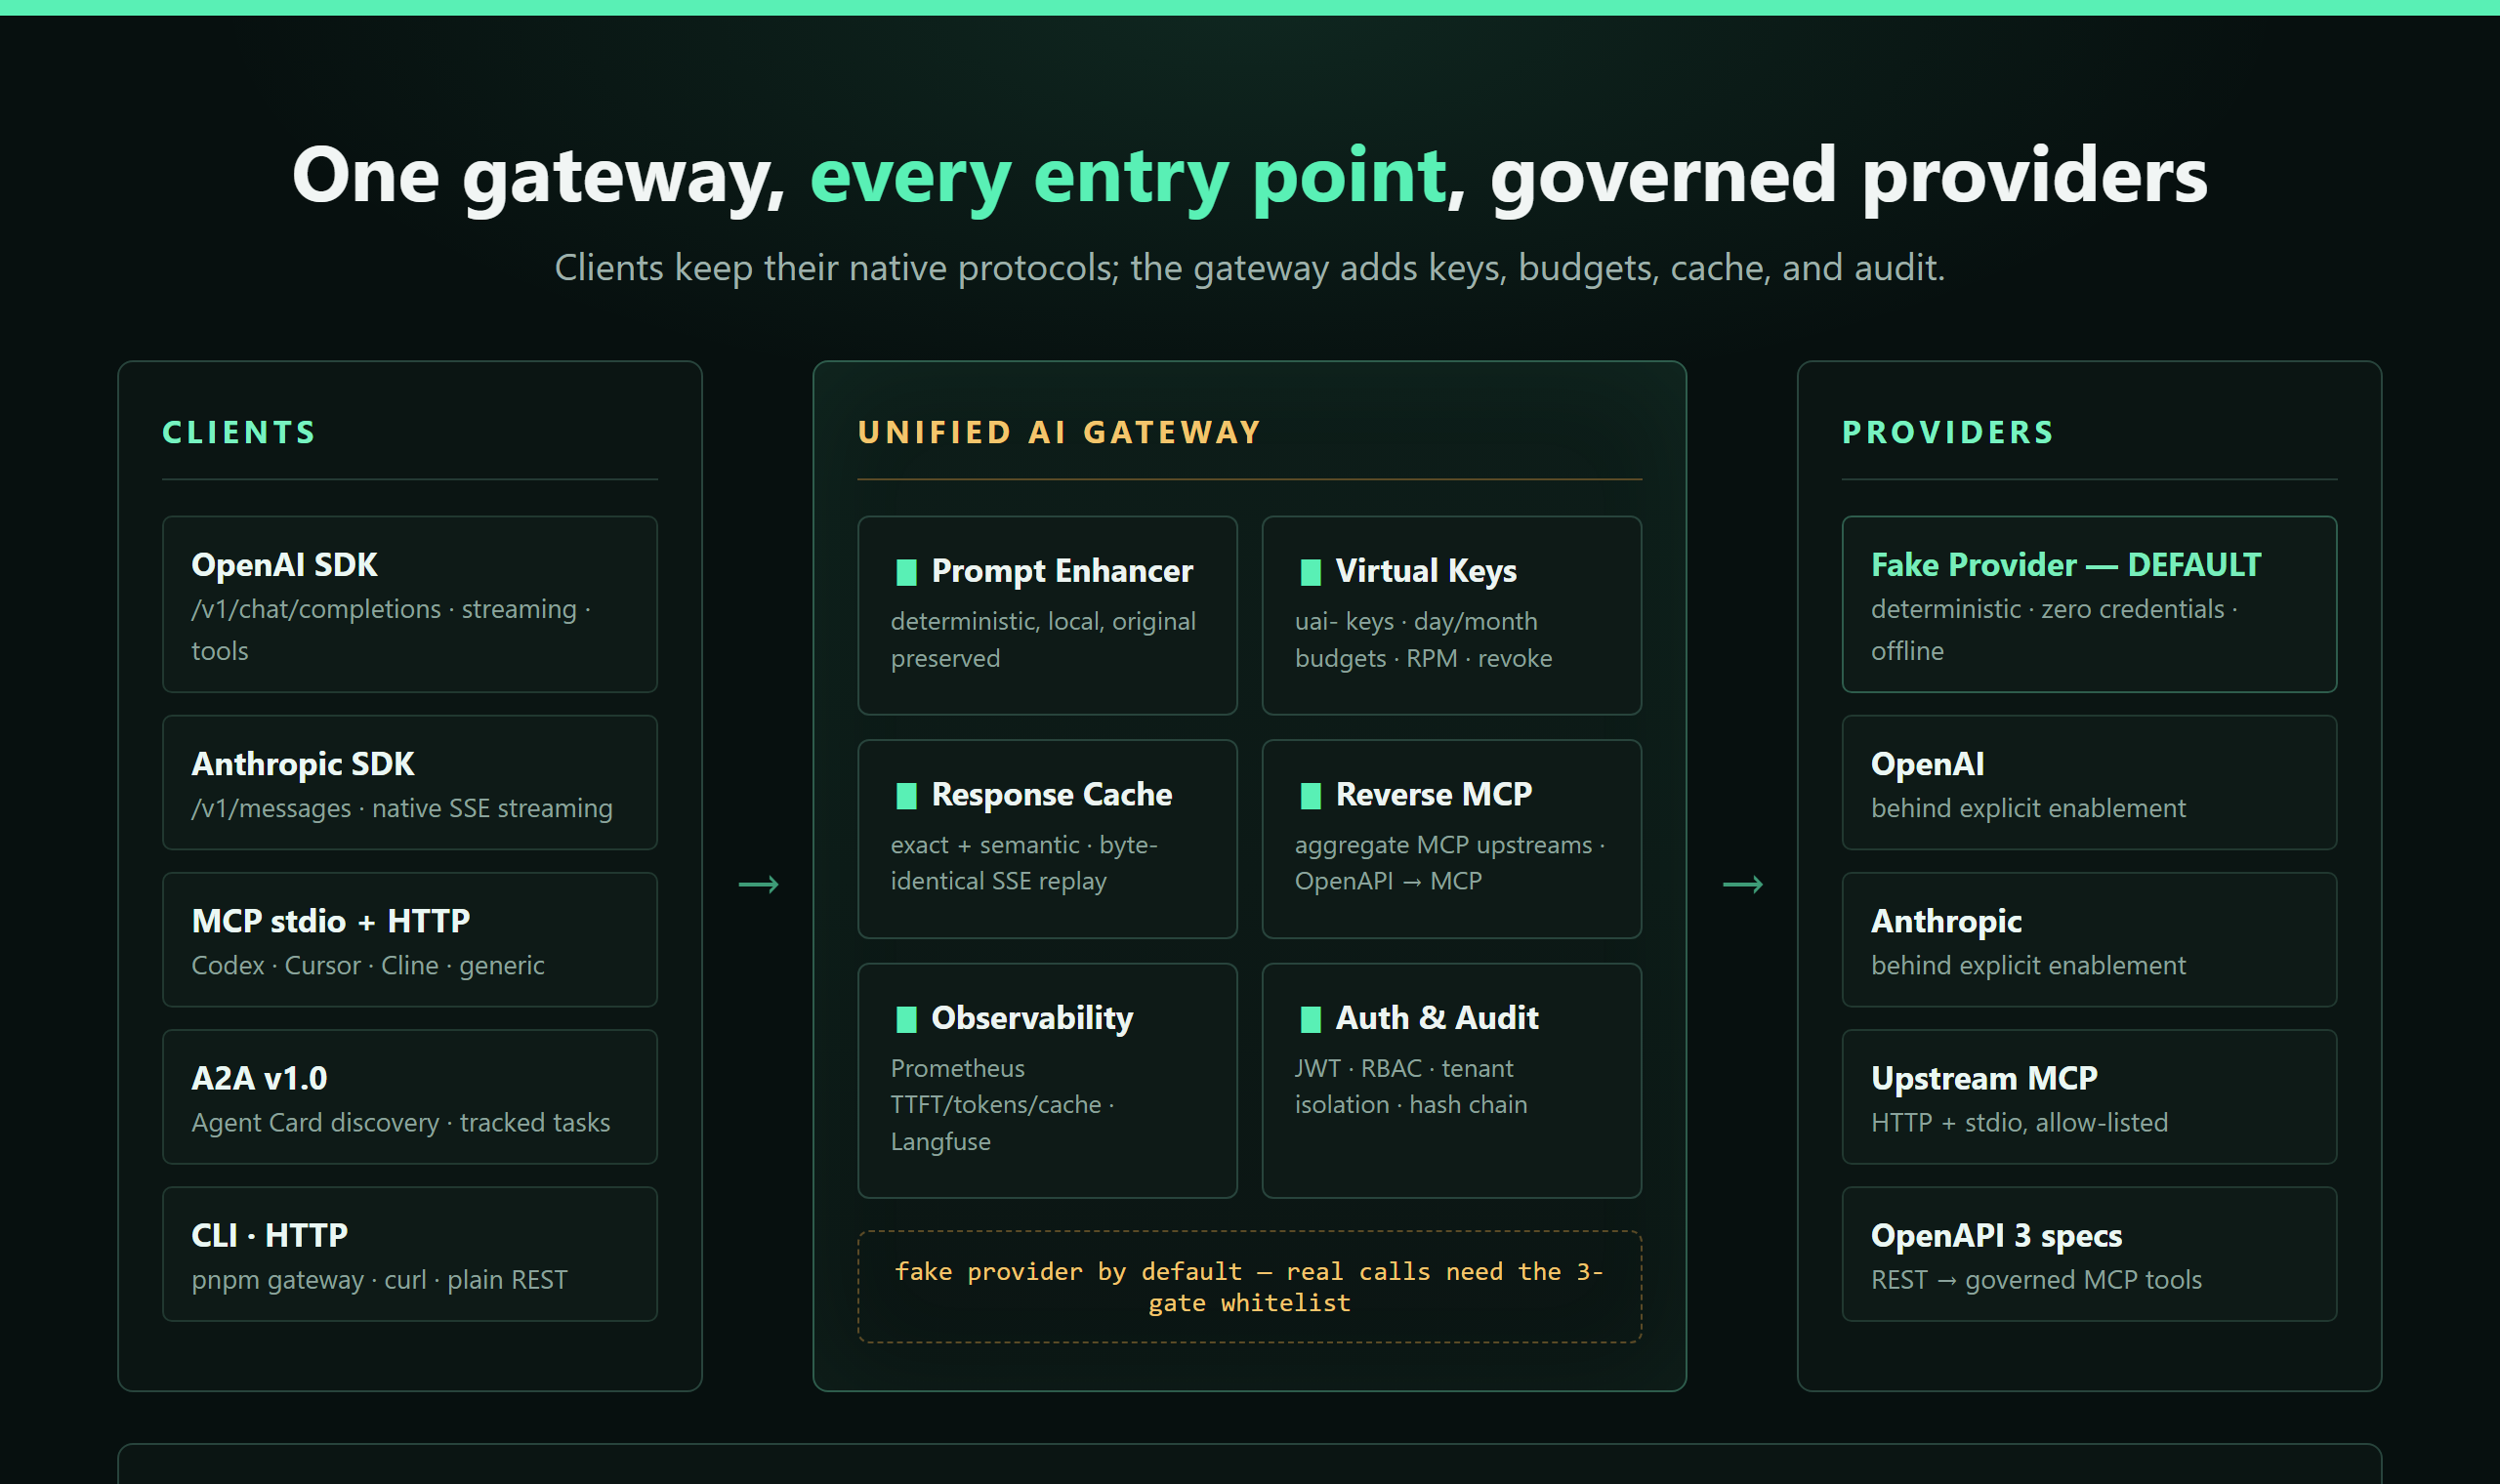
Clients keep their native protocols; the gateway adds keys, budgets, cache, and audit. The published image exposes fifteen bounded MCP tools, matching the current source build; both are inspectable after connecting. Controlled writes additionally require Agent Governance when enabled.
Choose Your First Path
| Your goal | Start here | What you get |
|---|---|---|
| Try it before installing | Browser Prompt Lab | A local, deterministic preview with no account or API key. |
| See who has accepted it | Where this project is listed | Curated catalogues and public MCP directories that carry an entry today, each with the URL that proves it, re-probed nightly. |
| Verify the published runtime | 60-second Docker demo | A disposable fake-provider run with visible evidence and cleanup. |
| Connect an agent client | Codex and MCP quickstart | A pinned MCP container with an inspectable tool list. |
| Choose a client path | MCP compatibility matrix | Install commands, first checks, and honest evidence boundaries. |
| Integrate with an application | Prompt enhancement guide | CLI, HTTP, SDK, curl, Python, and JavaScript paths. |
| Keep an existing OpenAI client | OpenAI-compatible API | Point baseURL at /v1 for Chat Completions, function tools, Responses, streaming, and model discovery. |
| Connect another agent | A2A v1.0 gateway | Verify an optionally signed Agent Card/JWKS and run tenant-scoped tasks with bounded memory, same-host SQLite, or cross-host PostgreSQL state plus fenced execution leases. |
| Check client runtime certification | Client runtime certification | Evidence-backed catalog state: 52 verified, 2,084 pending manual evidence, and 0 failed across 2,136 unique entries. |
| Run the certification suites yourself | Client runtime certification | node tools/verify-client-runtimes-serial.mjs --client tag:mainstream for sequential reports, node tools/run-global-client-discovery.mjs --source-manifest docs/client-runtime-catalog-sources-worldwide.json --execute --serial --max 0 for global coverage, and add --require-manual-evidence --manual-evidence docs/client-runtime-evidence.example.json to fail on missing manual proof. |
| Inspect the enhancement contract | Credential-free evaluation | Eight representative cases for profiles, languages, signals, determinism, and zero provider calls. |
| Diagnose a first-run problem | Troubleshooting matrix | Shell-specific checks without exposing credentials. |
| Verify an MCP client | MCP client report | Record one Codex, Cursor, Cline, or generic stdio run with a small evidence set. |
| Contribute or report a run | Usage report or good first issue #106 | A reproducible feedback path for users and maintainers. |
Gateway Capabilities
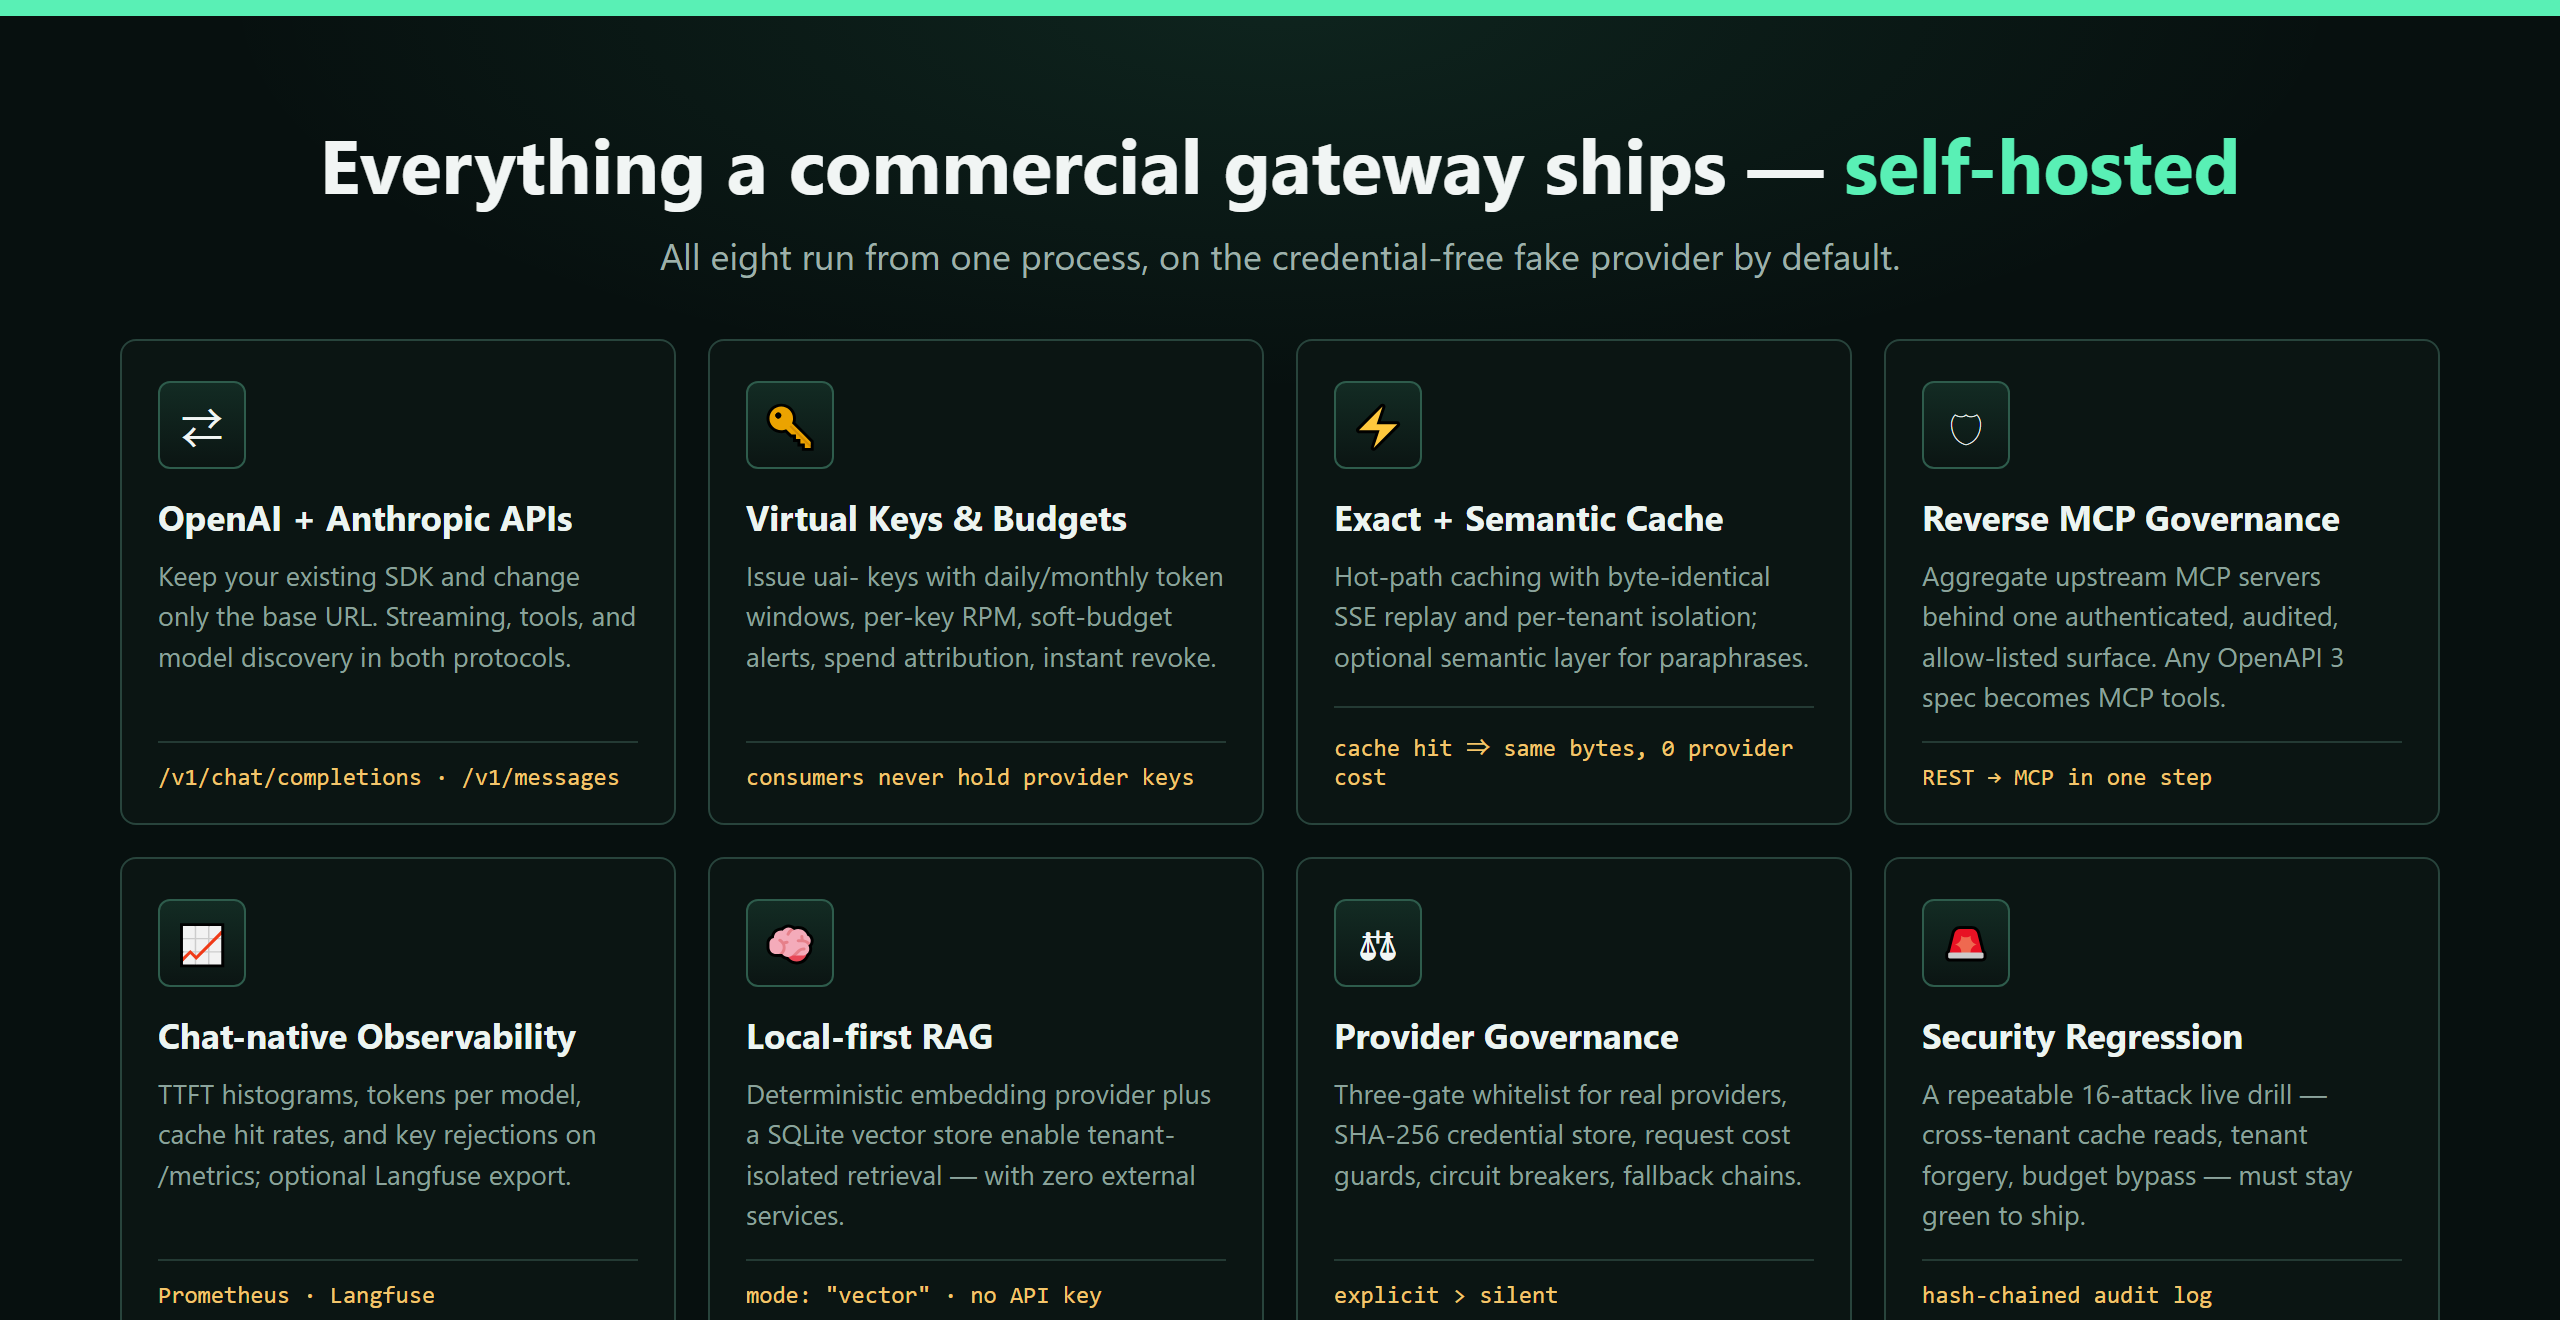
Everything below runs from the same self-hosted process — opt-in and fake-provider-first, so you can try every feature with zero credentials:
| Capability | What you get | Docs |
|---|---|---|
| OpenAI + Anthropic + Gemini compatible APIs | /v1/chat/completions (SSE streaming, tools, image/audio input, n>1), /v1/messages with native Anthropic streaming and prompt-caching passthrough, native Gemini inbound :generateContent/:streamGenerateContent/:batchGenerateContent, the Responses API, and model discovery — keep your existing SDK, change only the base URL. | OpenAI-compatible API · Gemini |
| Virtual keys + budgets | Issue uai- keys with periodic token budgets (daily/monthly windows), per-key request limits, soft-budget alerts, spend attribution, and instant revocation. Consumers never hold provider keys. | Virtual keys · Spend reporting |
| Response cache — exact + lexical-approximate | Tenant-scoped hot-path caching with byte-identical JSON/SSE replay, plus an opt-in similarity layer for near-duplicate requests. The default layer is deterministic lexical approximation, not a semantic model; attach a real embedding endpoint via the HTTP embedding hook for semantic-grade matching. | Response cache |
| Operations overview API (terminal-first) | GET /api/overview returns a compact JSON snapshot (provider mode, health, readiness, request stats, circuit state) behind dashboard:read — a lightweight companion to /metrics for CLI and dashboard tooling. The gateway serves no browser page; the public-clone gate keeps it terminal-first. | Observability |
| Guardrails — deterministic & local | Input/output scans: pasted secrets block, PII redacts, injection phrasings warn, banned terms and size limits enforce — no cloud tier, no extra credentials, <0.2 ms measured overhead, runtime-configurable per rule. | Guardrails |
| Reverse MCP governance | Aggregate upstream MCP servers (Streamable HTTP and stdio) behind one authenticated, audited, allow-listed surface — plus REST→MCP: each OpenAPI 3 operation whose input semantics are unambiguous becomes a governed MCP tool; a construct that cannot be resolved is refused rather than guessed. | Reverse MCP governance |
| Agent governance control plane | Explicit opt-in for server-bound /agent-exec, reverse-MCP, controlled /workforce/execute, and per-action /forge/orchestrate, with deterministic policies, signed state, reviewable top-level approvals, dual fences, rollback detection and cascade revocation. Per-action Forge approvals are not yet implemented and fail closed before any effect; Workforce run-local/A2A and standalone Forge remain explicit boundaries. | Agent governance |
| Observability | Chat-specific Prometheus metrics on /metrics — tokens per model, cache hit rates, TTFT histograms, virtual-key rejections, guardrail findings — plus an opt-in Langfuse export and a per-key spend report API/CLI. | Observability |
| Vector retrieval | A credential-free deterministic embedding provider and the SQLite vector store activate mode: "vector" RAG with strict tenant isolation. | Providers & knowledge |
| Provider governance | A three-gate whitelist matrix for real providers; memory-only runtime credentials by default, with opt-in AES-256-GCM encrypted file/SQLite persistence and a separately protected master key; hashed virtual keys and user tokens; request cost guards, circuit breakers, and fallback chains. | Provider enablement |
| Local-client intelligence gateway | Tenant-scoped inventory, server-bound per-client PoP, policy-pinned fake-provider dispatch, dry-run autonomous management, governed execution with receipt reconciliation and exactly-once aggregate learning, irreversible revocation, and transactional MCP onboarding. Credential-free fixture flows are proven; the open release gates are enumerated in the design doc. | Design and evidence boundary |
| Enterprise governance + security drills | JWT auth, RBAC, tenant isolation with audit hash chains — verified by a repeatable 23-attack live security regression. | Security drill · run output · what the drills do not establish |
| Enterprise identity & provisioning | OIDC SSO (authorization code + PKCE + JWKS signature verification, issues an API token on login) and SCIM 2.0 user provisioning (bearer-auth create/get/list/patch/deactivate). | Security drill · Enterprise SSO & SCIM |
| Operator traffic control | Configurable weighted routing splits and shadow traffic (AI_GATEWAY_WEIGHTED_ROUTES_JSON): shadow calls are separately accounted; real-provider shadowing also requires AI_GATEWAY_SHADOW_REAL_PROVIDER_ENABLED=true. | Multi-process deployment |
| Hot-path RAG + billing evidence | Opt-in unified_ai.rag knowledge injection on /v1/chat/completions; central usage evidence and an admin-only exact-attempt USD statement comparison. Local statement previews remain explicitly non-legal and no payment gateway is connected. | Spend reporting · RAG injection |
| Multi-instance controls | AI_GATEWAY_MULTI_INSTANCE=true keeps same-host SQLite defaults; explicit PostgreSQL modes cover cross-host quotas, response idempotency, dispatch tombstones, WebSocket/A2A/Workforce leases and terminal fences, approvals, billable usage, and a shared HMAC audit chain. A destructive CI drill proves bounded LSN-PITR, single-bridge fencing, old-primary safe rejoin, single-standby automatic failover, and at-most-once admission, and that drill carries its own not-proven list naming what stays deployment work. | Multi-process deployment · PostgreSQL recovery drill · External-effect fencing |
Published infrastructure benchmark (fake provider, single node): chat JSON p50 15.6 ms, SSE TTFT p50 2.8 ms, 402 req/s at concurrency 8, cache hits 5.6× faster than misses — see the gateway benchmark.
Why People Use It
- Prompt enhancement for teammates who do not write perfect prompts.
- Clean-clone verification without credentials or hidden setup.
- Provider-free HTTP examples for curl and Python's standard library.
- OpenAI SDK, CLI, HTTP API, shared SDK, MCP, Codex, Cursor, Cline, and Continue entry points.
- Clear boundaries: no AGI claim, no L5 claim, no silent provider behavior.
- Protocol-first onboarding: the governed JSON transaction path currently supports Claude-compatible, Cursor, and VS Code profiles. Other MCP, A2A, or HTTP clients require an explicit adapter/principal binding and reproducible certification report.
More Credential-Free Paths
You can also pipe a request directly into the published image without cloning the repository:
printf '%s' "Plan a launch for a small API" \
  | docker run --rm -i ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0 \
      pnpm --silent gateway demo --enhance --profile planning --language en --json
PowerShell equivalent for a request file:
Get-Content .\request.txt -Raw |
  docker run --rm -i ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0 `
    pnpm --silent gateway demo --enhance --profile planning --language en --json
The container still uses the disposable fake-provider path and exits after the result is printed.
Use --language zh-CN or --language en when the enhancement output should
follow an explicit language instead of automatic detection.
Prompt enhancement example:
Start the gateway first (from a source checkout):
pnpm gateway serve
Then, in another terminal:
pnpm gateway enhance "Build a small API for my team" --profile coding
pnpm gateway chat "Build a small API for my team" --enhance --profile coding
The CLI also accepts a request from stdin, which is useful for shell pipelines and text files:
printf '%s' "Plan a launch for a small API" \
  | pnpm gateway enhance --profile planning --language en
cat request.txt | pnpm gateway enhance --profile auto --json
PowerShell users can pipe the same path with Get-Content .\request.txt -Raw.
Existing OpenAI SDKs
Start the source gateway with pnpm gateway serve, then keep your existing
OpenAI client and change only its base URL:
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "http://127.0.0.1:3100/v1",
  apiKey: process.env.PME_AUTH_TOKEN || "local-development",
});

const result = await client.chat.completions.create({
  model: "local-fake-model",
  messages: [{ role: "user", content: "Build a small API for my team" }],
});

console.log(result.choices[0].message.content);
The credential-free gate verifies this path with the official OpenAI
JavaScript SDK 7.4.0. With the source gateway running, reproduce it with:
node docs/examples/openai-sdk-chat.mjs
The focused compatibility layer supports text completions, streaming, model listing, and optional local prompt enhancement. See the OpenAI-compatible API guide for Python, supported fields, auth behavior, and explicit limitations.
Prefer Node.js? The dependency-free example verifies the provider-free response before printing the enhanced JSON:
node docs/examples/prompt-enhancement.mjs "Help me plan a small API for my team" --profile planning --language en
Prefer Go? The standard-library example checks provider-free readiness and prints JSON evidence before showing the enhanced prompt:
go run docs/examples/prompt-enhancement.go "Help me plan a small API for my team" --profile planning --language en
For a no-clone prompt-enhancement walkthrough, start the published gateway image and follow the provider-free curl example:
read -rsp "Enter a random gateway token (32+ characters): " PME_AUTH_TOKEN
printf '\n'
export PME_AUTH_TOKEN
docker run --rm --publish 127.0.0.1:3100:3100 \
  --env AI_GATEWAY_SERVICE_HOST=0.0.0.0 \
  --env AI_GATEWAY_PROVIDER_MODE=fake \
  --env AI_GATEWAY_REAL_PROVIDER_ENABLED=false \
  --env PME_ENTERPRISE_AUTH_ENABLED=true \
  --env PME_AUTH_TOKEN \
  ghcr.io/happy520ai/unified-ai-system/ai-gateway-service:0.8.0
Keep that process running while you send the curl request. The response
includes metadata.providerCalled=false. For a credential-free HTTP stream,
use the curl SSE example to inspect
start, chunk, and done events with executionMode=fake.
The gateway refuses non-loopback listening when authentication is disabled;
see the critical attack-chain hardening report.
Use It
Terminal Workflow
After pnpm install:
pnpm gateway serve
pnpm gateway status
pnpm gateway doctor
pnpm gateway chat "Hello from Unified AI System"
The protected local-client control plane has read-only inspection plus explicit governed lifecycle commands. Prefer supplying the admin virtual key through the environment so it is not written to shell history:
$env:AGENT_CONSOLE_ADMIN_KEY = "<admin-virtual-key>"
pnpm gateway clients --json
pnpm gateway clients discover --json
pnpm gateway clients --help
Discovery and smart-management default to dry-run. Mutations require explicit confirmation and an admin key; uncertain writes are never retried. A registry inspection is not proof that a named application was configured or controlled. See Local Client Intelligence Gateway for the adapter and evidence boundary.
MCP / Codex / Cursor / Cline
Published MCP command:
codex mcp add unified-ai-system -- docker run --rm -i ghcr.io/happy520ai/unified-ai-system/mcp-server:0.8.0
On Apple Silicon, put --platform linux/amd64 before the image name. The published linux/arm64 tag
currently ships x86-64 native modules, including better-sqlite3, so the governed tools fail to load there -
issue #190 carries the reading and the one command
that reproduces it.
Restart Codex, run /mcp verbose to inspect the installed tool list, then follow the
60-second Codex MCP quickstart for a safe first
prompt-enhancement call and removal command.
Building from the repository takes one extra flag. The root Dockerfile declares two publishable
stages, mcp and gateway, and gateway is the last one, so a plain docker build . produces the
HTTP gateway - which never answers on stdio:
docker build --target mcp -t unified-ai-system-mcp .
printf '%s\n' '{"jsonrpc":"2.0","id":1,"method":"initialize","params":{"protocolVersion":"2025-06-18","capabilities":{},"clientInfo":{"name":"probe","version":"0"}}}' \
  | docker run --rm -i unified-ai-system-mcp
--target mcp and --target gateway are the two targets the release workflow builds, so this is the
same build that publishes the image above rather than an instruction that only exists in the docs.
Anything that introspects our Dockerfile - a directory checking tool definitions, or your own CI -
has to select mcp; without it it finds a gateway that answers HTTP and no MCP server at all.
For MCP clients that connect by URL, the source build provides a loopback-only Streamable HTTP endpoint:
pnpm mcp:http
# http://127.0.0.1:3210/mcp
See the MCP server guide for remote-bind authentication and the published-release boundary.
Installable Agent Skill
codex plugin marketplace add happy520ai/unified-ai-system --ref master
npx skills add happy520ai/unified-ai-system --skill unified-ai-gateway --agent codex --copy --yes
The plugin pins the reviewed immutable v0.4.9 MCP image
and starts it without container networking or Linux capabilities. The current release has its own
content review, read from the published layer tarballs rather than a
Docker export - that page is where the linux/arm64 architecture caveat is written down.
Skill hub: https://skills.sh/happy520ai/unified-ai-system/unified-ai-gateway
For local source work:
Requires Node.js 22.18.0 or newer and pnpm 11.19.0.
git clone https://github.com/happy520ai/unified-ai-system.git
cd unified-ai-system
corepack enable
corepack prepare pnpm@11.19.0 --activate
pnpm install --frozen-lockfile
pnpm verify:public-clone
pnpm gateway demo
For a prepared cloud workspace, use GitHub Codespaces. See the value first:
pnpm gateway demo "Build a small API for my team" --enhance --profile coding --evidence
For the complete credential-free clone check, run pnpm verify:public-clone
after the demo. The repository's devcontainer keeps the default path
provider-free. Codespaces availability and usage limits are controlled by
GitHub.
Docker Compose
For a source checkout, start the gateway with a readiness check:
docker compose up --build -d
docker compose ps
curl http://127.0.0.1:3100/health/check
The service becomes healthy only after /health/check responds successfully.
When finished, stop it with:
docker compose down
The Compose file treats .env as optional and leaves provider behavior explicit;
the credential-free fake-provider path remains the default.
Share a Verified Result
If the project helps your workflow, run one reproducible path, star the repository, and share the smallest useful result through the structured Usage Report.
For a ready-to-review CLI packet, append --evidence to the enhanced demo:
pnpm gateway demo "Build a small API for my team" --enhance --profile coding --evidence
Review the original request and output before sharing the generated JSON. The
packet also records detectedSignals and the item count for each
compiledSections entry, so a reviewer can see which request signals were
carried into the structured prompt without reading internal logs.
For the browser Prompt Lab, use its Copy evidence or Download evidence
action, then paste or attach the JSON in the optional Prompt Lab evidence field
of the same report.
Use Copy share link when you want another browser to reproduce the same local
input, profile, and language; review the prompt first because the URL fragment
contains the input text.
Next Steps
- Documentation for setup, the CLI, prompt enhancement, and providers.
- Codex MCP quickstart for the fastest agent-tool integration; the source guide is kept in the repository.
- Self-hosted AI gateways, in their own words - LiteLLM, Portkey Gateway, Agent Router and this project, each quoted from its own README with the date it was read, plus three questions to ask before handing over agent traffic.
- Nine measurements of the public MCP ecosystem - 40 servers advertised in the official registry, asked anonymously: 0 of the 16 that answered paginate
tools/list, 2 of the 18 that answered agreed to a protocol version that does not exist, both servers that issue a session id require it back, and 1 of 16 implementsserver/discoverwhile 12 have never heard of it, and 9 of 16 send server-writteninstructionsprose to an anonymous client, 72 to 1,423 characters. 22 of the 40 would not talk to an anonymous client at all, and every page says so about its own denominator. Two findings have their own pages and are worth reading on their own terms: do servers say how long their tool list may be cached - 1 of the 16 that returned a list did, and we were reading neither field - and can a header redirect a server to a method the body never asked for - 0 of 16 POST pairs and 0 of 13 body-less GET legs, plus the false positive a repeat leg caught before it became a sentence. Each page ships its script, so any number here is yours to re-run in about two minutes, and the whole set is published as generated data: the 40-endpoint run of 2026-09-27, its nine-question, ten-leg re-run of 2026-09-28, and the wide run. Another question, measured later the same day in its own window, asks whether anyone enforces theMCP-Protocol-Versionheader - none of the 16 that answered did, which is also why closing our own gap on it was a conformance fix rather than an interoperability rescue. And one reading is a census rather than a sample: every server the registry's default list shows, counted - 123,831 version rows resolving to 37,013 servers, of which 439 (1.20%) declare neither a package nor a hosted endpoint, with the second walk published beside it because a number that cannot be repeated is an anecdote. - Contributing guide for focused changes and safe verification.
- Usage Report template for reproducible feedback.
- Cite this project, Roadmap, and Support.
Honest Boundaries
We separate what is verified from what is not claimed:
- Clean clone + fake-provider path: Yes
- Hosted public API: No
- Real provider execution by default: No, must be explicitly enabled
- Browser chat UI in this repo: No (CLI/API/MCP are first-class)
- Cold stdio handshake: ~8 s on the published source entry point, measured rather than estimated — where an MCP connect budget actually goes says which part is process boot, which part is tool work, and what that page does not establish.
- Production ready / AGI / L5: Not claimed
Real provider calls are disabled by default. Configure safely via .env.example and docs/providers.md.
Verify the Project
pnpm check
pnpm test
pnpm check:public
pnpm verify:public-clone
pnpm verify:mcp
CI on master runs Linux checks, container startup smoke tests, MCP discovery, and process-cleanup checks.
Project Links
Star History
If the gateway saves you a proxy migration or an afternoon of prompt cleanup, a star helps more people find it.