searxNcrawl
SearXNGインスタンスおよび/またはYou.comを介したウェブ検索に加え、Crawl4AIとPlaywrightを使用したページおよびサイトのクローリングにより、ログインが必要なページも含めてクリーンで重複排除されたMarkdownを生成します。ローカルで実行可能(uvx searxncrawl)、MITライセンス。
ドキュメント


Website · Quick start · Docs · Developers · Cloud (planned) · Changelog
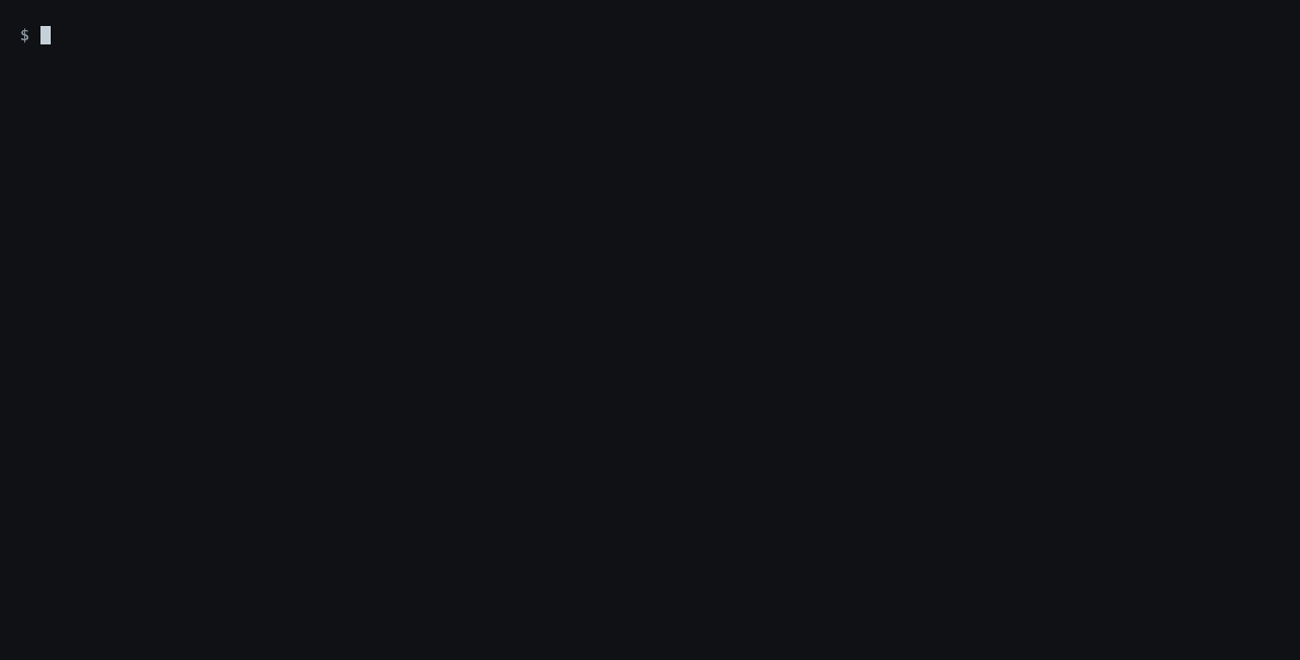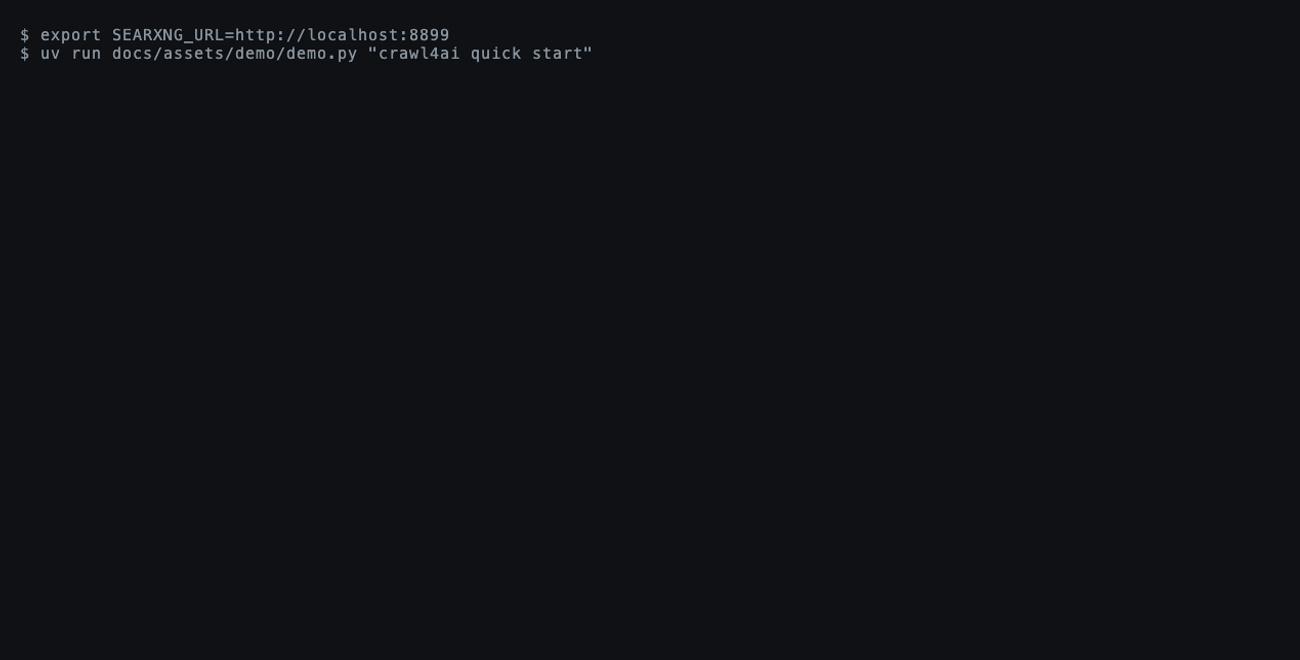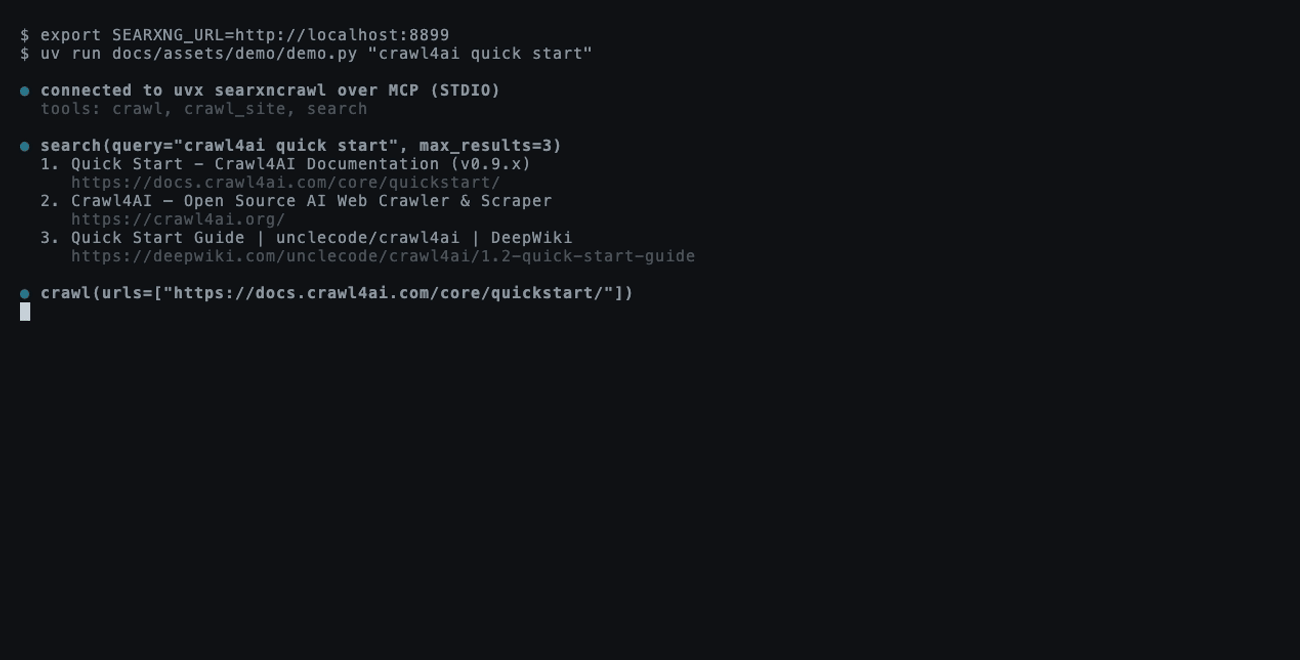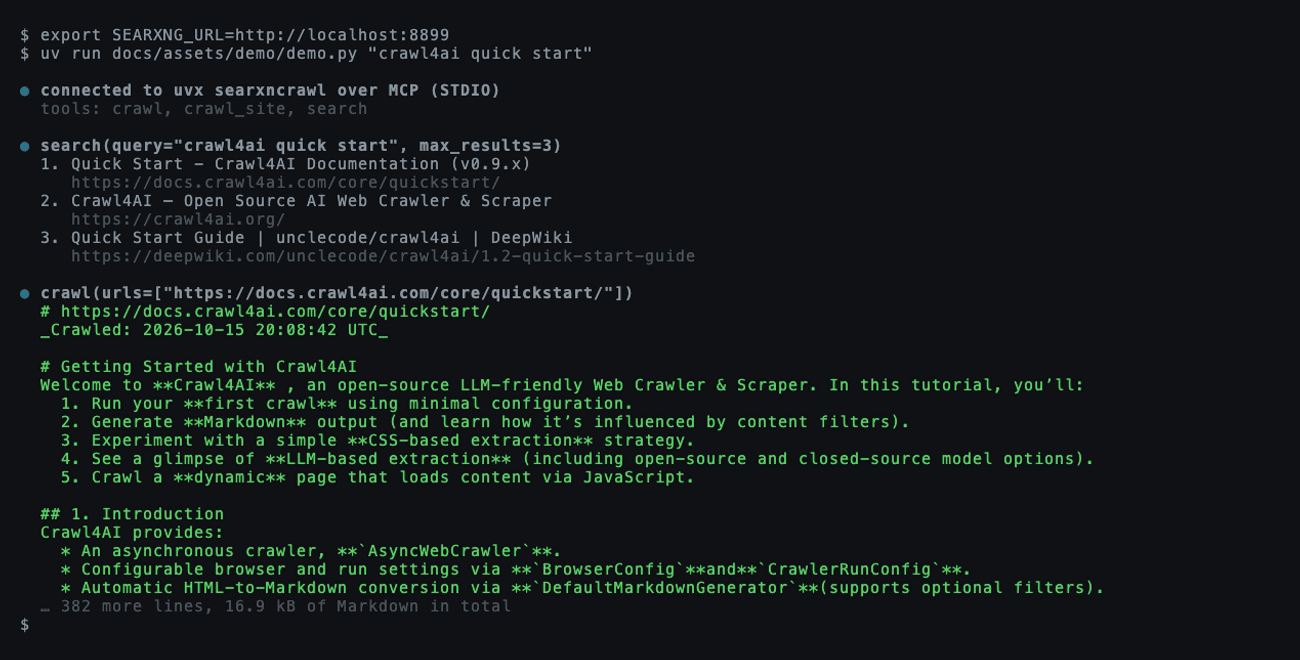
A real MCP client session (fastmcp) against uvx searxncrawl 0.31.0 and a local SearXNG: search, then crawl the top hit into Markdown. Output is shortened for display. Reproduce it with docs/assets/demo/.
searxNcrawl is an open-source MCP server and CLI toolkit that gives AI agents web search and clean Markdown crawling, built on Crawl4AI. Search queries the configured providers, SearXNG and/or You.com, in parallel and merges the results. It runs on your own hardware, needs no API key with SearXNG and succeeds searxng-mcp.
| Web search Your own SearXNG instance and/or the You.com API, queried in parallel; results are merged and attributed to their providers, filtered by language and time range. | Page crawl One or many URLs to Markdown or JSON, with repeated blocks removed and links optionally stripped. | Site crawl Whole sites with depth and page limits, tuned for documentation. |
| Authenticated crawls Capture a login session once with crawl-capture, then crawl behind the login. | STDIO and HTTP Plug into local MCP clients, or expose an HTTP endpoint with host and CORS guards. | CLI and Python APIcrawl, search and crawl-capture on the command line, or import it in Python. |
SEARXNG_URL=http://your-searxng:8888 uvx searxncrawl
Quick start
You need uv and, for the search tool, at least one search provider: a SearXNG instance with JSON output enabled and/or a You.com API key (YDC_API_KEY). No SearXNG yet? Start one with Docker. Crawling works without either.
Add it to your agent
One step for every agent on your machine
uvx searxncrawl setup
setup detects Claude Code, Codex, Gemini CLI, Cursor, VS Code and Claude Desktop, asks for your SearXNG URL and, optionally, a You.com API key (hidden input, never printed), shows each config change and applies it only after you confirm. Every file it touches is backed up first, and setup --remove undoes it. More options are in MCP server.
Or per agent

The buttons and commands below assume SearXNG at http://localhost:8888; change SEARXNG_URL if yours runs elsewhere, or add YDC_API_KEY for You.com.
Claude Code
claude mcp add searxncrawl --env SEARXNG_URL=http://localhost:8888 -- uvx searxncrawl
Codex
codex mcp add searxncrawl --env SEARXNG_URL=http://localhost:8888 -- uvx searxncrawl
VS Code
code --add-mcp '{"name":"searxncrawl","command":"uvx","args":["searxncrawl"],"env":{"SEARXNG_URL":"http://localhost:8888"}}'
Cursor (~/.cursor/mcp.json), Claude Desktop and other clients that use the mcpServers format
{
  "mcpServers": {
    "searxncrawl": {
      "command": "uvx",
      "args": ["searxncrawl"],
      "env": { "SEARXNG_URL": "http://localhost:8888" }
    }
  }
}
The first crawl downloads Playwright's Chromium once (about 550 MB). For Docker, HTTP transport and other setups see Installation and MCP server.
Ask your agent
Search for the Crawl4AI quick start, crawl the official page and summarise
how to run a first crawl.
Your agent calls search, picks a result and calls crawl. It gets back clean Markdown instead of raw HTML.
Use the terminal
uvx --from searxncrawl crawl https://modelcontextprotocol.io/docs/getting-started/intro
SEARXNG_URL=http://localhost:8888 uvx --from searxncrawl search "model context protocol" --max-results 5
How it works
flowchart LR
    agent["AI agent<br/>Claude Code · Codex<br/>Cursor · VS Code"]
    server["searxNcrawl<br/>MCP server"]
    searxng["SearXNG (your instance)<br/>and/or You.com API"]
    browser["Crawl4AI +<br/>Playwright Chromium"]
    results["Merged results<br/>attributed per provider"]
    markdown["Deduplicated<br/>Markdown or JSON"]

    agent -- "MCP · STDIO or HTTP" --> server
    server -- "search" --> searxng --> results
    server -- "crawl · crawl_site" --> browser --> markdown
Results return to the agent as the tool response. Search and crawling are also available as the search and crawl CLI commands, crawling also as a Python API.
searxNcrawl exposes three MCP tools:
| Tool | What it does |
|---|---|
search | Queries the configured providers (SearXNG, You.com) in parallel and returns one merged, deduplicated list with the source of each result. Filters: language, time range, safe search, paging; categories and engines for SearXNG. |
crawl | Renders one or many URLs in Chromium and returns Markdown or JSON with metadata and references. |
crawl_site | Follows links from a seed URL within depth, page and timeout limits, tuned for documentation sites. |
Both crawl tools drop sections that repeat within a page's Markdown (dedup_mode="exact"), can strip links for a smaller context (remove_links), and accept a Playwright storage_state for pages behind a login. Full parameters are in the MCP tools reference.
Why searxNcrawl
Hosted search and crawl APIs are quick to start with, but every call goes through someone else's service and is billed per request or credit. searxNcrawl runs on your own machine or server.
| searxNcrawl | Firecrawl | Tavily | Exa | |
|---|---|---|---|---|
| Search and crawl run on your hardware | ✅ Python package or Docker; You.com queries go to You.com | ✅ Self-host stack (Docker Compose), or hosted API | ❌ Hosted API | ❌ Hosted API |
| API key | Not needed with SearXNG; You.com needs one | Hosted API: needed. Self-hosted: not by default | Needed | Optional, anonymous use is rate-limited |
| Cost per call | None with SearXNG; You.com per its plans | Hosted: free monthly credits, then paid credits. Self-hosted: none | Free monthly credits, then paid credits | Free monthly credits, then paid per request |
| Search backend | Your SearXNG (the engines you enable) and/or You.com | Hosted: Firecrawl's search. Self-hosted: SearXNG if configured, otherwise DuckDuckGo | Tavily's search API | Exa's search index |
| Licence | MIT | AGPL-3.0 | MCP server MIT, API proprietary | MCP server MIT, API proprietary |
Self-hosted Firecrawl can search through SearXNG too; it runs as a multi-service stack (API, Playwright service, Redis, RabbitMQ, PostgreSQL and more), while searxNcrawl is a single Python process with Chromium, plus your SearXNG instance if you use one. A Firecrawl-compatible API for searxNcrawl is planned.
Where the others are a better fit: if you do not want to run a search provider and a browser yourself, a hosted API is less work, and Exa's semantic search index or Firecrawl's extraction features go beyond what searxNcrawl does today. Comparison based on each project's public repository and documentation in October 2026; corrections are welcome. Firecrawl is a trademark of its owner; searxNcrawl is not affiliated with it.
FAQ
Do I need SearXNG?
Only for the search tool, and only if you do not use You.com (YDC_API_KEY). crawl and crawl_site work without any search provider. SearXNG serves HTML only by default, so JSON output must be enabled (search.formats in settings.yml). Public instances may not enable it and often rate-limit automated requests, so run your own. Installation has a Docker one-liner.
Does it handle JavaScript-heavy pages?
Yes. Pages are rendered in Playwright's Chromium through Crawl4AI before they are converted to Markdown, so client-side content is captured.
Can it crawl pages behind a login?
Yes. Capture a session once with crawl-capture, then pass the saved storage_state file to crawl or crawl_site. See Session capture.
Can I run it remotely or share it with a team?
Yes. Start it with --transport http (port 8000 by default) or use the Docker Compose stack (port 9555), then point your MCP clients at http://<host>:<port>/mcp. Host and Origin allowlists guard the endpoint; see MCP server.
Why is the first crawl slow?
The first crawl downloads Playwright's Chromium (about 550 MB on disk). Later runs reuse it. Set PLAYWRIGHT_AUTO_INSTALL=false where browsers are provisioned separately.
I used searxng-mcp. What changed?
searxng-mcp is deprecated in favour of searxNcrawl. It only searched SearXNG and could pick a random public instance; searxNcrawl adds page and site crawling but needs your own SEARXNG_URL (or a You.com key), as random public-instance selection is not included.
Is there a hosted version?
Not yet. searxNcrawl Cloud is planned; see the roadmap.
Roadmap
- Firecrawl-compatible API (planned): use searxNcrawl as a drop-in backend for tools built against the Firecrawl API.
- searxNcrawl Cloud (planned): a managed endpoint for teams that do not want to run SearXNG and a browser. Details and waitlist.
Ideas and votes are welcome in Discussions.
Documentation
| Guide | Contents |
|---|---|
| Installation | uvx, Docker Compose, pip, uv, search providers and environment variables |
| MCP server | STDIO and HTTP transports, client configuration, Host and CORS guards |
| MCP tools | Parameters for crawl, crawl_site and search |
| CLI | crawl, search and crawl-capture |
| Python API | crawl_page, crawl_site and crawler configuration overrides |
| Output formats | Markdown and JSON structure, CrawledDocument |
| Session capture | Authenticated crawling with a saved browser session |
| MCP Registry | server.json and the publish steps |
| Architecture | Modules and features for contributors |
Contributing
Bug reports, feature ideas and pull requests are welcome. Read the contributing guide and open an issue first for larger changes. Coding agents find project conventions in AGENTS.md. Report vulnerabilities privately as described in the security policy.
License
MIT — © 2026 DDM – Das Digitale Momentum GmbH & Co KG
Maintained by DDM – Das Digitale Momentum GmbH & Co. KG, Much, Germany · www.searxncrawl.io · All our open-source projects