playwright-e2e-mcp
the "Short" text
Documentation
playwright-e2e-mcp
The test doctor for AI agents.
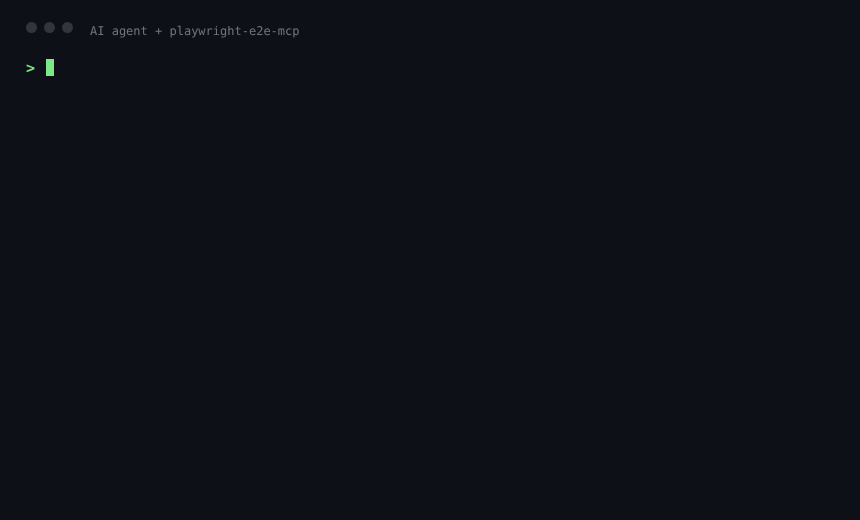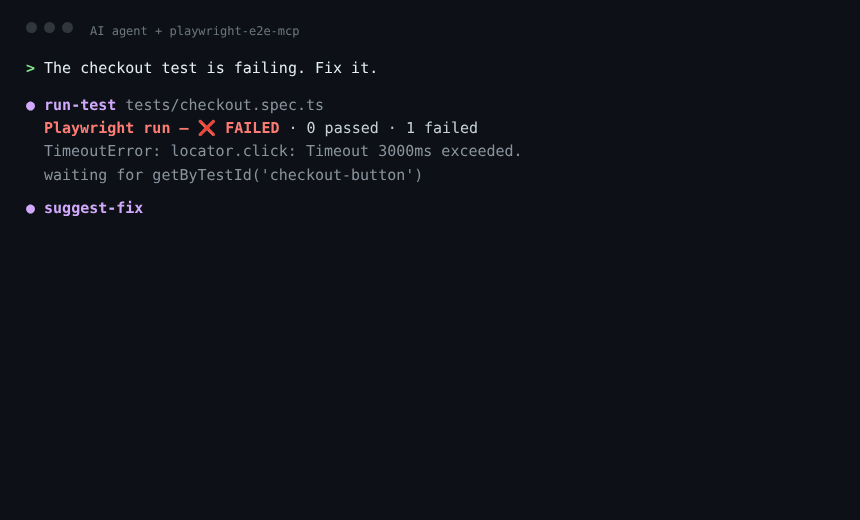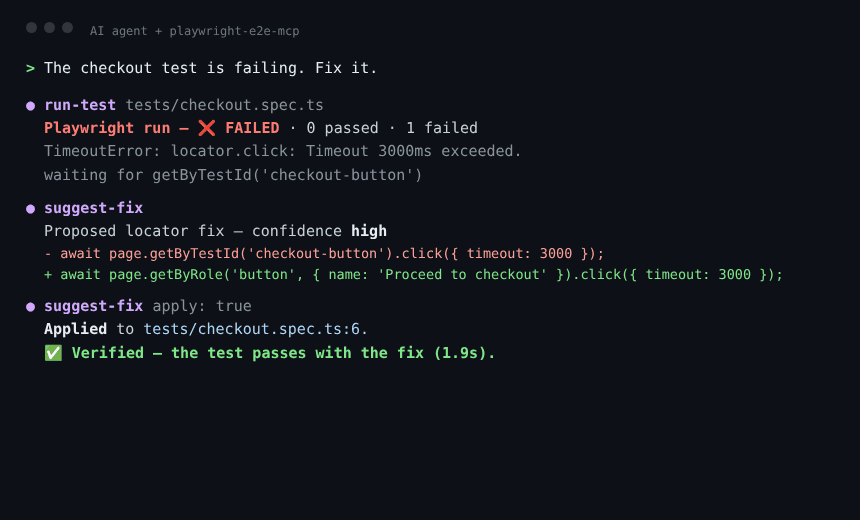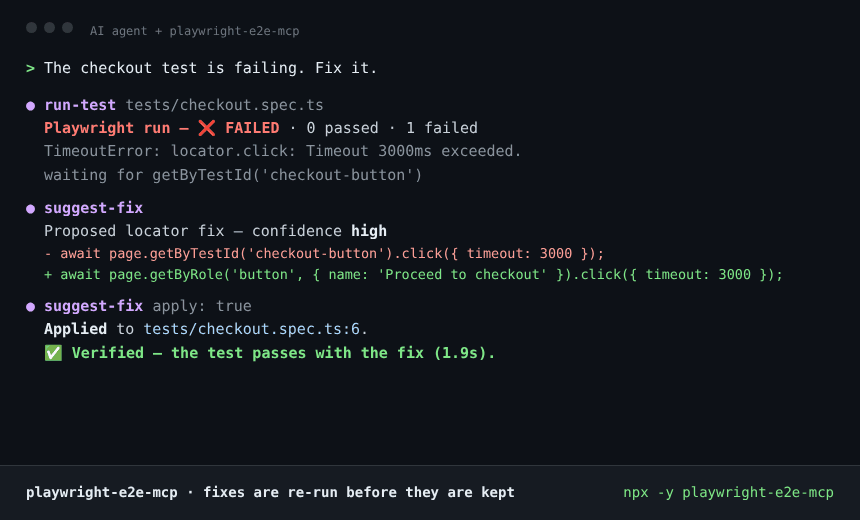
Your Playwright test fails. Your AI finds out why, fixes it, and proves the fix works, or tells you it's a real bug.





⭐ If it saves you a debugging session, a star helps other Playwright users find it.
Quick start · Features · Tools · Tool reference · GitHub Action · Benchmark · Changelog
An MCP server and agent skill that gives Claude, Cursor, VS Code Copilot, Codex, Gemini and any other MCP client a full Playwright toolkit: a test runner, a failure detective and a fixer that checks its own work. Browser MCPs let an AI click around a page. This one lets it keep your test suite green, for TypeScript and Python suites, on your laptop and in CI. Free, MIT, no account.
❌ Without it / ✅ With it
Without it, your agent sees Timeout 5000ms exceeded waiting for getByTestId('checkout'),
guesses a new selector, edits the test and hopes. Or it "fixes" the test by deleting the
assertion that caught a real bug.
With it, your agent reads the page as it was when the test failed (from the Playwright trace), swaps in a locator proven unique on that page, re-runs the test and keeps the edit only if it passes. When the button is really gone, it says so: that's an app bug, not a test to patch. And a heal guard blocks any "fix" that went green by checking less.
flowchart LR
  A["run-test<br/>or load-report (CI)"] --> B["get-failure<br/>DOM at failure, requests, console"]
  B --> C{"suggest-fix"}
  C -->|"locator proven on the page"| D["apply + re-run"]
  D -->|green| E["✅ fixed and verified"]
  D -->|still red| F["↩️ edit reverted"]
  C -->|"element really gone"| G["🐞 reported as an app bug"]
  D -.-> H["check-test-change<br/>blocks fixes that check less"]
⚡ Quick start
Run this in your project root. It adds the server to every MCP client config it finds (Claude Code, Cursor, VS Code, Gemini CLI, Codex), installs the agent skill and leaves your other servers alone:
npx -y playwright-e2e-mcp init      # --client all | cursor,vscode … · --dry-run
npx -y playwright-e2e-mcp doctor    # checks Node, Playwright, browsers, client setup and updates
Then restart your client and ask:
Run my Playwright tests and fix whatever fails.
Or let your agent install it. Paste this into any coding agent:
Install the playwright-e2e-mcp server and skill by following https://raw.githubusercontent.com/xsignon-secure/E2E/main/llms-install.md
Or add the standard config by hand (works in most clients):
{
  "mcpServers": {
    "playwright-e2e": {
      "command": "npx",
      "args": ["-y", "playwright-e2e-mcp"]
    }
  }
}
Needs: Node.js 22+, and a project with @playwright/test and a browser
(npx playwright install chromium) or with pytest-playwright.
The server uses its working directory as the project root; if your client starts it elsewhere,
add "env": { "PW_MCP_PROJECT_ROOT": "/path/to/your/project" }.
Claude Code
Server and skill, as a plugin:
/plugin marketplace add xsignon-secure/E2E
/plugin install playwright-e2e-mcp@xsignon-secure
Or the server only:
claude mcp add playwright-e2e -- npx -y playwright-e2e-mcp
Claude Desktop
Download the .mcpb extension from the latest release
and double-click it. It ships its own dependencies, so no Node setup is needed. On install it
asks for your project root: choose the project folder, not your home directory.
You can also add the standard config to claude_desktop_config.json.
Cursor
Click Install in Cursor,
or go to Settings → MCP → Add new MCP server and paste the standard config. For one
project only, put it in .cursor/mcp.json.
Only fixing failing tests? Install the core tools only: the seven-tool fix loop
(--tools=core), about 2.3k tokens of tool definitions instead of 12.1k.
VS Code / GitHub Copilot
Click the Install in VS Code button above, or run:
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","playwright-e2e-mcp"]}'
Codex
codex mcp add playwright-e2e -- npx -y playwright-e2e-mcp
A Playwright run with retries can take longer than Codex's default 60 s tool timeout. Raise
the timeouts in ~/.codex/config.toml:
[mcp_servers.playwright-e2e]
command = "npx"
args = ["-y", "playwright-e2e-mcp"]
startup_timeout_sec = 60
tool_timeout_sec = 600
Gemini CLI / Qwen Code
Server and skill, as an extension:
gemini extensions install https://github.com/xsignon-secure/E2E
Or paste the standard config into .gemini/settings.json (Qwen Code: .qwen/settings.json).
Windsurf, Cline, Zed, Freebuff and other clients
Add the standard config to the client's MCP config file (Cline: MCP Servers → Configure).
Clients that take a command, such as Zed, run npx with the arguments -y playwright-e2e-mcp.
Freebuff / Codebuff: drop an mcp.json with the standard config into your project's .agents/
folder. This repo ships one in .agents/mcp.json; Freebuff asks you to trust
a repository's .agents/ on first run.
ChatGPT, claude.ai and other remote-only clients
Some clients only accept a remote HTTPS server. This repo ships a Streamable HTTP bridge you can host for free on Vercel, with OAuth sign-in for claude.ai connectors (dynamic registration and Client ID Metadata Documents). See Hosted endpoint. On Vercel the page tools (inspect a page, check selectors, accessibility and Web Vitals audits) run on a bundled Chromium against public URLs. Running and fixing your own tests needs your project, so use the local install for that.
Other ways to install: skill only, Docker, registry, tarball
| Route | How |
|---|---|
| Skill only, any agent | npx skills add xsignon-secure/E2E |
| MCP Registry | io.github.xsignon-secure/E2E (listing); registry-aware clients find it there |
| Docker | docker run -i --rm -v "$PWD:/work" ghcr.io/xsignon-secure/playwright-e2e-mcp (published on each release; see Development) |
| Straight from GitHub, no npm | npx -y github:xsignon-secure/E2E#v0.15.0 (pin a release tag) |
| Release tarball | npm install -D https://github.com/xsignon-secure/E2E/releases/download/v0.15.0/playwright-e2e-mcp-0.15.0.tgz |
| Local checkout | "command": "node", "args": ["/path/to/E2E/dist/index.js"] |
Updating
| Installed with | To update |
|---|---|
npx -y playwright-e2e-mcp (the setup above, and what init writes) | Restart your MCP client. npx (npm 10, which comes with Node 22) asks npm for the latest version on each launch and fetches it. |
npm install -D playwright-e2e-mcp in the project | npm install -D playwright-e2e-mcp@latest |
npm install -g playwright-e2e-mcp | npm install -g playwright-e2e-mcp@latest |
GitHub Action uses: xsignon-secure/E2E@v0.x.y | Change the tag (Dependabot's github-actions updates do it for you) |
| Docker | docker pull ghcr.io/xsignon-secure/playwright-e2e-mcp:latest |
Claude Desktop bundle (.mcpb) | Download the new bundle from the latest release and open it |
| Git clone | git pull && npm ci |
Agent skill copied by init or npx skills add | Run the same command again |
npx -y playwright-e2e-mcp doctor tells you whether a newer version is out and prints the
command for your setup. Upgrade notes for each release are on the
releases page.
💬 What you can ask
| You ask your AI… | It does this | |
|---|---|---|
| 🏃 | "Run my tests" | Runs the suite and reports every failure with file, line, cause and a fix hint. One root cause breaking 30 tests shows up as one problem. |
| 🔍 | "Why did this fail?" | Reads Playwright's trace: the page at the moment of failure, the broken request, the console error. No guessing. |
| 🛠️ | "Fix it" | Swaps in a locator proven unique on that page, re-runs the test and undoes the edit if it's still red. If the element is really gone, it tells you it's an app bug. |
| ☁️ | "Why did CI fail?" | Loads the CI job's report (sharded blob reports too) and its traces, so the same diagnosis and fixes work on CI failures. |
| 🎲 | "Is this test flaky?" | Re-runs it with retries off, alone and in shuffled order, and names the race, the shared state or the test it depends on, with the seed that reproduces it. |
| 🎯 | "Which commit broke this?" | Bisects git history in a throwaway worktree and names the first bad commit, its diff and the failure there. |
| 📈 | "What's been breaking lately?" | Ranks flaky, newly broken and slow tests from the run history and names the commit where each went bad. |
| 🧊 | "Quarantine this flaky test" | Keeps it running and reported but stops it failing the build, with an owner and an expiry date. |
| 🛡️ | "Did that fix cheat?" | Compares the changed tests with git and blocks a fix that passes by deleting assertions, skipping tests or adding .only. |
| ✍️ | "Write a test for this flow" | Walks the steps on the live page, writes a spec with real locators and assertions on where the flow landed, and runs it once to prove it passes. |
| 🔑 | "Log in and save the session" | Signs in once, 2FA codes included (generated from your TOTP secret), checks the session and saves it. The password never passes through the chat. |
| ♿ | "Check this page for accessibility" | Runs axe-core (WCAG 2.2 AA) and returns each problem with a verified locator and a ready regression test. |
| ⚡ | "Why is this page slow?" | Measures Web Vitals (LCP, CLS, INP, TBT) on desktop or a throttled phone, names the slow and shifting elements, and hands back a budget test. |
| 🐍 | "Run my pytest suite" | Runs pytest-playwright projects with the same failure diagnosis and traces. |
✨ What you get
🩺 A fix loop that proves itself
- Fixes are verified, not guessed.
suggest-fixpicks a locator proven unique on the DOM at failure, writes it, re-runs the test and reverts if it's still red. Strict-mode violations get the locator of the intended match; changed copy gets the new expected text. - Honest about real bugs. When the element is really gone, it refuses to patch the test and reports an app bug.
- Heal guard.
check-test-change(andplaywright-e2e-mcp guardin CI) blocks a "fix" that went green by deleting an assertion, skipping the test, adding.only, swallowing the error or moving an assertion under anif, and warns on weaker matchers, hard waits, forced clicks, early returns and raised timeouts.runtime: truealso runs the old and new version and blocks a test that now executes fewer assertions, which catches what no code scan can. Works for pytest-playwright files too. - Asks before it writes. Applying a fix, writing a test, quarantining or replacing a visual
baseline shows you the exact diff and waits for your yes in clients that support MCP
questions (
PW_MCP_CONFIRM_WRITES).
🔬 Flaky tests, history and the breaking commit
- Flaky verdicts with evidence.
diagnose-flakytells a race from shared state from a test-order dependency, and gives the seed that replays it. - Quarantine with an owner and an expiry. The test keeps running and being reported; it stops blocking the build until the date you set.
- Memory of every run.
analyze-historyranks flaky, regressed, broken and slow tests and names the commit where each went bad. Share one history across every CI job and laptop with the free, self-hosted history server (onedocker run, dashboard included). bisect-failurefinds the first bad commit without touching your checkout.audit-testsfinds flake risks in the test code (hard waits, one-shot assertions, missingawaits, fragile selectors, clicks right aftergotoon a server-rendered app), ranks them by real flakiness and applies the safe rewrites with a verifying run.
⚡ Hydration races and stale mocks
- The "too fast" click. On Next.js, Nuxt, Remix, Astro and other server-rendered apps the HTML
is clickable before JavaScript attaches its handlers, so a test clicks, the step passes and
nothing happens.
inspect-pagenames the framework and measures how long controls were on screen before hydration;get-failureanddiagnose-flakyflag a click made while the page's scripts were still downloading and hydration errors in the console; each comes with the wait to add. - Mocks that drifted from the API.
check-mocks(andplaywright-e2e-mcp mocksin CI) finds everyroute.fulfillJSON body androuteFromHARrecording, calls the real endpoint (GET only) and reports the fields the mock relies on that the API no longer sends, changed types, new nulls and removed endpoints, so a green suite stops hiding a broken contract.
🔗 CI runs by URL, remote browsers, Python fixes and AI chat UIs
-
Paste the CI run, skip the download. Give
load-reporta GitHub Actions run or GitLab job URL. It fetches the report and traces with your ownGITHUB_TOKEN/GITLAB_TOKEN, maps them onto your checkout, andget-failureandsuggest-fixwork on that run.{ "report": "https://github.com/acme/shop/actions/runs/123456789" } -
Any browser, anywhere. The page tools take
connect: a Playwright server (npx playwright run-server), a browser grid or device cloud, or a Chrome over CDP. Keys stay in the environment as{{env:…}}, never in chat, and only go to hosts you named inPW_MCP_CONNECTorPW_MCP_CONNECT_HOSTS.{ "url": "https://staging.example.com", "connect": "wss://grid.example.com/playwright?key={{env:E2E_GRID_KEY}}" } -
Fixes for pytest suites.
suggest-fixnow patchestest_*.pyfiles in Python syntax and re-runs the test with pytest before keeping the change:- page.get_by_test_id("checkout-button").click() + page.get_by_role("button", name="Checkout").click() -
AI chat and streaming UIs. The agent skill shows how to test answers that stream in: mock the model's stream, wait for the "done" signal instead of the text, and check shape rather than exact wording against a live model.
await expect(page.getByRole('button', { name: 'Stop' })).toBeHidden();
await expect(page.getByTestId('message').last()).toHaveText('Hello, world!');
🤖 CI that comments with working fixes
- GitHub Action that writes the diagnosis to the job summary, keeps one PR comment up to date and posts each verified fix as a suggested change reviewers apply with one click.
- CI templates for GitHub Actions, GitLab, Azure DevOps, CircleCI, Bitbucket and AWS CodeBuild, and a plain
cicommand for anything else. - Diagnose CI locally:
load-reportmaps a CI job's report and traces onto your checkout.
🌐 Page tools with locators that already work
inspect-pagereturns a compact map of verified Playwright locators (about 570 tokens for a storefront page, against 2,300 for a Playwright MCP snapshot), or the full DOM inventory, or the accessibility snapshot with a readytoMatchAriaSnapshotassertion.- Reaches the hard screens: saved logins, headers, click and fill steps, popups and new tabs, API mocks (500s, empty lists, slow calls), HAR record and replay, phone and tablet presets, Chromium, Firefox, WebKit, Chrome and Edge.
- Look without changing anything:
blockWritesstops POST, PUT, PATCH and DELETE requests from reaching a real backend, andblockResourcesskips images, fonts and trackers for faster, private page checks.offline: truecuts the network after load to test offline states. - Accessibility, Web Vitals and visual diffs that return locators and ready tests, not just a score.
🚀 Built for agents in 2026
- Lean on context. Start with
--tools=auto(about 2.4k tokens of tool definitions instead of 12.1k) and the agent loads the page, audit or history tools when it needs them, or pick a profile:core,triage,inspect,author. - Interactive test report in MCP Apps clients (Claude, ChatGPT, Cursor): filter failures, see expected vs. received, re-run or "Ask to fix" in one click.
- Current MCP: the stateless 2026-07-28 revision (2025 clients still work), structured results with output schemas, tool annotations for accurate safety prompts, the skill served over the Skills extension, and a Server Card for discovery.
- Everywhere you work: npm, Claude Code plugin, Claude Desktop bundle, Gemini CLI extension, Docker image on GHCR, and an HTTP bridge with OAuth for remote-only clients.
🧰 Tools
| Tool | Purpose |
|---|---|
run-test | Run Playwright tests and return stats, failures grouped by root cause, diagnostics and hints; background: true returns a run id for long suites |
get-run-status | Progress or final result of a background run; can wait for it or cancel it |
get-failure | Deep analysis of one failure: stack, expected/actual, DOM snapshot at failure (from the trace), failed requests, console errors, next steps |
load-report | Load a run from CI (JSON report, sharded blob reports, or straight from a GitHub Actions run or GitLab job URL), map its paths onto the checkout and find the traces, so every other tool works on it |
suggest-fix | Patch a failure with a locator proven unique on the DOM at failure or the new expected text; apply: true writes it, re-runs and reverts if still red |
check-test-change | Heal guard: BLOCK deleted assertions, skipped or removed tests, .only and assertions moved under an if; WARN on weaker matchers, hard waits, force: true, swallowed errors, early returns. runtime: true compares the assertions that actually ran. TS/JS and pytest |
check-mocks | Mock drift: compare every route.fulfill JSON mock and HAR recording with the live API (GET only) and report missing fields, changed types, new nulls and removed endpoints |
diagnose-flaky | Run a test 2–10 times with retries off and return CONSISTENTLY FAILING, FLAKY or NOT REPRODUCING; tells parallelism and test-order bugs from races |
quarantine | Quarantine a flaky test with an owner, a reason and an expiry (default 14 days); it keeps running but stops failing run-test and ci |
analyze-history | Rank flaky, regressed, broken and slow tests, group failures by cause, show stability by day and the commit where each test went bad |
bisect-failure | Find the commit that broke a test: binary-search git history in a temporary worktree (your checkout is untouched) |
audit-tests | Audit the test code for flake risks, ranked by real flakiness; fix: true rewrites the mechanical ones and verifies with a re-run |
list-tests | List tests (file, line, full title, projects) with filtering |
inspect-page | Open a URL (optionally signed in, after steps) and return verified locators, the full element inventory, or the ARIA snapshot with a ready assertion; reports the framework and the hydration gap on server-rendered pages |
validate-selector | Check a CSS selector, Playwright selector or locator expression on a live page: match count and a sturdier verified locator for each match |
generate-e2e-test | Scaffold a test with the project's real selectors, or walk a flow on the live page and write a spec that is run once to prove it passes |
save-login | Log in once and save the session with {{env:E2E_PASSWORD}} and {{totp}} (2FA codes); reused until it expires; secrets never pass through the chat |
audit-accessibility | axe-core (WCAG 2.2 AA) violations, worst first, with verified locators and a regression check |
audit-performance | Lab Web Vitals (LCP, CLS, TBT, FCP, TTFB, INP), optionally as a throttled phone; names the LCP and shifting elements and returns a budget test |
compare-visual-state | Visual regression: screenshot before/after a change and report what moved and how colors shifted |
With --tools=auto, a load-tools tool turns on more tools mid-session. Two prompts,
fix-failing-test and triage-flaky-tests, package the main workflows as slash commands. Every
argument and example output is in the tool reference.
Typical workflow
run-test{ "testFiles": ["tests/checkout.spec.ts"] }, or{ "background": true }for a long suite andget-run-status{ "waitSeconds": 30 }until it finishes. For a failure from CI, callload-reportwith the run URL{ "report": "https://github.com/acme/shop/actions/runs/123" }(needsGITHUB_TOKEN; GitLab job URLs needGITLAB_TOKEN), or with the artifacts you downloaded{ "report": "ci-artifacts/results.json" }.get-failure{ "index": 1 }to read the code frame, expected/actual, the DOM snapshot at failure, the failed network requests and the page's console errors.suggest-fix{ "index": 1 }for a locator or copy change: review the diff, then{ "index": 1, "apply": true }to write it and verify with a re-run. If it reports the element is missing, fix the app, not the test.- For anything it cannot patch:
inspect-page{ "url": "…" }(addstorageStateoractionsto reach the right screen), thenvalidate-selectorto prove the new locator before editing. - If a failure looks intermittent:
diagnose-flaky{ "runs": 3 }for fresh evidence, andanalyze-history{ "view": "commits" }to see where it went bad. - Re-run only what failed with
run-test{ "lastFailed": true }until green.
To write a new test, call generate-e2e-test with a description and the steps of the flow;
it walks them on the live page, writes the spec and runs it once.
🤖 CI: GitHub Action, GitLab and any CI
The same diagnosis runs without an agent. On a pull request the Action re-runs each failing test with its suggested fix and posts the fixes that pass as suggested changes on the failing lines, so a reviewer applies one with the Commit suggestion button:
permissions:
  contents: read
  pull-requests: write   # for the PR comment and the suggested fixes
steps:
  - uses: actions/checkout@v6
  - uses: actions/setup-node@v6
    with: { node-version: 24 }
  - run: npm ci && npx playwright install --with-deps chromium
  - uses: xsignon-secure/E2E@v0.15.0
    with:
      flaky-runs: 3      # 0 skips the flaky verdict
      suggest: 2         # suggest-fix diffs for the first 2 failures
      # guard: true      # fail the job if a test was made to pass by checking less
- Ready-to-copy workflows: GitHub Actions (artifact upload, heal guard, history server), GitLab CI (heal guard on merge requests and a merge request comment), Azure DevOps, CircleCI, Bitbucket Pipelines and AWS CodeBuild (heal guard on pull requests, reports as artifacts).
- Any other CI (Jenkins, Buildkite, TeamCity):
npx -y playwright-e2e-mcp ci --flaky-runs 3 --suggest 2 --output report.md. Exit code0passed,1tests failed,2the run itself failed. Quarantined, unexpired failures don't fail it. - Heal guard without the Action:
npx -y playwright-e2e-mcp guard --base origin/main(exit 1 on BLOCK;--strictfails on warnings too). - Mock drift check:
npx -y playwright-e2e-mcp mocks --base-url https://staging.example.comagainst a preview or staging deploy (exit 1 on drift;--mapgives wildcard routes a real URL,--header "Authorization: Bearer $TOKEN"signs the calls). - Team history across machines: run the free history server and
give the Action
history-urlandhistory-token; every CI run lands in one history thatanalyze-historyon your laptop and the server's dashboard both read.
Action inputs: project-root, args, flaky-runs, suggest, comment, review,
verify-fixes, guard, history-token, history-url, fail-on-failure, version,
github-token. Outputs: exit-code, report, guard.
🐍 Python projects (pytest-playwright)
When the project has no Node Playwright but has pytest settings (pytest.ini, pyproject.toml,
setup.cfg, tox.ini) or a conftest.py, the tools run python -m pytest instead.
What works for Python
run-testruns the suite, a file,tests/test_cart.py::TestCart::test_addortests/test_cart.py:42(the test at that line).grepbecomes-k,browserbecomes--browser,retriesuses pytest-rerunfailures. Failures that finished are kept even when the run is killed.get-failureshows the message, the code frame, expected vs actual and, from the trace pytest-playwright keeps (--tracing retain-on-failureis added for you), the failed action, the DOM at failure, network and console.list-tests,analyze-history,quarantineand thecicommand work as for Node.check-test-change(the heal guard) readstest_*.pyfiles: deletedasserts andexpects,@pytest.mark.skip/xfail,try: … except: passaround an assertion, weaker matchers,wait_for_timeout,force=True.check-mocksreadsroute.fulfill(json=…),body=json.dumps(…)andbody='{…}'.suggest-fixpatches.pyfiles too: the new locator is written in Python syntax (get_by_role("button", name="Buy")) and verified with a pytest re-run. It checks the locator on the DOM at failure with Node Playwright, like the page tools.diagnose-flakyrepeats pytest tests (one pytest process per run) for the same per-test verdicts.isolate: trueruns them in parallel with pytest-xdist (-n) first, then alone.orderneeds Playwright's shuffle and is Node only.audit-testsreadstest_*.py/*_test.pywith Python rules:wait_for_timeout,time.sleep, one-shotassert loc.is_visible()(rewritten toexpect(loc).to_be_visible()withfix: true), un-awaited calls inasync deftests,force=True,networkidle,query_selector, layout selectors,timeout=0.generate-e2e-testwritestests/generated/test_<name>.pywith Python locators. Withstepsit walks the flow, writes the module and runs it once with pytest. The start URL comes frompageUrlorbase_urlin your pytest config (pytest-base-url).- The page tools and
suggest-fixdrive the browser with Node Playwright. A Python project needs nothing extra: the server brings its ownplaywright-core. If it reports a missing browser, run the command it gives once (npx -y playwright@<version> install chromium).
Results come from a small pytest plugin the server loads with -p from its temp folder; nothing
is installed in your project. It uses your Python: PW_MCP_PYTHON, else .venv, venv or env
in the project, else python3 / python.
pip install pytest-playwright && playwright install chromium
⚙️ Configuration
Pick your tools. --tools= (or PW_MCP_TOOLS) takes profiles and tool names:
auto (core loop plus load-tools, about 2.4k tokens), core (the seven-tool fix loop, about
2.3k), triage, inspect, author, or all twenty (about 12.1k, the default).
Environment variables
| Environment variable | Default | Purpose |
|---|---|---|
PW_MCP_PROJECT_ROOT | server cwd | Default project root for every tool |
PW_MCP_TOOLS | all | Which tools to expose, as tool names and/or profiles, comma separated (same as the --tools= flag). Profiles: core (run, status, failure, fix, flaky, heal guard, list), triage (run, status, failure, CI report, flaky, history, test audit, bisect, quarantine, heal guard, mock check, list), inspect (page, selector, accessibility, performance, visual, login), author (list, page, selector, generate, run, login, heal guard, mock check). auto starts with the core loop (or the tools listed with it, e.g. auto,inspect) plus a load-tools tool the agent calls to turn on more tools for the session; the client is told the tool list changed. auto needs a client that refreshes its tool list (Claude Code, Cursor, VS Code); over the hosted HTTP endpoint it lists every tool. All twenty tool definitions cost the model about 12.1k tokens per request and core about 2.3k (the full tools/list, with output schemas most clients do not show the model, is about 16.8k and 4.9k) |
PW_MCP_OUTPUT_SCHEMAS | on | 0 leaves the output schemas out of the tool list to save context. Results still carry structuredContent (see Structured results) |
PW_MCP_PROTOCOL | both | legacy stops offering the stateless 2026-07-28 MCP revision, for a client that trips over it. By default 2026 clients get it and 2025 clients get the old handshake |
PW_MCP_NO_UPDATE_CHECK | off | 1 stops doctor from asking npm whether a newer version is out (same as doctor --offline) |
PW_MCP_CONFIRM_WRITES | auto | Ask before a tool changes your files (suggest-fix apply, audit-tests fix, a new test from generate-e2e-test, quarantine add/remove, replacing a visual baseline). auto asks when the client can show a question (MCP elicitation) and writes as before when it can't; always refuses to write when the client can't ask; off never asks. The question shows the exact diff, and a yes only covers that diff |
PW_MCP_APPS | 1 | Show an interactive test report next to run-test, get-run-status and get-failure results in clients that support MCP Apps (Claude, ChatGPT, Cursor). The report filters failures, shows expected vs. received, and re-runs or asks to fix a test with one click. 0 turns it off; other clients show the text result as before |
PW_MCP_SKILLS | on | 0 stops serving the bundled agent skill over the MCP Skills extension (skill://playwright-e2e-mcp/SKILL.md) |
PW_MCP_STORAGE_STATE | — | Default storageState file (inside the project) for the page tools |
PW_MCP_CONNECT | — | Default remote browser for the page tools (same as connect): a Playwright server ws(s)://… endpoint (npx playwright run-server, Browserless, a device cloud's Playwright endpoint) or cdp: + a Chrome DevTools URL. {{env:NAME}} tokens in it are filled from the environment, so keys stay out of chat. Local server only; the HTTP bridge refuses it |
PW_MCP_CONNECT_HOSTS | — | Comma separated hosts (grid.example.com, cloud.example.org:9443) that a connect URL chosen by the agent may send {{env:…}} values to. localhost and the host of PW_MCP_CONNECT are always allowed |
GITHUB_TOKEN / GITLAB_TOKEN | — | Only for load-report with a GitHub Actions run or GitLab job URL: read access to the run's artifacts (GH_TOKEN and CI_JOB_TOKEN work too). Sent only to github.com, gitlab.com and the hosts in PW_MCP_CI_HOSTS |
PW_MCP_CI_HOSTS | — | Your GitHub Enterprise or self-managed GitLab hosts (comma separated) that load-report may send GITHUB_TOKEN / GITLAB_TOKEN to. Run URLs on any other host are refused |
PW_MCP_PYTHON | project venv, then python3 | The Python that runs a pytest-playwright suite |
PW_MCP_BLOCK_RESOURCES | — | Default for the page tools' blockResources: comma separated image, media, font, stylesheet, trackers |
PW_MCP_BLOCK_WRITES | off | 1 makes the page tools abort POST, PUT, PATCH and DELETE requests that no mock answers (same as blockWrites: true), so steps run against a real environment cannot change its data |
PW_MCP_SHUFFLE_SEEDS | random | Comma-separated seeds for diagnose-flaky's order pass, to replay the orders a diagnosis reported |
PW_MCP_LOGIN_ENV | — | Extra environment variables save-login may type through {{env:NAME}}, comma separated. Without it only E2E_*, TEST_*, PW_*, PLAYWRIGHT_* and LOGIN_* are allowed |
PW_MCP_HISTORY_URL / PW_MCP_HISTORY_TOKEN | — | Optional: your team's history server (free, self-hosted) and a token from it. CI runs are uploaded with playwright-e2e-mcp upload (or the Action's history-url / history-token inputs) and analyze-history merges them with local runs. Unset (the default), nothing is ever sent anywhere. The older names PW_MCP_PRO_KEY / PW_MCP_PRO_URL still work |
PW_MCP_HISTORY | on | 0 stops recording runs to .playwright-e2e-mcp/history.jsonl |
PW_MCP_ALLOWED_ROOTS | — | Extra directories a caller may pass as projectRoot (:-separated, ; on Windows). Anything outside these and the default root is rejected. When the default root is your home folder or / (a client started the server without a working directory), only project folders are accepted: no hidden folders such as ~/.ssh, and a package.json, Playwright config or pytest config must be present |
PW_MCP_HTTP_TOKEN | — | HTTP bridge only: bearer token that unlocks all tools: 16+ characters, 32+ recommended (see Hosted endpoint) |
PW_MCP_ALLOWED_HOSTS | localhost + Vercel hostnames when there is no token | HTTP bridge only: comma-separated Host allowlist; * accepts any |
PW_MCP_MAX_FAILED_AUTH | 20 | HTTP bridge only: wrong tokens or access keys one client address may send in 15 minutes before it gets 429 |
PW_MCP_OAUTH_REDIRECT_HOSTS | any https host | HTTP bridge only: comma-separated hosts OAuth apps may return to, e.g. claude.ai,chatgpt.com; .example.com covers subdomains; localhost always works |
PW_MCP_OAUTH_CIMD | 1 | HTTP bridge only: accept OAuth clients that identify with a Client ID Metadata Document (an https client_id, the MCP default since 2025-11-25); 0 accepts only dynamically registered clients |
PW_MCP_TRUST_PROXY | off (on for Vercel) | HTTP bridge only, so the sign-in limit counts per client, not per proxy. 1 (or N for N proxies in a row) reads the address the nearest proxy appended to X-Forwarded-For, counted from the right, so a client cannot forge it. x-real-ip reads X-Real-IP instead, for a proxy that overwrites that header (nginx proxy_set_header X-Real-IP $remote_addr) and does not append to X-Forwarded-For |
PW_MCP_PASSTHROUGH_ENV | — | HTTP bridge only: comma-separated extra variables passed to test runs (e.g. BASE_URL) |
PW_MCP_MAX_CHILDREN | 4 | HTTP bridge only: how many test runs and browser probes may run at once |
PW_MCP_BLOCK_PRIVATE_URLS | off (on for the HTTP bridge) | 1 makes the URL tools refuse loopback, private-network and cloud-metadata addresses, including redirects and subresources |
PW_MCP_SERVERLESS_CHROMIUM | on for Vercel | Launch the page tools on the bundled serverless Chromium (@sparticuz/chromium, Linux x64, Node 22+); 0 turns it off, 1 turns it on elsewhere |
LOG_LEVEL / MCP_LOG_LEVEL | info | debug | info | warn | error | silent; LOG_LEVEL wins when both are set |
LOG_FORMAT / MCP_LOG_FORMAT | text | text, or json (also ndjson) for one structured JSON object per line, ready for a log ingester |
Logs always go to stderr; stdout is reserved for the MCP protocol. Unrecognized values
fall back to the default, so a typo in LOG_LEVEL logs at info and one in LOG_FORMAT
logs as text rather than silencing the server.
📊 Benchmark
bench/token-benchmark.mjs breaks a checkout button's test id on a
storefront page and fixes it two ways: with this server (run-test → suggest-fix → apply) and
with Playwright MCP plus a shell (playwright test, browser_navigate + browser_snapshot, edit,
re-run). Latest result (full output):
| Step | playwright-e2e-mcp (core tools) | playwright-e2e-mcp (all tools) | Playwright MCP + shell |
|---|---|---|---|
| Tool definitions the model reads (every request) | 2,266 | 11,480 | 4,558 |
| Run the failing test | 257 | 257 | 323 |
| Find the element / propose the fix | 232 | 232 | 2,286 |
| Apply + verify (re-run) | 230 | 230 | 34 |
| Total for one fix | 2,985 | 12,199 | 7,201 |
| Looking at the storefront page | Tokens |
|---|---|
inspect-page (default: locator map) | 571 |
Playwright MCP browser_navigate + browser_snapshot | 2,286 |
Tokens are characters ÷ 4 and count what the model reads (each tool's name, description and input
schema). Tool definitions are sent with every request, so with all 20 tools loaded they outweigh
the saving on the work itself: use --tools=core when you only fix failing tests, or
--tools=auto to start at 2,427 tokens and load more on request. The Playwright MCP route is a
lower bound: it assumes the agent picks the right locator from the snapshot on the first try,
which the server does for it here. Run 2026-11-01 with Playwright 1.64.1; re-run with
npm run build && node bench/token-benchmark.mjs.
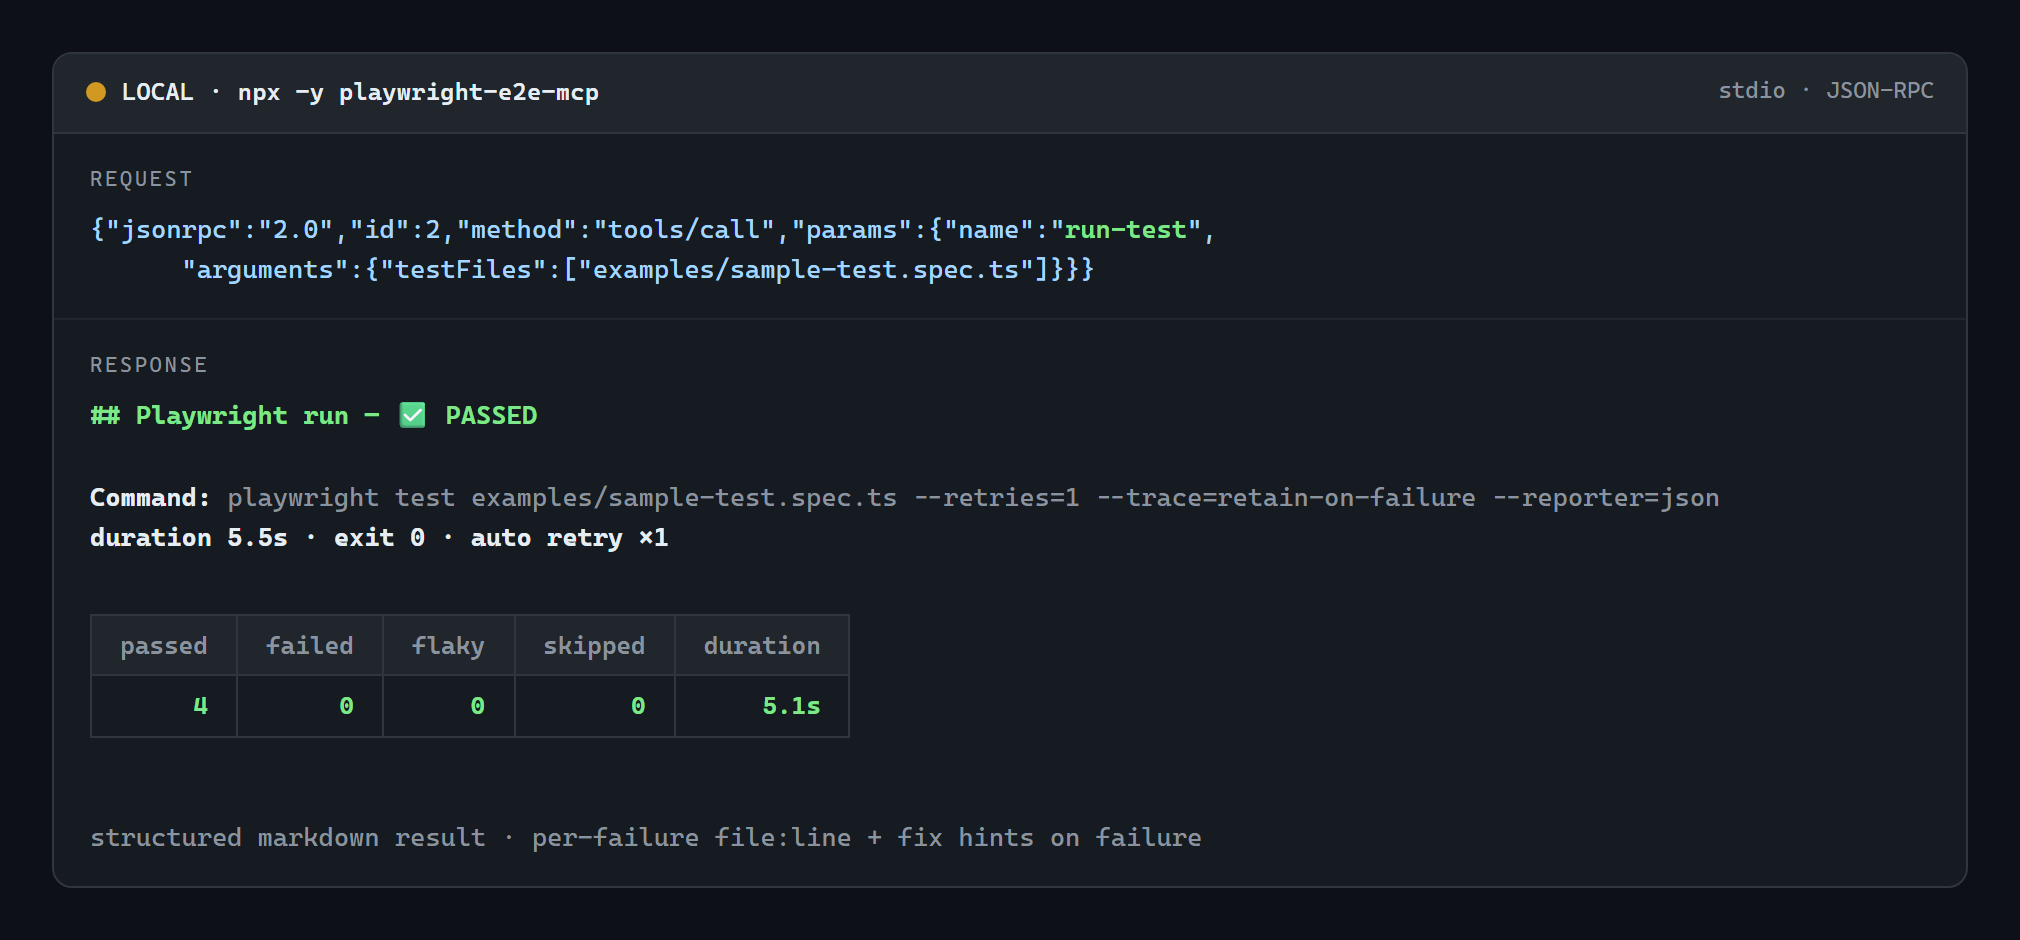
A real run-test result
A real run-test call served over stdio by npx -y playwright-e2e-mcp against the bundled
examples/sample-test.spec.ts (actual output, unedited):
🤝 Works alongside your browser MCP
Microsoft's Playwright MCP, Chrome DevTools MCP and similar servers are great for driving a page step by step. This server doesn't replace them or Playwright's own Test Agents in VS Code. Use a browser MCP to explore, and this one to run, diagnose and fix the suite, with fixes that are verified, a guard against fixes that cheat, flaky verdicts with evidence and the commit that broke a test.
💚 Free and open source
- MIT licensed. Use it, change it, ship it in commercial work. No paid tier, no feature held back, including the team history server, which you host yourself.
- No account, no API key, no sign-up.
npx -y playwright-e2e-mcp initis the whole setup. - No telemetry. It never phones home. Your tests, traces and run history stay on your machine
unless you point it at your own history server. The only other requests are
doctorasking npm for the latest version number when you run it (--offlineskips it),load-reportdownloading a CI run's artifacts when you give it a run URL, and a remote browser you name withconnect. - Free dependencies only: the MCP SDK (Apache-2.0), zod (MIT), axe-core (MPL-2.0) and playwright-core (Apache-2.0). Test runs use the Playwright your project already has.
🆕 Recent releases
- 0.15: pytest-playwright suites get
diagnose-flaky(with pytest-xdist forisolate),audit-tests(Python flake rules andexpect(...)rewrites) andgenerate-e2e-test(writes and verifiestest_*.py).-nruns no longer count each pytest result twice. - 0.14.1: security fix: behind a reverse proxy the sign-in limit can no longer be dodged
with a forged
X-Forwarded-For;{{env:…}}secrets in an agent-chosenconnectURL only go to hosts you named. CI templates for Azure DevOps, CircleCI, Bitbucket and AWS CodeBuild, andcheck-mocksreads JSON bodies written as strings (body='{"id": 1}'). - 0.14:
run-testchanged: true(only tests affected by your changes),suggest-fixverifyAllProjects(keep a fix only if every browser passes),maskfor dynamic regions incompare-visual-state,blockResourcesandofflinefor page tools, and a guard when the server starts in your home folder. - 0.13.1: security fix:
load-reportonly sendsGITHUB_TOKEN/GITLAB_TOKENto github.com, gitlab.com and hosts inPW_MCP_CI_HOSTS, never along a redirect. Page tools andsuggest-fixnow work in pytest projects installed from npm or Docker (the server shipsplaywright-core). - 0.13:
load-reporttakes a GitHub Actions or GitLab run URL, remote browsers and device clouds withconnect,suggest-fixpatches pytest files, guidance for testing AI chat and streaming UIs. - 0.12: hydration-race detection,
check-mocksfor mocks that drifted from the API, heal guard that checks at run time and reads pytest files. - 0.11: compact
inspect-page(571 tokens instead of 3,600),--tools=autoto load tools on request, smaller tool definitions. - 0.10: asks before changing your files, interactive test report in MCP Apps clients, Client ID Metadata Document sign-in for the hosted endpoint.
- 0.9: the team history server is free, self-hosted and in this repo.
- 0.8: pytest-playwright suites, popups and new tabs,
blockWrites, MCP 2026-07-28, update check indoctor. - 0.7: saved logins with 2FA, heal guard, flaky-test quarantine.
📚 More documentation
- Tool reference: every argument, example outputs, edge cases handled
- Hosted endpoint: the HTTP bridge for ChatGPT and claude.ai connectors
- History server: shared CI run history with a dashboard, self-hosted
- Architecture: how the server is built and the design decisions behind it
- Security: the security model and how to report a vulnerability
- Development: building, tests, Docker, signing and releasing
🙌 Contributing
Issues, ideas and pull requests are welcome. Start with a good first issue, read CONTRIBUTING.md and the code of conduct.
License
MIT. If this saves you a debugging session, a ⭐ on the repo helps other Playwright users find it.