since-cutoff
Tells your coding agent what changed in a Python library's public API since its training cutoff. Tools: api_changes (one package, by model or cutoff date) and project_changes (every dependency in a project's lockfile). Static diff, local stdio, no API key.
Documentation

since-cutoff
For Python projects written with a coding agent: since-cutoff finds the dependency APIs that changed after the model's training cutoff, measures which of them the model gets wrong, and fixes those with short AGENTS.md notes, each checked by a type checker or taken directly from the API diff.


English | 简体中文 | Español | Français
The problem
Every model has a training cutoff; your lockfile keeps moving. When a library changes its public API after the cutoff, a model that learned the old version keeps writing the old calls. Some of that code fails at import or call time. Some still runs, because the old path is only deprecated.
A few of the changes since-cutoff scan finds for Claude Sonnet 4.5 (training cutoff July
2025) in the sample project,
which pins six of its nine dependencies to current releases (for the other three, which are
unpinned, the tool uses the latest release):
| library | release at the cutoff | pinned | what changed |
|---|---|---|---|
| anthropic | 0.60.0 | 1.8.0 | messages.create(temperature=..., top_p=..., top_k=...) is no longer accepted |
| huggingface-hub | 0.34.3 | 2.0.0 | hf_hub_download(resume_download=..., force_filename=..., local_dir_use_symlinks=...) left the signature in 1.0 (2.0.0 still accepts them at run time, ignores them and warns) |
| langchain-core | 0.3.72 | 1.6.5 | retriever.get_relevant_documents() and llm.predict() removed |
| openai | 1.98.0 | 3.19.2 | 21 breaking changes, 6 new deprecations |
In that project, 7 of 9 dependencies changed their public API after the cutoff. The static diff flags 317 breaking changes and 23 new deprecations; some are internals, which the probes skip.
It is not one model or one vendor. Across 36 widely used Python AI libraries and 21 models from OpenAI, Anthropic, Google, xAI, DeepSeek, Qwen, Moonshot and Mistral, even the newest model tested (Claude Opus 5.5, June 2026 cutoff) predates a public API break in 20 of the 36 (full results):

since-cutoff does three things about it:
scanfinds, for each dependency, the newest release on or before the model's cutoff and diffs its public API against the version you pin. No model calls, no API key.runasks the model short coding tasks that need the changed APIs, with no tools and no docs, and scores each answer with a type checker against both versions: stale, wrong, deprecated or correct. No LLM judges anything.- Notes: for each failure it writes a one-line AGENTS.md / CLAUDE.md note. It keeps a model-written note only if its example type-checks against your version; otherwise it uses a plain statement of the change from the API diff. Then it re-tests the model on held-out tasks with and without the notes.
The same diff is available to agents through an MCP server and to CI through a GitHub Action and a pre-commit hook.
Quick start
# list API changes since your model's cutoff (no model calls, no API key)
uvx since-cutoff scan

# probe the model, write notes, and add them to AGENTS.md
uvx since-cutoff run --apply
Or install it with pipx install since-cutoff (or pip install since-cutoff) and run
since-cutoff. Run it from your project root: it reads uv.lock, poetry.lock, pdm.lock,
pylock.toml, Pipfile.lock, requirements*.txt, pyproject.toml, Pipfile or a .venv
(not setup.py or setup.cfg). Without --model it tests the model your coding agent is set
up with, from the Claude Code, Codex, OpenCode or Aider settings; for any other model, pass
--model (see Choosing the model).
scan is free; run sends prompts to the model provider and uses your API credits or Claude
Code usage.
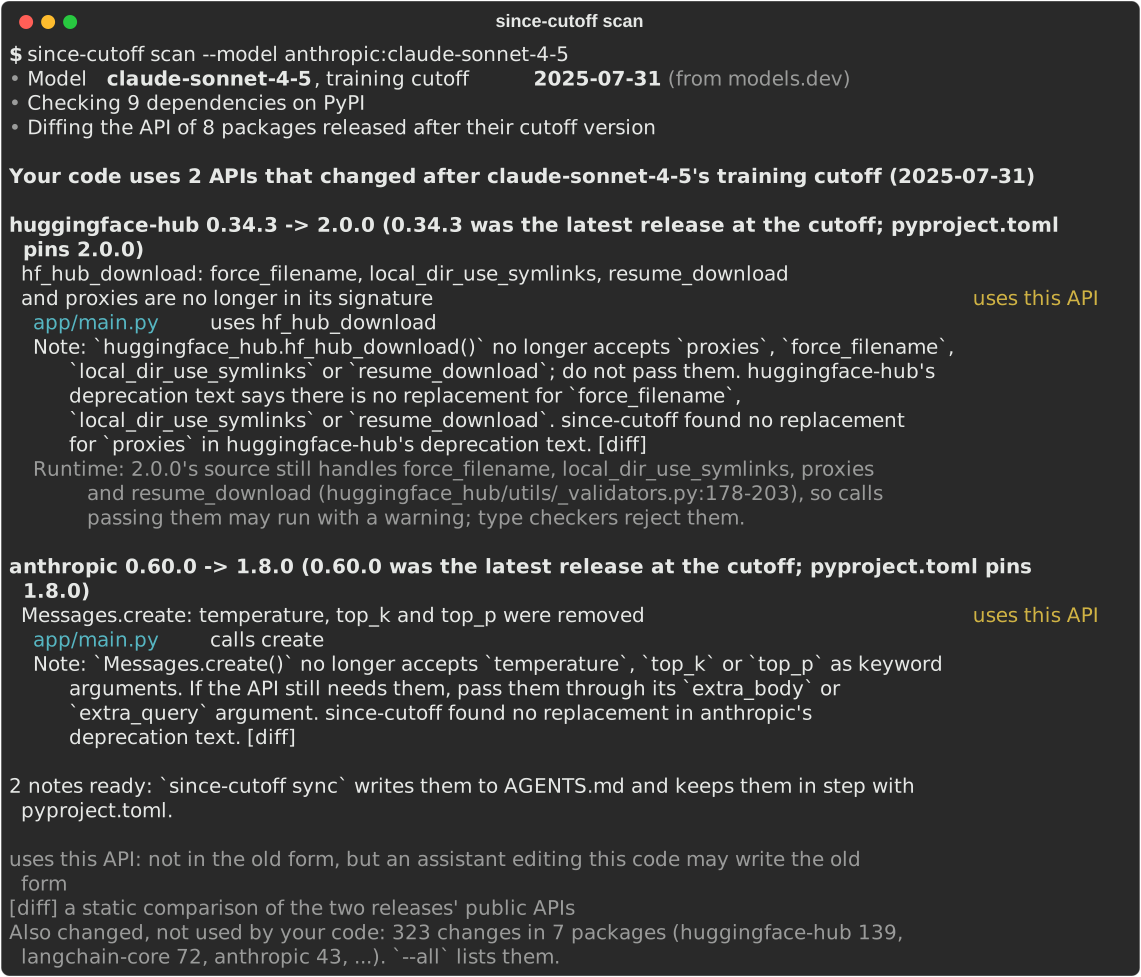
What scan prints for the sample project:
In Claude Code
/plugin marketplace add MohammadHijjawi97/since-cutoff
/plugin install since-cutoff@since-cutoff
Then ask Claude to "check which of our dependencies you are out of date on", or run
/since-cutoff:since-cutoff. The skill runs the CLI; the measuring itself is done by a fresh,
tool-less copy of the model, so the agent cannot grade itself. The plugin also starts the
MCP server, so
Claude can look up a library's changes before it writes code.
In other coding agents
npx skills add MohammadHijjawi97/since-cutoff
This installs the same skill through the open skills
CLI for Codex, Cursor, Gemini CLI, GitHub Copilot, OpenCode and other agents that read
SKILL.md. since-cutoff reads the model from the Codex, OpenCode and Aider settings too; for
other agents, tell it which model to test, for example since-cutoff scan --model openai:gpt-5.4.
Add the MCP server as shown below.
Prompts that work well:
- "Which of our dependencies changed their public API after your training cutoff?" The agent
runs
since-cutoff scanor calls the MCP toolproject_changes. - "Measure which of those changes you actually get wrong, and add the notes to AGENTS.md." The
agent asks you first, then runs
since-cutoff run --quick --apply. - "Before you write the httpx code, check what changed in httpx since your cutoff." The agent
calls the MCP tool
api_changes.
Choosing the model
--model | uses | needs |
|---|---|---|
claude-code (default when no setting names a model) | your Claude Code login (subscription or key), current model | the claude CLI |
claude-code:sonnet, claude-code:claude-haiku-4-5 | a specific Claude model | the claude CLI |
anthropic:<model> | Anthropic API | ANTHROPIC_API_KEY |
openai:<model> | OpenAI API | OPENAI_API_KEY |
openrouter:<vendor/model> | OpenRouter | OPENROUTER_API_KEY |
deepseek:<model> | DeepSeek API | DEEPSEEK_API_KEY |
ollama:<model> | local Ollama | Ollama running |
openai-compatible:<model> | any OpenAI-compatible server | --base-url, optional OPENAI_API_KEY |
Without --model, since-cutoff 0.3.0 and later test the model your coding agent is set up with, and
the model line says where it came from ("model from .claude/settings.json"):
SINCE_CUTOFF_MODEL(a full spec such asopenai:gpt-5.4) always wins.- Inside Claude Code (which sets
CLAUDECODE=1for the commands it runs), only Claude Code's settings count:ANTHROPIC_MODEL, then the project's.claude/settings.local.jsonand.claude/settings.json, then~/.claude/settings.json. - Elsewhere the most specific setting wins: first
ANTHROPIC_MODELorAIDER_MODEL, then the project settings, nearest folder first, from the scanned folder up to the repository root (never the home folder), then the user settings. In one folder the agents count in this order:
| agent | project settings | user settings |
|---|---|---|
| Claude Code | .claude/settings.local.json, .claude/settings.json | ~/.claude/settings.json |
| Codex | .codex/config.toml, with its selected profile | $CODEX_HOME/config.toml or ~/.codex/config.toml |
| OpenCode | opencode.json, opencode.jsonc | ~/.config/opencode/ |
| Aider | .aider.conf.yml, with Aider's aliases (4o, flash, r1, ...) | ~/.aider.conf.yml |
When no setting names a model, it tests Claude Code's default model and says so. Only the model
fields are read, and a model name it cannot place stops the run with a message naming the
setting. A model that an agent reaches through another service (GitHub Copilot, Amazon Bedrock,
Vertex AI) is named after its maker, so run calls the maker's API (openai: needs
OPENAI_API_KEY).
Training cutoffs come from models.dev (a snapshot is bundled for offline
use). since-cutoff models sonnet lists them; --cutoff 2025-07 overrides the date, and
since-cutoff scan --cutoff 2025-07 without --model scans against that date alone. scan
needs only the cutoff, so it also takes a model id without a provider (claude-haiku-4-5,
sonnet) or with any provider models.dev lists (google:gemini-2.5-pro, Amazon Bedrock and
Vertex AI ids included); run needs a provider from the table above.
Results
Two Claude models on the 9-dependency sample project in
examples/agent-app,
measured with since-cutoff 0.1.0, with Claude Opus 4.6 writing the tasks and notes:
| Claude Haiku 4.5 | Claude Opus 4.6 | |
|---|---|---|
| training cutoff | Feb 2025 | May 2025 |
| API changes probed | 20 | 16 |
| stale / wrong / deprecated / correct | 5 / 1 / 2 / 12 | 7 / 0 / 3 / 6 |
| libraries with stale use | 3 of 5 probed | 2 of 4 probed |
| notes written (with an example that type-checks) | 8 (7), about 391 tokens | 10 (7), about 437 tokens |
| held-out correct, without -> with notes | 14% -> 57% (14 pairs) | 5% -> 65% (20 pairs) |
| previously-correct APIs after notes | 6/6 still correct | 6/6 still correct |
Held-out tasks are paraphrases of the task each failing change was probed with; each one is answered twice, without and with the notes, and scored the same way. The last row re-checks APIs the model already got right, to catch notes that make things worse.
In this sample the stronger model was not safer: Opus 4.6 wrote APIs that were removed after its
cutoff, including anthropic.HUMAN_PROMPT with client.completions. Stale code from both runs,
each valid for the comparison release and rejected by the type checker for the pinned one:
messages.create(temperature=...) (anthropic 1.8), hf_hub_download(resume_download=...),
local_dir_use_symlinks=..., force_filename=... and proxies=... (huggingface-hub 2.0), and
client.beta.vector_stores (openai 3.x). At run time, anthropic 1.8.0 raises TypeError for
temperature; huggingface-hub 2.0.0 still accepts those four download arguments, ignores them
and warns.
The notes written in the Claude Haiku 4.5 run (excerpt, verbatim):
<!-- since-cutoff:start -->
## Library changes after the model's training cutoff

**anthropic 1.8.0**
- `temperature=...` was removed from `messages.create()` in anthropic 1.8.0. Omit the `temperature` parameter entirely; there is no replacement.

**huggingface-hub 2.0.0**
- `hf_hub_download(..., resume_download=True)`: The `resume_download` parameter was removed in huggingface-hub 2.0.0. Omit it; downloads resume automatically.

**openai 3.19.2**
- `client.beta.vector_stores` is removed in openai 3.19.2. Use `client.vector_stores` instead.
<!-- since-cutoff:end -->
The huggingface-hub note is not quite right: resume_download left the signature in 1.0, not
2.0.0, and 2.0.0 still accepts it at run time, ignores it and warns
(source).
Omitting it is still the right advice.
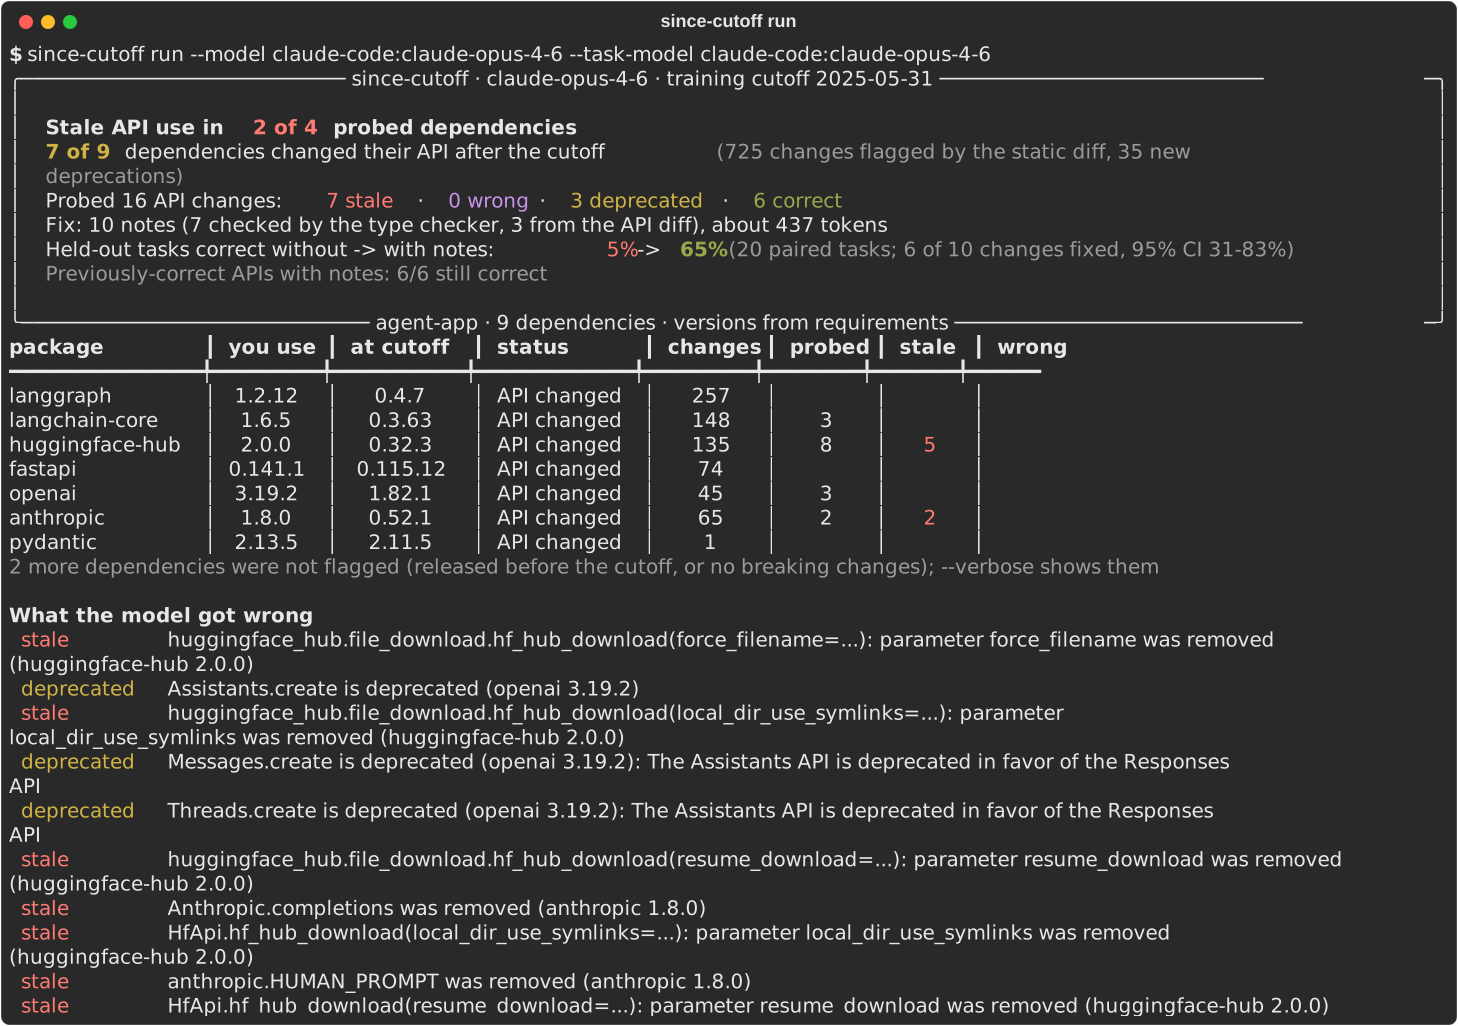
The terminal summary of the Claude Opus 4.6 run, recorded with 0.1.0. The probe results are the
ones in the table above. The diff counts on the card are 0.1.0's ("725 changes flagged"); after
fixes to the diff, scan in 0.2.0 reports 513 breaking changes and 48 new deprecations for the
same cutoff. The card's "changes fixed" count and its 95% CI also follow 0.1.0: the interval
belongs to that count, not to the 5% -> 65% rates, and versions up to 0.2.0 counted a change as
fixed even when a held-out answer was already correct without the notes.
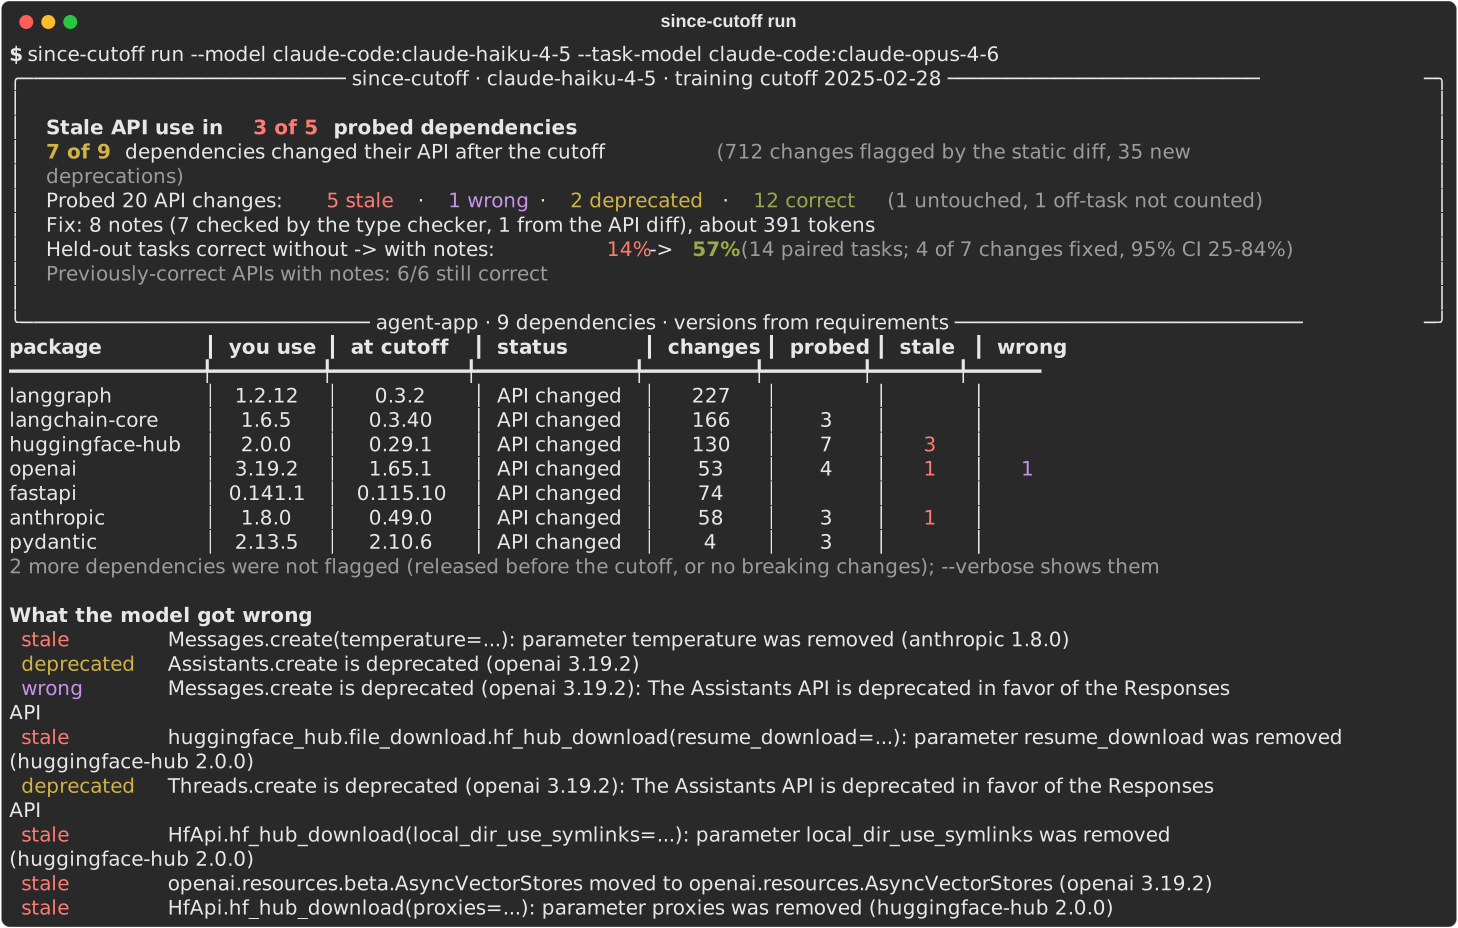
The same summary for the Claude Haiku 4.5 run (also 0.1.0; scan in 0.2.0 reports 491 breaking changes and 50 new deprecations for its cutoff)
Small samples, two models, one project: treat this as a demonstration of the method, not a
benchmark. Every run writes its full report (each task, answer and type-checker error) to
.since-cutoff/report.md. To repeat the experiment with the current version (its diff and
ranking changed, so the probes will not be identical):
cd examples/agent-app && since-cutoff run --model claude-code:claude-haiku-4-5 --task-model claude-code:claude-opus-4-6.
Since 0.3.0, a run can also save its tasks: add --tasks-out tasks.json, and anyone
can repeat the run on exactly the same tasks with --tasks-from tasks.json, for another model or
another set of notes. The file names who wrote the tasks (model, prompt version, since-cutoff
version), and a run on reused tasks reports it
(details).
Results from your own projects are very welcome in
Share your results.
How the measurement works and what these numbers do and do not show, in more detail: the write-up.
Use it from any agent (MCP)
since-cutoff mcp is an MCP server that lets a coding agent ask "what changed in this library
since my training cutoff?" before it writes code. It has three read-only tools:
| tool | answers |
|---|---|
api_changes(package, model, symbol=...) | what changed in one library between the release at the model's cutoff and the latest (or a given) version, hard breaks first |
project_changes(project_dir, model) | the same for every dependency of a project at its pinned version, starting with APIs your code already uses |
model_cutoff(model) | a model's training cutoff, from models.dev |
The agent passes its own model id, so the answer covers what changed after that model's training cutoff. The tools read PyPI and package sources statically: no model calls, no API key, no package code executed.
Claude Code
claude mcp add --scope user since-cutoff -- uvx since-cutoff@latest mcp
Codex (~/.codex/config.toml)
[mcp_servers.since-cutoff]
command = "uvx"
args = ["since-cutoff@latest", "mcp"]
startup_timeout_sec = 60
tool_timeout_sec = 900
Cursor (~/.cursor/mcp.json) and Claude Desktop (claude_desktop_config.json)
{
  "mcpServers": {
    "since-cutoff": { "command": "uvx", "args": ["since-cutoff@latest", "mcp"] }
  }
}
VS Code (.vscode/mcp.json)
{
  "servers": {
    "since-cutoff": { "type": "stdio", "command": "uvx", "args": ["since-cutoff@latest", "mcp"] }
  }
}
Gemini CLI
gemini mcp add --scope user since-cutoff uvx since-cutoff@latest mcp
# or as an extension, which starts the same server:
gemini extensions install https://github.com/MohammadHijjawi97/since-cutoff
@latest makes uvx pick up new releases instead of reusing the first version it cached (the
plugin's own .mcp.json pins the exact release). If the client cannot find uvx, install
uv or give the full path (which uvx). The server is listed in the
MCP Registry as io.github.MohammadHijjawi97/since-cutoff.
The first project_changes call on a larger project downloads the wheels of every dependency
that changed and can take several minutes (very large packages such as transformers take the
longest). Results are cached, so later calls take seconds. To warm the cache, run
since-cutoff scan in the project once; it shares the cache with the server. Clients with a
short default tool timeout may need a longer one, as in the Codex example above.
project_changes keeps its answer under about 24,000 characters: changed dependencies that do
not fit get one line each, and passing them in only lists their changes.
What api_changes("huggingface-hub", model="claude-haiku-4-5") returned in 0.2.0 (real output,
trimmed; later versions refine the diff, so their counts differ slightly):
# huggingface-hub 0.29.1 -> 2.0.0

- From 0.29.1 (2025-02-20): the newest release on or before 2025-02-28 (training cutoff of claude-haiku-4-5, from models.dev)
- To 2.0.0 (2026-09-24): the latest release on PyPI
- 116 breaking changes, 0 new deprecations (removed or moved 62, parameters removed 43, parameters now required 9, changed kind 1, now keyword-only or positional-only 1)

## Removed or moved

- `huggingface_hub.InferenceApi` was removed; similar names now: `inference`, `InferenceEndpoint`, `InferenceClient`
...

## Parameters removed

- `huggingface_hub.snapshot_download(resume_download=...)`: parameter `resume_download` was removed; similar parameters now: `force_download`
- `huggingface_hub.file_download.hf_hub_download(force_filename=...)`: parameter `force_filename` was removed; similar parameters now: `filename`
...

Not listed: 76 breaking changes, 0 new deprecations (removed or moved 47, parameters removed 29). Narrow with symbol="..." or raise limit.
With symbol="hf_hub_download" it lists only the 8 changes to that function (resume_download=,
force_filename=, local_dir_use_symlinks= and proxies=, on the function and on HfApi).
symbol also takes a call the way code writes it: client.messages.create finds the changes
to Messages.create. The diff reads signatures only: these four parameters left the signature in
huggingface-hub 1.0, but 2.0.0 still accepts them at run time, ignores them and warns.
Use in CI
GitHub Action
Scans the project on each pull request and adds a summary to the job page: per dependency, the
version at the model's cutoff, the version you pin and the top changes, with changes to names
your code uses first. Like scan, it only reads PyPI and models.dev: no model calls, no API key.
# .github/workflows/since-cutoff.yml
name: since-cutoff
on:
  pull_request:
    paths: ["**/*.lock", "**/pylock*.toml", "**/requirements*.txt", "**/pyproject.toml"]
jobs:
  scan:
    runs-on: ubuntu-latest
    steps:
      - uses: actions/checkout@v7
      - uses: MohammadHijjawi97/since-cutoff@v0
        with:
          model: anthropic:claude-sonnet-4-5  # the model your team codes with
| input | default | |
|---|---|---|
model | required | provider:model as for --model; only its training cutoff is used |
working-directory | . | the project directory |
only, exclude | comma-separated PyPI names | |
cutoff | override the training cutoff (YYYY-MM or YYYY-MM-DD) | |
fail-on-changes | false | fail the step when a dependency changed its API after the cutoff |
step-summary | true | add the Markdown summary to the job summary |
cache | true | keep PyPI metadata, package sources and API diffs between runs (also when fail-on-changes fails the job) |
args | more since-cutoff scan arguments, e.g. --all-deps --limit 20 | |
since-cutoff-version | 0.3.2 | the since-cutoff release to run, or latest |
Outputs: changed-packages (comma-separated), changes (breaking changes), deprecations,
markdown (the summary's path, for example to post it as a pull request comment) and report
(the full report's path). A change reachable under several import paths is counted once.
pre-commit
# .pre-commit-config.yaml
repos:
  - repo: https://github.com/MohammadHijjawi97/since-cutoff
    rev: v0.3.2
    hooks:
      - id: since-cutoff-scan
        args: [--model=anthropic:claude-sonnet-4-5]  # add --fail-on-changes to block the commit
The hook runs when a lockfile, a requirements file or pyproject.toml changes, and prints the
scan. Give it --model in args. It needs PyPI, so skip it on pre-commit.ci
(ci: {skip: [since-cutoff-scan]}).
Other CI
# Markdown summary for any CI; exit code 3 if a dependency changed its API after the cutoff
since-cutoff scan --model anthropic:claude-sonnet-4-5 --markdown summary.md --fail-on-changes

# measure the model as well (needs its API key, or the claude CLI)
since-cutoff run --quick --fail-on-stale --json > since-cutoff.json
--markdown - prints the summary to stdout, and only the progress and the report's path to
stderr, as --json does. In a file, a pipe or a CI log there is no live progress bar, and the
output is laid out 160 columns wide (COLUMNS sets another width). Exit codes: 0 ok, 1
error (for example, run could not probe any API change or score any model answer), 2 usage
error, 3 stale API use found with run --fail-on-stale, or API changes found with
scan --fail-on-changes, 141 the output was closed early (piped into head, for example).
How it works
Three stages. The first needs no model; in the other two, a type checker scores every answer and checks every note the model writes:

| outcome | meaning |
|---|---|
| stale | the code is valid for the comparison release (the one at the model's cutoff) and invalid for yours, and the error involves an API that changed |
| wrong | invalid for your version, but not explained by a change (hallucinated or misused API) |
| deprecated | valid, but uses an API marked @deprecated in your version |
| correct | valid for your version and actually uses the changed API |
| untouched / off-task / invalid / error | not counted in any rate, and always reported |
Since 0.3.0, the held-out result gives the task-level rates without -> with notes (with the number of paired tasks and API changes behind them), their difference with a 95% bootstrap interval that resamples API changes, the changes the notes fixed (wrong without, correct with) with a Wilson 95% interval, the changes they broke, an exact sign test of fixed against broken, and the held-out pairs not counted, by reason. The regression check reports how many previously-correct APIs are still correct with the notes.
run --compare template,signatures (0.3.0 and later) also answers the held-out tasks and
regression checks with baseline notes that need no model: template states each failing change in
one sentence from the API diff, and signatures gives the new signature and first docstring
paragraph of each changed API, or of the replacement its library names. All blocks are scored on
the same pairs, against the same answers without notes, and each block's size is shown in tokens,
so a run shows what since-cutoff's own notes add over them.
Everything is scored by a type checker against the exact package versions, each in an isolated
environment with that package's own runtime dependencies. No LLM judges anything, and every
number traces back to results.json. Details: docs/how-it-works.md.
What it runs, sends and stores
- Runs no package code and no model-written code. Packages are read statically (griffe with
inspection off; only
.py/.pyifiles are extracted, with path and size checks). The model's answers are only type-checked, locally, with basedpyright. - Fetches public package metadata and wheels from PyPI, and model cutoffs from models.dev (a snapshot is bundled for offline use). Git, path, workspace and private-index dependencies are never looked up on public PyPI by name.
- Sends prompts only in
run, and only to the model provider you choose: package names, versions, public signatures and docstrings of the changed APIs, the generated tasks and, for notes, the model's own answers. Never your source code.scan, the MCP server, the GitHub Action and the pre-commit hook send nothing to any model. - Stores results in
.since-cutoff/in your project (it ignores itself in git) and a local cache (since-cutoff cache pathshows it,since-cutoff cache clearremoves it). With--applyit writes one marked block intoAGENTS.md/CLAUDE.mdand leaves the rest of the file byte-for-byte unchanged;since-cutoff unapplyremoves the block. - No telemetry, no account, no personal data. Re-runs come from the cache, so they are free
and reproducible (
--freshasks the model again). See PRIVACY.md.
Limitations
- Python only for now. TypeScript (
.d.tsdiffs,tsc) is next (#1). - A type checker sees wrong names, wrong parameters and PEP 702 deprecations. It cannot see
behaviour changes behind an unchanged signature, or deprecations that only warn at run time.
scanalso lists deprecations declared with a library's own decorator (name containing "deprecat") and removed names that a module still serves with a warning through__getattr__, butrundoes not probe them. - The diff covers the public API:
_privatenames, and test suites, benchmarks and examples shipped inside a package, are skipped. - Probes cover a ranked sample of the breaking changes (symbols your code already uses first), not all of them.
- "The comparison release" is the newest release on or before the cutoff date. Models know recent releases less well, so real staleness can start earlier.
- Held-out tasks are paraphrases of the same change: they show that a note fixes that change, not that the model got better in general.
What the training cutoff is used for
The cutoff date picks a comparison point. It is not a claim about what a model memorised.
since-cutoff takes the date from models.dev (or --cutoff); a month means its last day
(2025-07 is 31 July 2025). For each dependency it takes the newest final, non-yanked release
uploaded on or before that date (a pre-release only if the package had no final release by then,
never a development release), and diffs that release's public API against your locked version.
That diff is a list of candidates: API changes that the model's training data probably does not
include.
The date decides three things:
- which packages are diffed at all: a package whose locked version is no newer than that release has nothing to diff, and a package first released after the date is listed as new;
- in
run, which versions of that release's own dependencies the old side is type-checked with (the newest each requirement allowed on that date); - the "old" side of every probe in
run, so an answer that is valid there and invalid for your version, with the error on a changed API, is "stale" rather than "wrong".
A model can know a release after its stated cutoff or not know releases shortly before it, so the
scan can list changes the model already handles and miss some it does not. Whether the model
actually writes the old API is shown only by run, which asks it: with no tools, told which
version the project pins.
How it compares
since-cutoff answers one question for one project: which public APIs of the versions you pin
changed since the release a model's training cutoff points to, starting with the ones your code
uses? since-cutoff run adds two optional questions: does this model actually get them wrong,
and does a short note fix it? Most tools below answer a different question ("what do the
library's docs say now?") and work well alongside it.
| tool | what it does | how since-cutoff relates |
|---|---|---|
Context7 (MCP server and ctx7 CLI) | The agent calls resolve-library-id and query-docs to pull documentation snippets into its context while it works. It serves a specific version (/org/project/version) when the library's owners have added that version (git tags or branches, at most 20); otherwise it serves the indexed branch. Works without an API key at a lower, anonymous rate limit. | Complementary. Context7 supplies documentation; it does not read your locked versions or check the code the agent writes. since-cutoff lists which of your pinned APIs changed after the model's cutoff, the ones your code uses first, so you know where a lookup or a note is needed. When you ask Context7, name the version you pin. |
| Other docs servers: Ref, docs-mcp-server | Documentation search for agents, at answer time; docs-mcp-server can index docs locally | Same as Context7. |
| library-skills | Libraries such as FastAPI and Streamlit ship agent skills inside their packages; uvx library-skills links the skills of the versions you have installed into .agents/skills or .claude/skills, so they update with the library | Written by the maintainers and in step with your installed version: when a library ships one, use it. since-cutoff covers packages that ship no guidance, and only states changes to the API surface. |
| Vendor skill plugins, e.g. pydantic/skills | Claude Code, Codex and Cursor plugins and SKILL.md files for Pydantic, Pydantic AI and Logfire, installed from the repository | Maintainer guidance on how to use a library well; released with the plugin repository, not with the version you pin. since-cutoff's notes are written for your lockfile. |
Codemods: ast-grep rules, OpenAI's openai migrate (Grit) | Rewrite code that already exists with hand-written syntactic rules; ast-grep's catalog has an OpenAI SDK migration (openai.Completion.create(...) to client.completions.create(...)) | For migrating code you already have, a codemod is the right tool. since-cutoff is about the code an assistant writes next: it finds the changes from the API diff instead of from rules someone wrote, and only suggests; it rewrites nothing. |
| Dependency bots: Renovate, Dependabot | Open pull requests that update your pinned versions | The GitHub Action can run on those pull requests and list the changed APIs, the ones your code uses first. |
| Benchmarks: GitChameleon 2.0, VersiCode, CodeUpdateArena, LibEvolutionEval | Measure models on fixed task sets built from real version changes, or synthetic ones (CodeUpdateArena); GitChameleon 2.0 runs unit tests | They compare models in general, and some check behaviour by running tests. since-cutoff looks at one project's pinned versions, statically: a type checker sees names, parameters and deprecations, not behaviour. |
--compare signatures in since-cutoff run gives the model the new version's signature and the
first paragraph of its docstring. It is a local stand-in for a documentation lookup, not Context7.
Two smaller tools work on the same problem: cutoff
probes a library you maintain by running model-written programs against its current version, and
postcut turns a Ruby Gemfile.lock into a brief of changes
since the cutoff. since-cutoff is built on griffe,
basedpyright, models.dev and rich.
Using since-cutoff with Context7
since-cutoff scan tells you which APIs to look up; Context7 can supply the docs. Name the
version you pin when you ask ("anthropic 1.8.0"). Context7 matches it only when the library's
owners added that version:
on 2026-09-27, /openai/openai-python offered v1.68.0, v1_105_0, v2.8.1 and v2.11.0, and
/anthropics/anthropic-sdk-python offered none, so you may get the default branch's docs.
Related research
- Deprecated APIs in code completion. Wang et al., LLMs Meet Library Evolution: Evaluating
Deprecated API Usage in LLM-based Code Completion (ICSE 2025;
arXiv:2406.09834, first titled How and Why LLMs Use
Deprecated APIs in Code Completion? An Empirical Study). 7 models, 145 mappings from a
deprecated API to its replacement in 8 Python libraries, 28,125 completion prompts. Most
completions used neither API. Of those that used one of the two (the paper's "plausible"
completions), 25-38% used the deprecated one over the whole dataset: 70-90% when the prompt came
from code that used the deprecated API, 9-18% when it came from up-to-date code. Two baseline
fixes were tested on up-to-date prompts where a model had used the deprecated API. ReplaceAPI
swaps the deprecated API's tokens for the replacement during decoding and lets the model finish
the line: the replacement was then used in 85.2-99.6% of cases on the six open models (it needs
control of decoding, so not GPT-3.5). InsertPrompt adds the comment
# {dep} is deprecated, use {rep} instead and revise the return value and arguments.and regenerates: 25.7-97.2%, depending on the model, which the authors judge not yet effective or accurate enough. since-cutoff's notes are close to InsertPrompt, moved into the project's instructions file;since-cutoff runmeasures them on held-out tasks instead of assuming they work. - Documentation in context is not enough on its own. Ashik et al., When LLMs Lag Behind:
Knowledge Conflicts from Evolving APIs in Code Generation
(arXiv:2604.09515, 2026 preprint). 270 real API updates (45
deprecated or removed, 128 modified, 97 new) from releases of 8 Python libraries after December
2023, and 11 models from 4 families with training cutoffs before that date. Given only a
description of the update, the models at least partly adopted it in 74.64% of answers (judged
by GPT-5 mini), and 42.55% of those answers ran in the library version that introduced the
update; with the API documentation as well, 92.87% adopted it and 66.36% ran. Adding
chain-of-thought and self-reflection prompts raised the executable rate by a further 11.33%, a
relative gain rather than percentage points. Of the answers that did not adopt the update, 42.1%
ignored it entirely and 16.4% used the old API; of the adopting answers that still failed to run
in the best setup, the most common update-related cause was wrong parameters (26.6% of those
failures). This is why since-cutoff checks code against your exact version, and why
since-cutoff runre-tests the model with the notes rather than assuming they are followed. - Benchmarks. GitChameleon 2.0: 328 Python completion problems, each tied to specific library versions and checked by executable unit tests; enterprise models reach 48-51% at baseline, retrieved documentation adds up to about 10 points (GPT-4.1: 48.5% to 58.5%) and self-debugging about 10-20. VersiCode: version-specific code completion and version-aware code migration over more than 300 Python libraries and more than 2,000 versions across 9 years. CodeUpdateArena: knowledge editing for 54 functions from 7 Python packages, with synthetic, GPT-4-generated updates and 670 program-synthesis examples; prepending the update's documentation did not let open models (DeepSeek, CodeLlama) use it. LibEvolutionEval (NAACL 2025): version-specific inline completion across 8 libraries; retrieved version-specific documentation and prompting help.
These studies measure many models on fixed task sets; GitChameleon 2.0 and Ashik et al. run the
generated code. since-cutoff does something narrower: for one project it lists the changes since a
comparison release, the ones your code uses first, and run checks one model's answers
statically. It cannot see behaviour changes behind an unchanged signature, which tests that run
the code can.
Contributing
since-cutoff is young. The most useful help right now:
- Run it on your project and post what it found, including false positives, in Share your results.
- Pick up a good first issue: small, self-contained tasks such as another lockfile format or a provider preset.
- Bigger pieces are labelled help wanted, for example TypeScript support.
- Report a bug or an odd result in the issues.
CONTRIBUTING.md explains the code layout and the checks; the offline test suite runs the whole pipeline with a toy library and a scripted model, so no API key is needed. Security issues: SECURITY.md.
Citation
If you use since-cutoff in research, please cite it (see CITATION.cff).
License
MIT © Mohammad Hijjawi