Inferrail
Local, payload-free AI cost visibility for agents. Track spend by model, route, customer, or tagged work without storing prompt or response bodies.
Documentation
Know what your AI work costs.
Without keeping what it said.
Inferrail is a gateway you run yourself that tracks token usage and estimated LLM cost by customer, workflow, or task for its supported OpenAI and Anthropic endpoints.



Try locally · How it works · Privacy · Integrations · MCP · Status · Docs
Open source under Apache-2.0. Developer preview: the features below are implemented and tested, but CLI flags, config shape, and receipt fields may still change before 1.0.
Privacy boundary
For each supported request, the gateway writes one receipt to a local file. This is a real receipt from the offline demo below.
Example receipt: synthetic demo data, abbreviated.
{
  "receipt_id": "ir_4090e812f2ba4d3680e7",
  "route": "default",
  "provider": "demo",
  "model": "demo-small",
  "status": "success",
  "prompt_tokens": 812,
  "completion_tokens": 143,
  "pricing": {
    "input_usd_per_million": "0.20",
    "output_usd_per_million": "0.80",
    "source": "DEMO — a made-up round number, not a real provider price",
    "verified_date": "2026-09-26"
  },
  "estimated_cost_usd": "0.000277",
  "attributes": {"customer": "acme", "workflow": "contract-review", "work_id": "work-contract-1"}
}
Omitted here: request_id, timestamp, total_latency_ms, retry_count.
Full field list: receipts/schema.py.
What happens to your key and your content (self-hosted):
- Your gateway process reads the provider key from its own environment and sends requests to the provider you configure.
- It processes prompts and responses in memory to forward them. The provider still receives your request content, under its own policies.
- Receipts record usage, cost evidence, status, timing, and the attribution you supply. The receipt path does not copy message bodies.
- Attribution tags are stored exactly as sent. Use identifiers, and keep secrets and message content out of them.
- Local telemetry events are operational metadata. The optional usage beacon is separate and sends nothing unless you configure a collector endpoint (details).
- The hosted trial is a different boundary: if you add a real key there, the hosted process holds that key and handles your traffic.
Check it yourself: request handlers · execution engines (OpenAI, Anthropic) · provider adapters (OpenAI, Anthropic) · receipt builder · sinks (JSONL, SQLite) · canary tests (OpenAI, streaming and telemetry, Anthropic).
inferrail verify-payload-free prints the live receipt schema and checks
that no field is named for message content. It is a schema check, not a
security audit: it cannot inspect stored values, logs, or your provider.
Try it offline
Requires Python 3.11+. Installing downloads the package and its dependencies; after that, the demo runs offline.
python -m pip install inferrail
inferrail demo
inferrail report --by customer --receipts ./inferrail-demo-receipts.jsonl
The demo needs no API key, makes no network calls, and creates no
provider charges. It sends six scripted requests through the real engine
with a fake provider and made-up prices labeled DEMO, then writes
./inferrail-demo-receipts.jsonl in your current directory.
Setting up Python or fixing command not found
python3 -m venv .venv && source .venv/bin/activate   # Windows: .venv\Scripts\activate
python -m pip install inferrail
If inferrail is still not found, the environment is not active or pip
installed into a different Python. More in
docs/self-hosting.md.
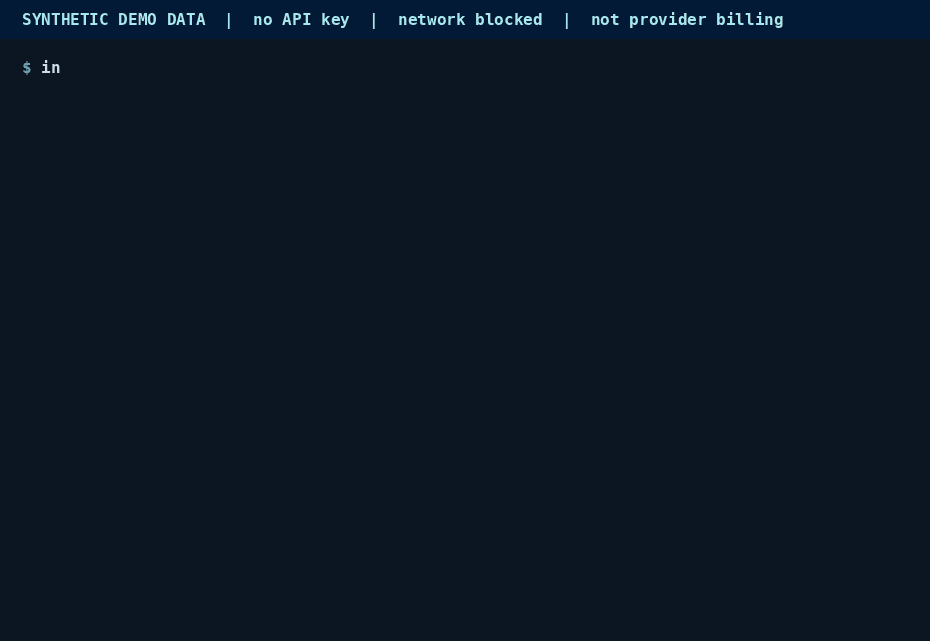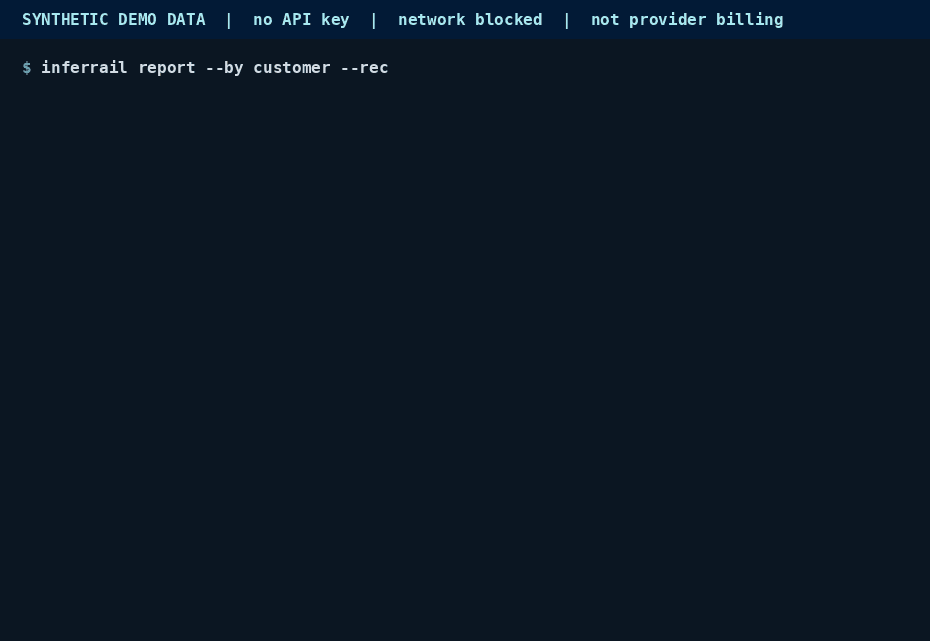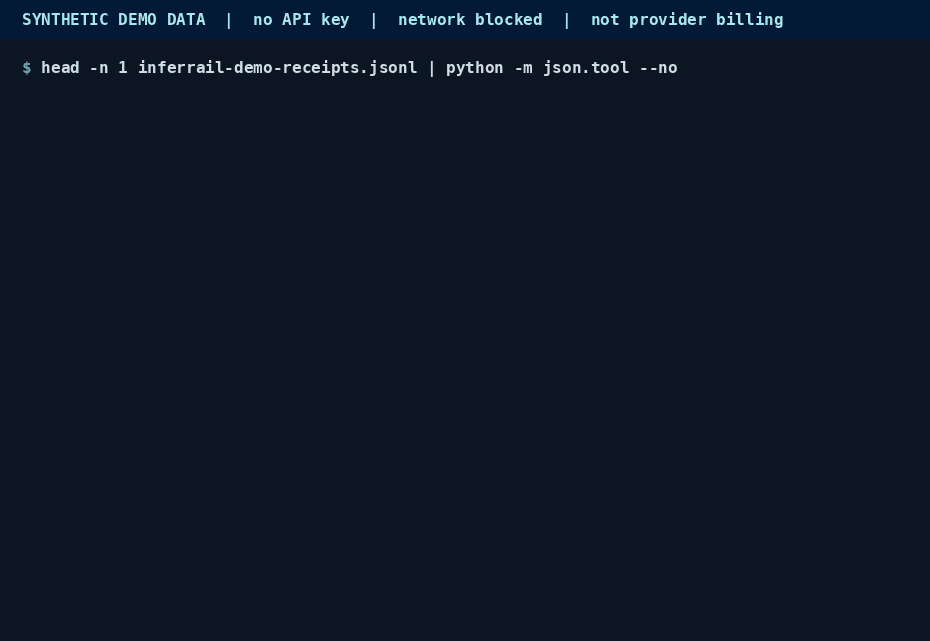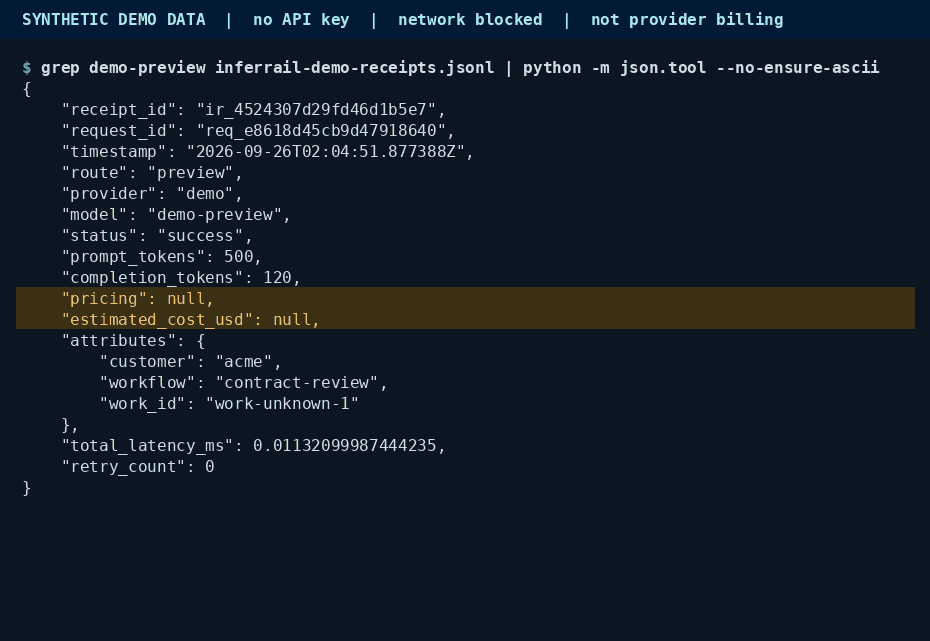
Real run of inferrail demo 0.4.3 with networking blocked. Synthetic data, not provider billing.
Static image ·
captured output ·
how it was made
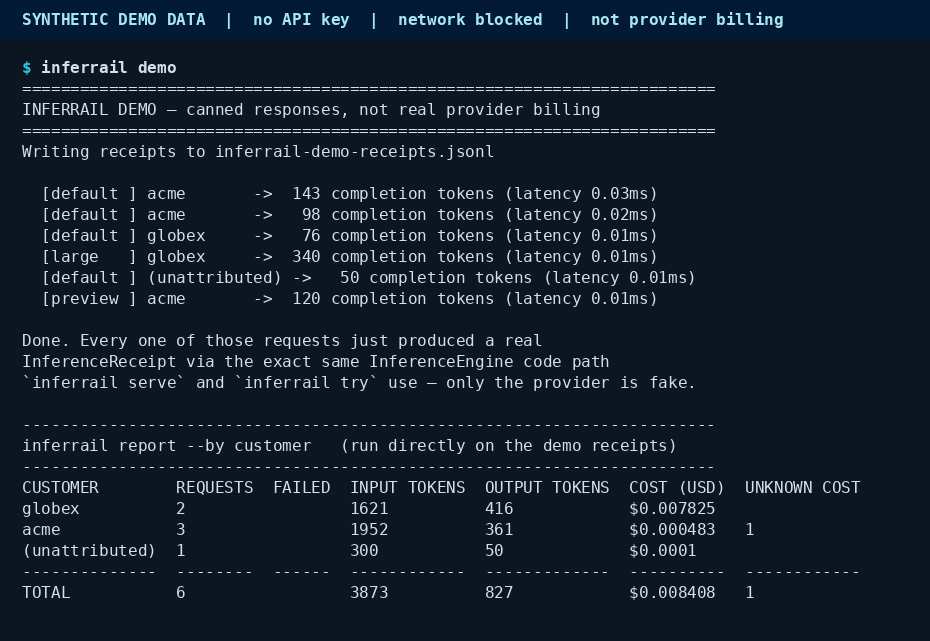
In the report, acme shows one request with unknown cost: the demo's
preview model has no price on file, so its receipt has
"pricing": null and "estimated_cost_usd": null. The COST (USD)
column adds up known costs only. It is not a complete bill when the
unknown count is above zero.
Send a real request
This uses your own provider account, which bills you as usual. Run the gateway in one terminal, with the key set in that terminal, because the gateway is the process that calls the provider:
export OPENAI_API_KEY=...        # and/or ANTHROPIC_API_KEY=...
inferrail serve --quickstart
Then point your client at it from another terminal or your app:
from openai import OpenAI

client = OpenAI(base_url="http://127.0.0.1:8000/v1", api_key="not-needed")
client.chat.completions.create(
    model="gpt-4o-mini",
    messages=[{"role": "user", "content": "Say hello in five words."}],
    extra_headers={"X-Inferrail-Attribute-Customer": "acme"},
)
import anthropic

# No /v1 here: the Anthropic SDK adds /v1/messages itself.
client = anthropic.Anthropic(base_url="http://127.0.0.1:8000", api_key="not-needed")
client.messages.create(
    model="claude-haiku-4-5-20251001",
    max_tokens=256,
    messages=[{"role": "user", "content": "Say hello in five words."}],
)
The client's api_key is a placeholder; the gateway ignores it unless
you set INFERRAIL_GATEWAY_TOKEN. Then run inferrail report --by customer
in the gateway's directory. The gateway listens only on 127.0.0.1 by
default. Set INFERRAIL_GATEWAY_TOKEN before exposing it anywhere else
(SECURITY.md).
How it works

Each request is routed by model to a configured provider
(routing), executed with retries, and
measured. Cost is computed only when the provider reports usage and a
verified price is on file; otherwise it stays null, never a guessed
$0 (calculator). Architecture:
docs/ARCHITECTURE.md. Diagram source:
scripts/render_flow_svg.py.
Integrations
Supported today: POST /v1/chat/completions (OpenAI-compatible, with
streaming and tool calls), POST /v1/messages (Anthropic-compatible,
with streaming and tool use), and GET /health. Any client or framework
that lets you set a base URL and sends those shapes can use the gateway.
Attribution, work grouping, framework examples, and MCP setup are in
docs/integrations.md.
Voice agents. Inferrail has no native voice support. A voice stack can route its text LLM stage through Inferrail if that stage accepts a custom OpenAI- or Anthropic-compatible base URL and sends a supported request shape. Only that stage's tokens and cost are recorded. Audio, speech-to-text, text-to-speech, the Realtime API, and full call cost are not covered, and no voice framework has been tested by this project (details).
MCP
Inferrail ships an MCP server with two read-only tools, so an agent can ask what its AI work cost. The tools read your local receipts file. They do not run inference, spend provider budget, change configuration, or write any file. Inferrail receipts store usage and cost metadata without persisting prompt or response bodies, so the tools have none to return. (The gateway itself still handles prompts and responses in memory while forwarding them to the provider; see Privacy boundary.)
| Tool | What it answers |
|---|---|
get_spend | Known cost, tokens, and request counts grouped by provider, model, route, or any attribute you tag requests with (customer, workflow, work_id), optionally within a time window. Requests with unknown pricing are counted separately, not as $0. |
get_health | Whether the gateway answers GET /health, plus the most recent receipt. |
There are no separate customer, workflow, or job tools. get_spend groups
by whatever tags your requests carry, so grouping by customer,
workflow, or work_id (a unit of tagged work, such as one job) only
covers requests that were sent with that tag
(attribution).
The server speaks stdio and is started by your MCP client:
uvx inferrail mcp # or: pip install inferrail && inferrail mcp
Client config (Claude Desktop, Cursor, and other clients that use
mcpServers; VS Code uses the same entry under servers):
{
  "mcpServers": {
    "inferrail": {
      "command": "uvx",
      "args": ["inferrail", "mcp"],
      "env": {
        "INFERRAIL_RECEIPTS_PATH": "/absolute/path/to/inferrail-receipts.jsonl"
      }
    }
  }
}
Claude Code: claude mcp add inferrail -e INFERRAIL_RECEIPTS_PATH=/absolute/path/to/inferrail-receipts.jsonl -- uvx inferrail mcp
Set INFERRAIL_RECEIPTS_PATH to your receipts file. Clients start the
server from their own working directory, so the default
./inferrail-receipts.jsonl is rarely the right place. For
serve --app-mode, point it at receipts.db in Inferrail's data
directory (~/.local/share/inferrail on Linux, ~/Library/Application Support/inferrail
on macOS, %APPDATA%\inferrail on Windows).
Then ask, for example: "How much did the work tagged contract_review_42
cost?" If your requests carried work_id=contract_review_42, the agent
calls get_spend with by: "work_id" and reads that group.
Full tool contract: inferrail-mcp/README.md.
Status
| Capability | Status |
|---|---|
| Text LLM gateway, cost receipts, reports, attribution | Available in the 0.4.3 developer preview on PyPI |
| Work grouping and application-declared outcomes | Available. Reports known cost only and counts unknown-cost receipts separately |
| Budget checks | Available, opt-in. Applies only to supported requests through this gateway; unpriced models are not checked (details) |
Local dashboard (serve --app-mode), read-only MCP tools | Available. Both ship in the PyPI package (MCP) |
AP invoice-exception recovery (inferrail ap demo) | Experimental workflow with a bounded contract (docs) |
| Hosted cost-gateway trial (tryinferrail.com/try) | Preview. With a real key, the hosted process holds it in memory, and the trial expires within 4 hours of adding it (key handling) |
| Hosted Work Economics and Economic Authority | Experimental, Base Sepolia testnet only. Work Economics: docs, example. Economic Authority: docs, example |
| Referral rewards, paid tiers | Planned. Not part of the package |
| Audio, speech-to-text, text-to-speech, Realtime API, embeddings, images, batch | Not supported |
| Providers beyond OpenAI- and Anthropic-compatible APIs (Gemini, Bedrock native) | Not supported |
Inferrail does not account for all spending on a provider account, only the supported requests that pass through a running gateway. Full scope and non-goals: docs/PRODUCT.md.
Documentation
- docs/integrations.md: clients, attribution, work tracking, voice, MCP
- docs/self-hosting.md: install, configuration, storage, budgets, dashboard
- docs/PRODUCT.md: exact current scope
- docs/ARCHITECTURE.md and docs/adr/: how and why it is built this way
- docs/privacy/usage-ping.md: the usage beacon
- openapi.json, config.schema.json, llms.txt: machine-readable references
Feedback, security, license
- Questions and bugs: GitHub issues.
- Security or privacy vulnerabilities: please report privately, as described in SECURITY.md.
- Contributing: CONTRIBUTING.md.
pytestneeds no API key or network. - License: Apache-2.0.