Reddit Scraper: Posts, Comments & Subreddits (Apify Actor)
Search Reddit and pull posts and comment threads from subreddits, search results, post URLs and user profiles: real score, comment count, clean text, date and keyword filters, parent IDs for threads. No login and no Reddit API key. $1.50 per 1,000 posts, $0.80 per 1,000 comments, $0.02 per run start; not-found and error rows are free. Runs as an Apify Actor, callable from MCP clients via the Apify MCP server (https://mcp.apify.com/?tools=cliqtomedia/reddit-scraper).
Hosted MCP Server
npx add-mcp 'https://mcp.apify.com/?tools=cliqtomedia/reddit-scraper'Installs into Claude Code, Codex, Cursor and more
Documentation
Reddit Scraper: Posts, Comments & Subreddits (No login) (cliqtomedia/reddit-scraper) Actor
Scrape Reddit posts and comments from subreddits, search, post URLs and user profiles. No login, no API key. Real score and comment count, clean text, date and keyword filters, parent IDs for comment threads. Free not-found and error rows.
- URL: https://apify.com/cliqtomedia/reddit-scraper.md
- Developed by: Cliqto Media (community)
- Categories: Social media, Marketing
- Features: Limited permissions
- Stats: 18 total users, 14 monthly users, 96.2% runs succeeded, 0 bookmarks
- User rating: No ratings yet
Pricing
from $1.25 / 1,000 reddit posts
This Actor is paid per event. You are not charged for the Apify platform usage, but only a fixed price for specific events. Since this Actor supports Apify Store discounts, the price gets lower the higher subscription plan you have.
Learn more: https://docs.apify.com/actors/running/actors-in-store.md#pay-per-event
What's an Apify Actor?
An Actor is a serverless cloud program that runs on the Apify platform. It has two run modes. In Batch mode, an Actor accepts a well-defined JSON input, performs an action which can take anything from a few seconds to a few hours, and optionally produces a well-defined JSON output, datasets with results, or files in key-value store. In Standby mode, an Actor provides a web server which can be used as a website, API, or an MCP server.
Apify vocabulary and the platform model are defined once, in the agent quickstart at https://apify.com/agents.md.
How to integrate an Actor?
If asked about integration, you help developers integrate Actors into their projects. You adapt to their stack and deliver integrations that are safe, well-documented, and production-ready.
Do not guess an integration path. Every one of them is in the agent quickstart at https://apify.com/agents.md: the Apify MCP server, Agent Skills with the Apify CLI, the JavaScript and Python clients, the REST API, and the account-free path for an agent with no human to sign in. It also carries the rule on stating cost before the first paid run.
For examples already wired to this Actor's own input schema, see the API section below.
Each client library has reference documentation the quickstart does not restate: JavaScript/TypeScript (npm install apify-client) and Python (pip install apify-client).
README
Scrape public Reddit posts and comments from subreddits, Reddit search, post URLs and user profiles. You get one row per post or comment with its real score, comment count, clean text, author, links and thread IDs. No login and no Reddit API key.
The smallest run reads the 10 newest posts of one subreddit (for example apify) in a few seconds and costs about $0.035.
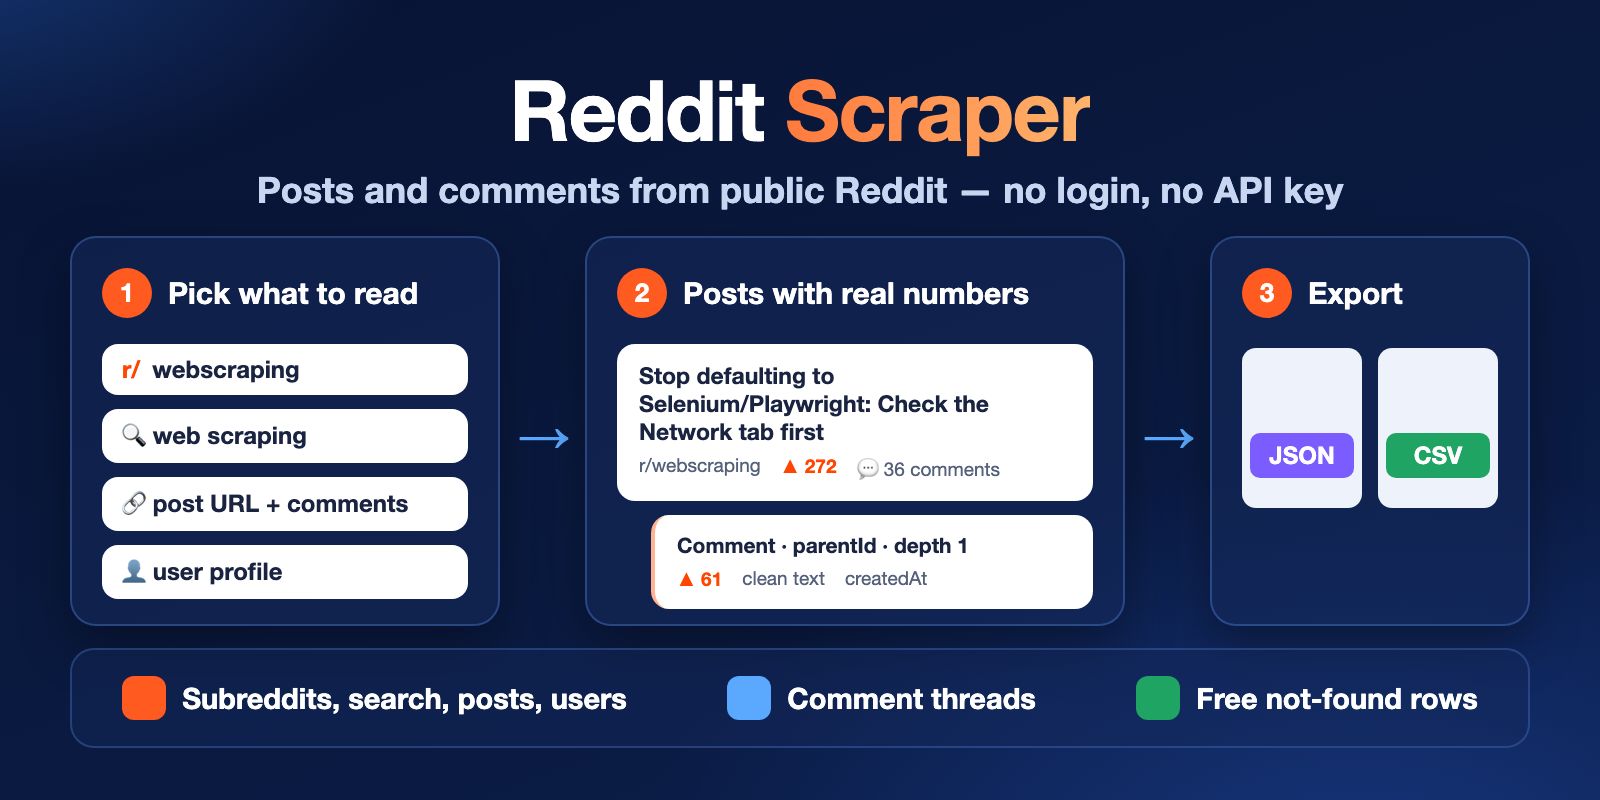
Table of contents
- What it does
- How it works
- Quick start
- Use cases
- Input
- Output
- Pricing
- Limits
- API, export and integrations
- Troubleshooting
- FAQ
- Related Actors
- Support
What it does
The Actor reads public pages of Reddit and saves posts and comments to a Dataset. Choose one mode:
subreddit— posts from one or more subreddits (new, hot, top or rising);search— posts that match keywords, across all public subreddits;post— single posts by URL or ID, usually with their comments;user— posts submitted by a user.
In every mode you can also add comments for each post (maxCommentsPerPost). In subreddit, search and user mode you can keep only posts from a date range (postedAfter, postedBefore) or with certain keywords (keywords); dropped posts are free. Each comment keeps parentId and depth, so you can rebuild the reply tree.
Targets that do not exist, are empty or cannot be read get a free status row. You always see what happened to each subreddit, query, post or user.
Good fit
- Watch what people say about a brand, product or topic in a subreddit or in search.
- Collect posts and comment threads for market research or a text dataset (AI, RAG, sentiment).
- Export the posts of known users or a list of posts to a spreadsheet.
Not a fit: private or login-only content, user comment history and the official Reddit API — see Limits.
How it works
- You choose a mode and give subreddits, search queries, post URLs or usernames.
- The Actor opens the same public Reddit pages a logged-out visitor sees, page by page, through Apify residential proxies, until it has
maxPostsposts per target andmaxCommentsPerPostcomments per post. - It saves one Dataset row per post or comment, a free status row for each target that is missing, empty or blocked, and a run summary (
RUN_SUMMARY) with counts and warnings.
Quick start
-
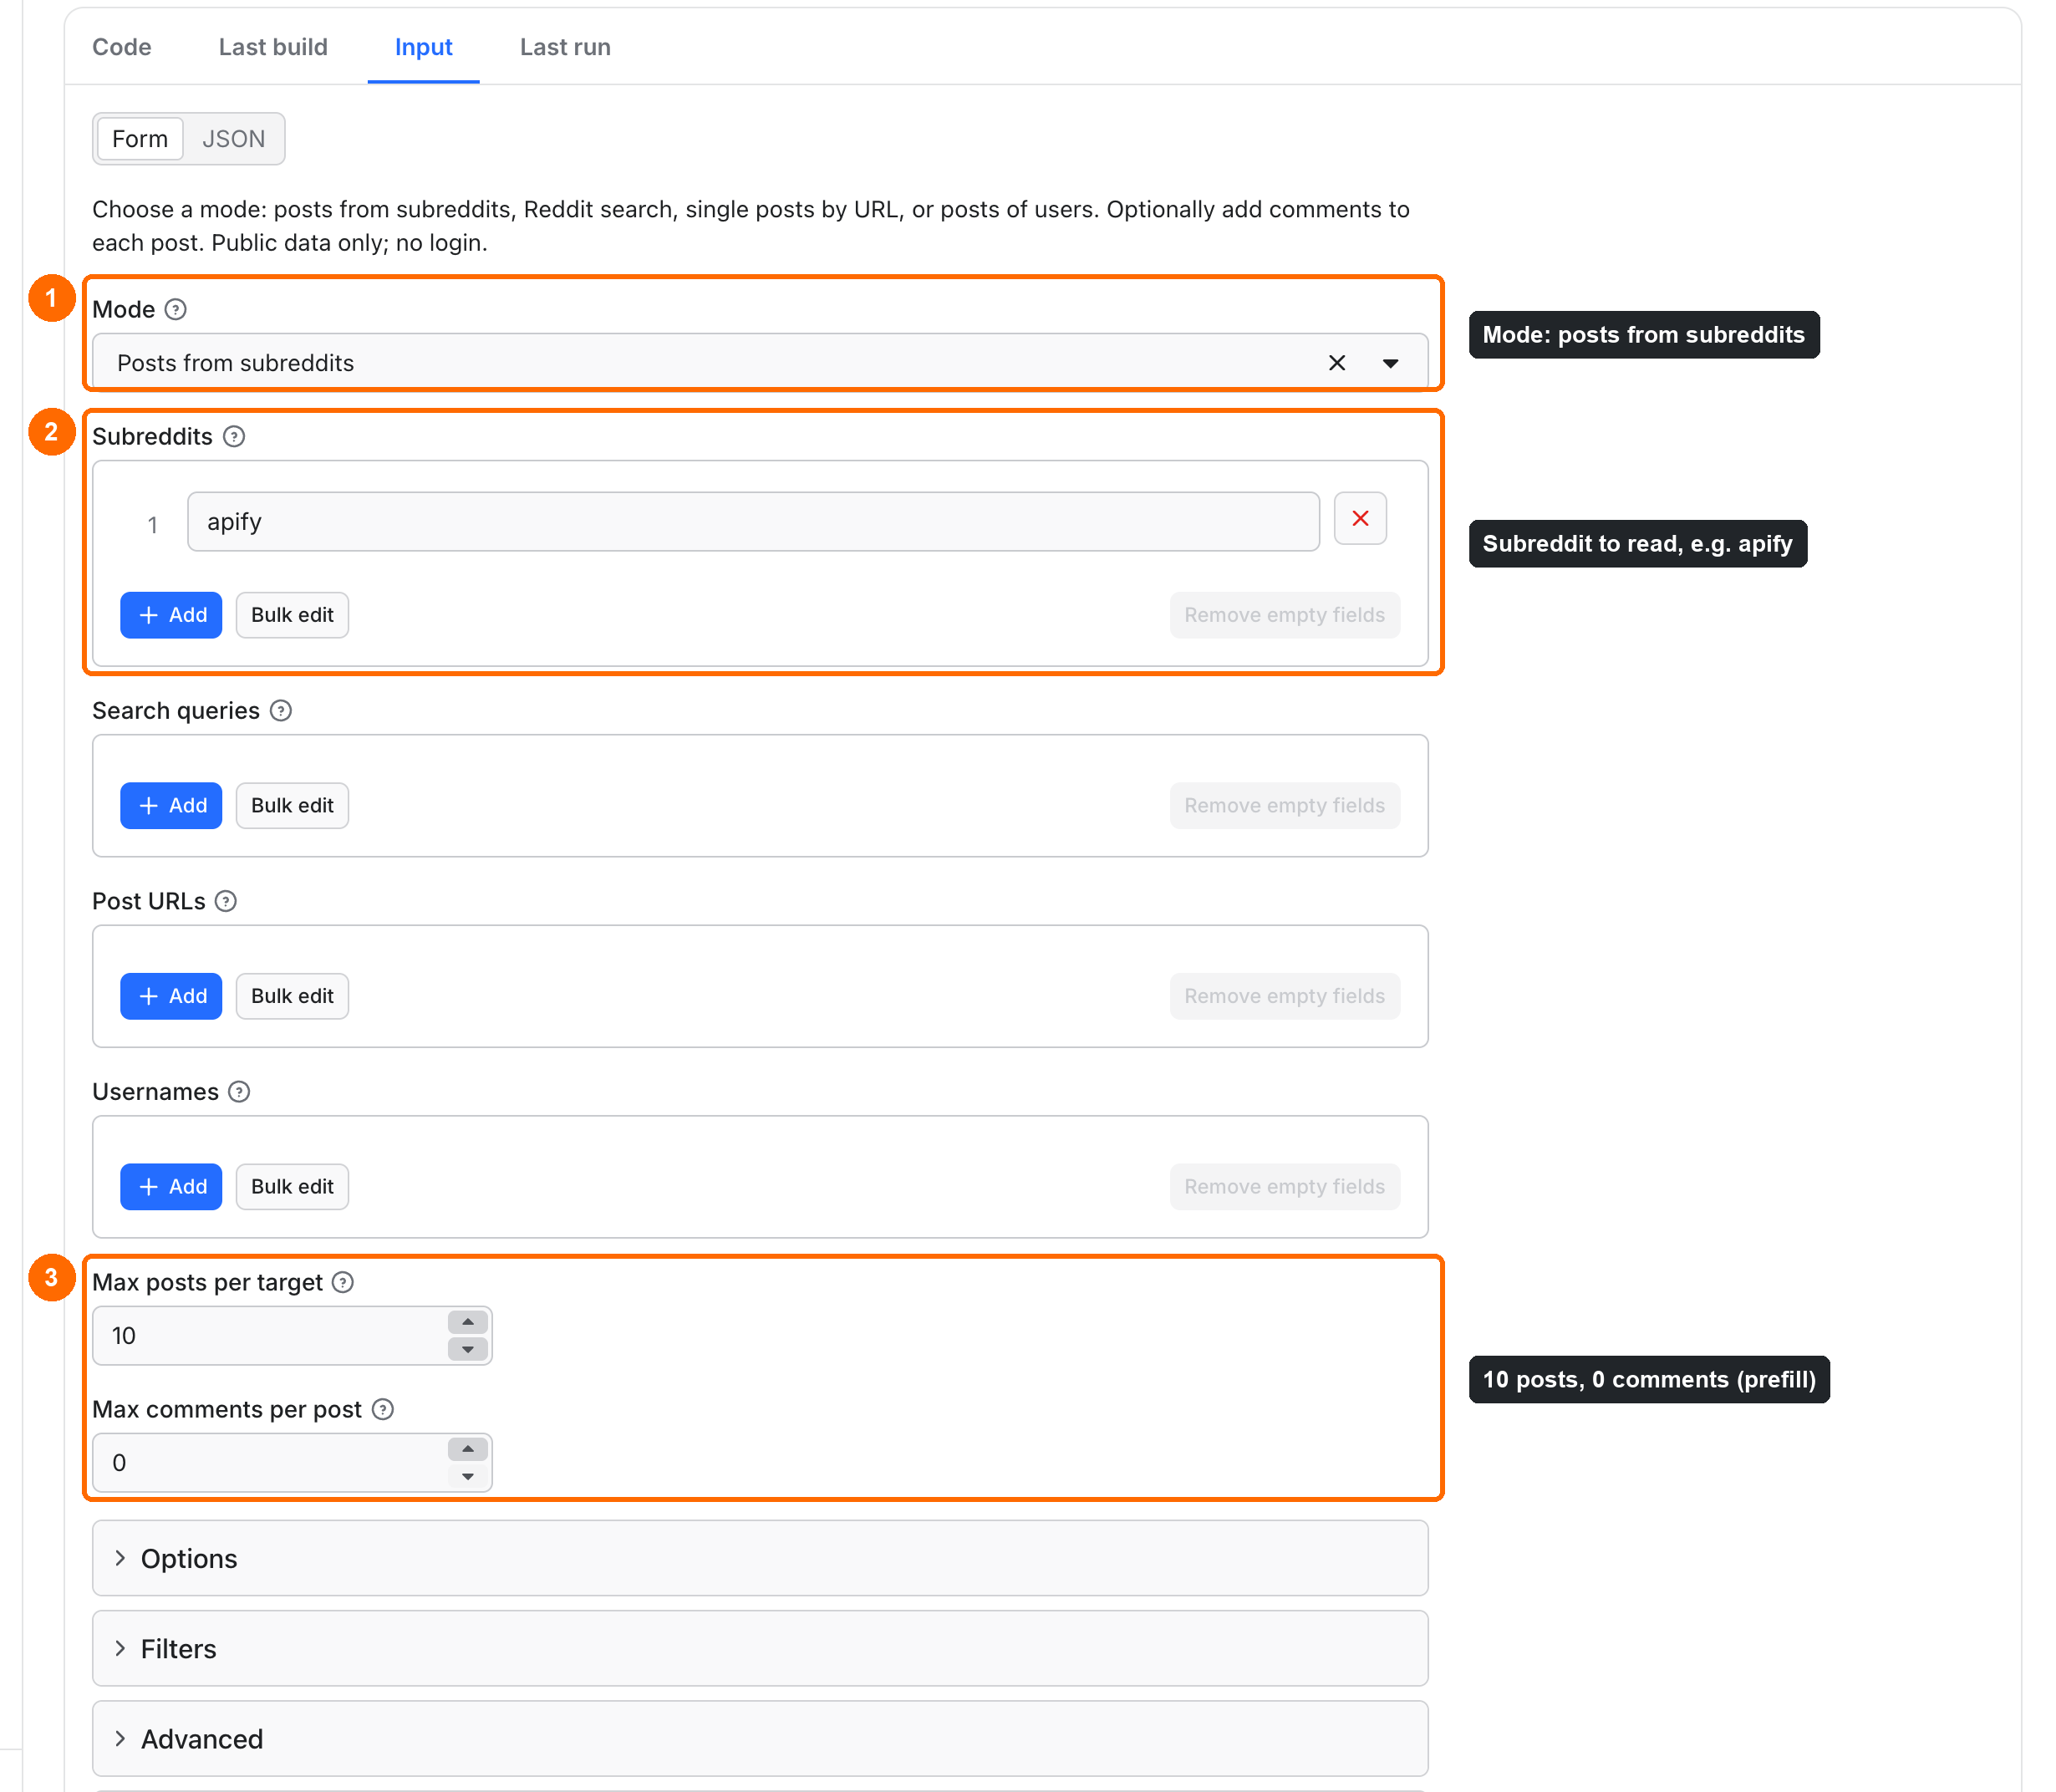
Open the Input tab. Keep Mode =
Posts from subreddits(box 1 in the picture). -
Type a subreddit in Subreddits, for example
apify(box 2). -
Keep Max posts per target = 10 and Max comments per post = 0 (the prefill, box 3).
-
Click Start.
-
Open the Output tab and check
title,scoreandnumCommentsof the first rows.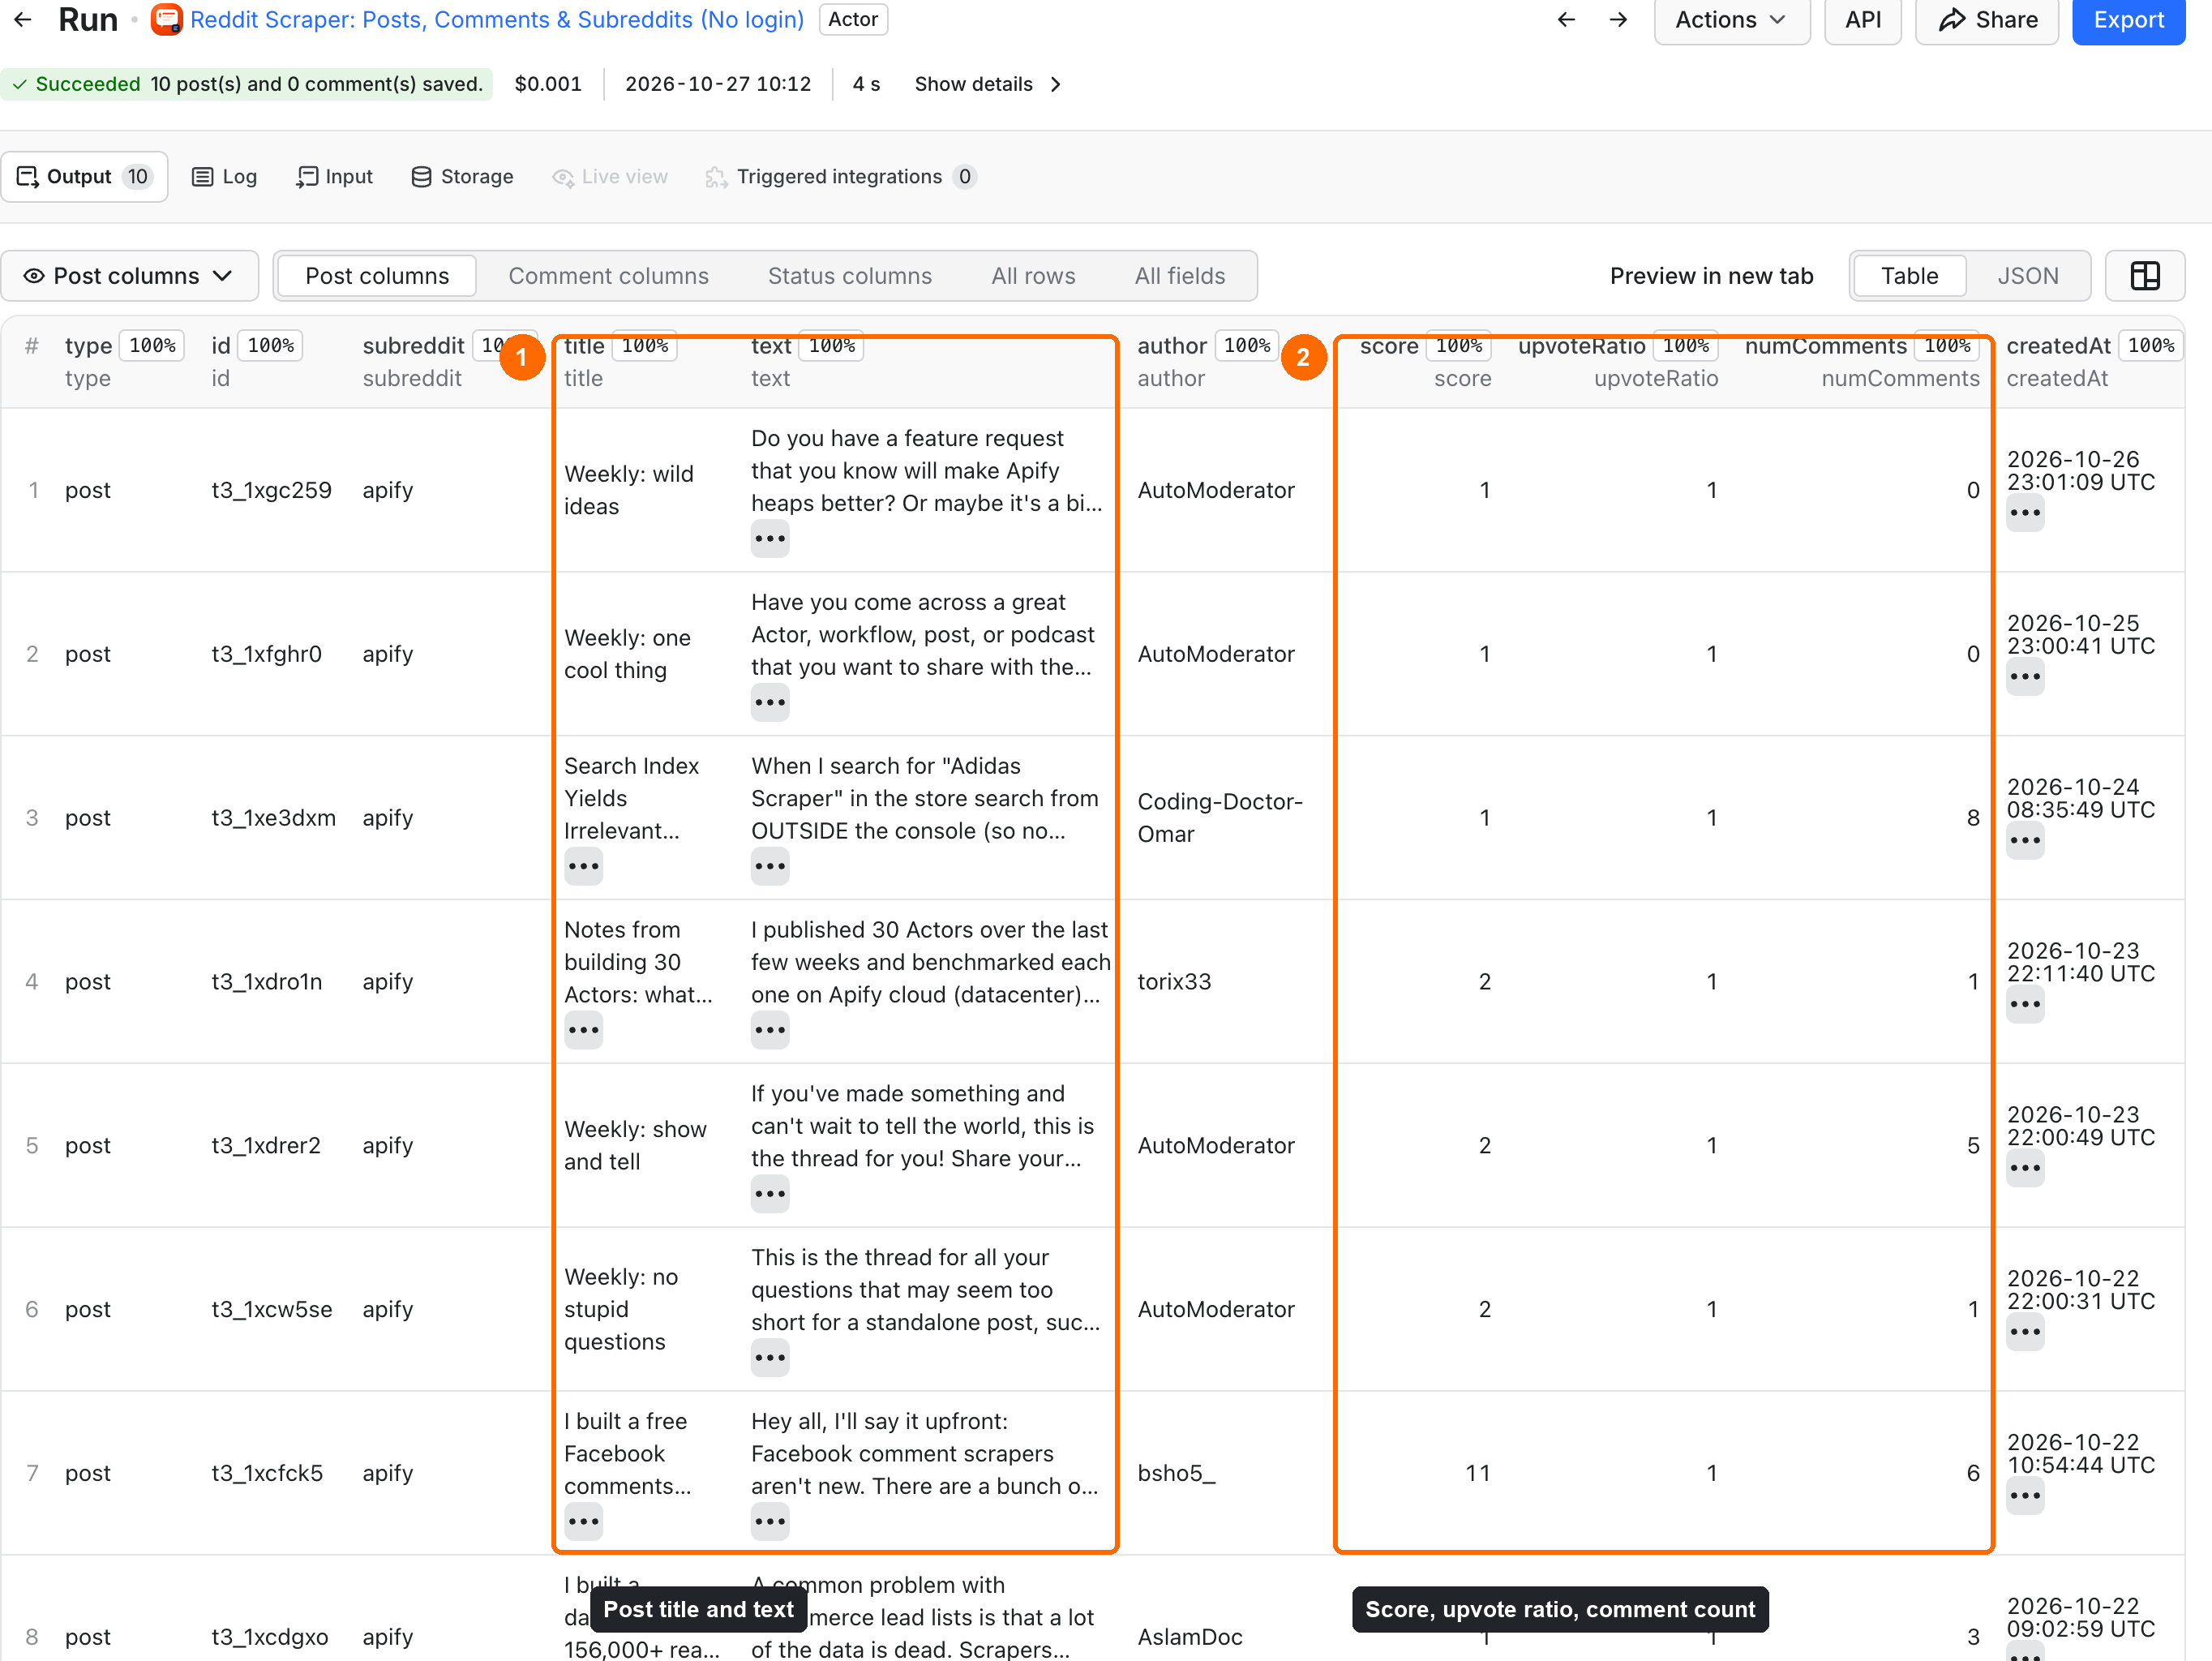
Expected result: 10 newest posts of r/apify, one row each, in about 5 seconds.
Use cases
| Buyer job | Input path | Output entity | Key fields | Next step |
|---|---|---|---|---|
| Brand or topic monitoring | mode: search, searchQueries, sort: new | post | title, text, subreddit, score, createdAt | schedule the run, export CSV |
| Community research | mode: subreddit, subreddits, sort: top, timeFilter: month | post + comment | score, numComments, text, parentId | spreadsheet or BI tool |
| Discussion analysis | mode: post, postUrls, maxCommentsPerPost | post + comment | text, depth, parentId, score | sentiment or AI pipeline |
| Author research | mode: user, usernames | post | subreddit, title, score, createdAt | spreadsheet |
Input
Input fields
| Field | Plain name | Type | Required | Default / prefill | Allowed values | Effect |
|---|---|---|---|---|---|---|
mode | Mode | string | yes | subreddit | subreddit, search, post, user | What to read; only the list for this mode is used |
subreddits | Subreddits | string[] | for subreddit | prefill ["apify"] | up to 50; apify, r/apify or a subreddit URL | Subreddits to read |
searchQueries | Search queries | string[] | for search | — | up to 50 keywords or phrases | Searches across all public subreddits |
postUrls | Post URLs | string[] | for post | — | up to 50 post URLs or IDs (1x64f49, t3_1x64f49, redd.it/1x64f49) | One post row per URL, plus comments |
usernames | Usernames | string[] | for user | — | up to 50; spez, u/spez or a profile URL | Posts submitted by each user |
maxPosts | Max posts per target | integer | no | 10 | 1–1000 | Posts for each subreddit, query or user (not used in post mode) |
maxCommentsPerPost | Max comments per post | integer | no | 0 | 0–500 | 0 = posts only; otherwise comments with replies for each post |
sort | Post sort | string | no | new | new, hot, top, rising, relevance, comments | Order of posts |
timeFilter | Time range | string | no | all | hour, day, week, month, year, all | Time range for top sort and for search |
commentSort | Comment sort | string | no | top | top, new, best, controversial, old | Order of comments |
postedAfter | Posted on or after | string | no | — | date YYYY-MM-DD or ISO time (UTC) | Keeps posts created at or after this time; not used in post mode |
postedBefore | Posted before | string | no | — | date YYYY-MM-DD or ISO time (UTC) | Keeps posts created before this time |
keywords | Keywords | array of strings | no | — | up to 20 | Keeps posts whose title or text contains any of them, any case; in search mode only the title is checked |
proxy | Proxy | object | no | Apify Proxy, RESIDENTIAL, US | proxy editor | Reddit blocks datacenter IPs; keep the default |
The same post given twice (for example as an ID and as a URL) is saved once. Share links (reddit.com/r/.../s/...) are not supported: open them in a browser and copy the full post URL.
Interacting settings
| When | Setting | Effective behavior |
|---|---|---|
mode: subreddit | sort | new, hot, top, rising; another value falls back to the nearest one (shown in the run summary) |
mode: search | sort | relevance, new, top, comments |
mode: user | sort | new, hot, top |
sort: top or mode: search | timeFilter | Limits posts to the chosen time range; other sorts ignore it |
mode: post | maxCommentsPerPost | Set it above 0 to get comments; maxPosts is ignored |
postedAfter with sort: new | listing pages | Reading stops at the first page older than postedAfter |
postedAfter, postedBefore, keywords | maxPosts | maxPosts counts kept posts; dropped posts are free. With other sorts the Actor reads up to the end of the listing (about 1,000 posts) |
commentSort: new | maxCommentsPerPost | Reddit may end a "new" comment list early; the run adds a warning. Use top for long threads |
Input examples
Newest posts of a subreddit (prefill)
{
  "mode": "subreddit",
  "subreddits": ["apify"],
  "maxPosts": 10,
  "maxCommentsPerPost": 0
}
Expected output: 10 post rows with title, text, score, numComments, upvoteRatio, postType. Cost on the free plan: $0.035.
Search with top posts of the month
{
  "mode": "search",
  "searchQueries": ["web scraping"],
  "sort": "top",
  "timeFilter": "month",
  "maxPosts": 15
}
Expected output: 15 post rows from different subreddits with subreddit, title, text and score.
Posts of one week that mention a keyword
{
  "mode": "subreddit",
  "subreddits": ["webscraping"],
  "sort": "new",
  "postedAfter": "2026-10-01",
  "postedBefore": "2026-10-08",
  "keywords": ["proxy", "captcha"],
  "maxPosts": 50
}
Expected output: up to 50 post rows created from 1 to 7 October 2026 whose title or text contains "proxy" or "captcha". RUN_SUMMARY.counts.filteredOut shows how many posts the filters dropped.
One post with its comments
{
  "mode": "post",
  "postUrls": ["https://www.reddit.com/r/AskReddit/comments/1x3uinu/what_previously_glorified_careers_are_struggling_now/"],
  "maxCommentsPerPost": 100,
  "commentSort": "top"
}
Expected output: 1 post row and up to 100 comment rows with parentId, depth, score and text.
Output
Each row has type: post, comment or status. The Output tab has four views: All rows, Post columns, Comment columns and Status columns.
Output fields
| Field | Meaning | Type | Can be empty? |
|---|---|---|---|
type | post, comment or status | string | no |
id | Reddit ID: t3_... for posts, t1_... for comments | string | no (status rows: absent) |
postId | t3_ ID of the post (for a comment: its post) | string | no (status rows: absent) |
parentId | Comments: t3_ post ID for a top-level comment, t1_ comment ID for a reply | string | null on posts |
depth | Comments: 0 = top level, 1 = reply, … | integer | null on posts |
subreddit | Subreddit name without r/ | string | rarely null |
title | Post title (on comments: title of their post) | string | rarely null |
text | Post body or comment text, plain text, HTML entities decoded | string | null for link, image and video posts without a body |
author | Username | string | null for deleted or removed authors |
authorId | t2_ ID of the post author (posts only) | string | null on comments, and in post mode once Reddit RSS ends |
score | Upvotes minus downvotes, as Reddit shows it | integer | null when Reddit hides it or the comment is deleted |
upvoteRatio | Share of upvotes, 0–1 (posts) | number | null in search and post modes |
numComments | Number of comments on the post | integer | null on comments |
url | Link to the post or comment on reddit.com | string | null for some deleted comments |
linkUrl | Link, image, video or gallery URL of the post | string | null for text posts, and in post mode once Reddit RSS ends |
postType | text, link, image, video, gallery, … | string | null in search and post modes |
createdAt | Creation time, ISO 8601 UTC | string | rarely null |
status | Status rows: not_found, no_results or error | string | status rows only |
message | Status rows: what happened, in plain words | string | status rows only |
errorCode | Status rows: INVALID_INPUT, SOURCE_BLOCKED, NOT_CHECKED, … | string | null for not_found and no_results |
mode | Mode of the run | string | no |
input | Your subreddit, query, post URL or username as given | string | no |
source | Always Reddit | string | no |
fetchedAt | Time the row was read, ISO 8601 UTC | string | no |
null means Reddit did not show the value. It is never replaced with 0: a deleted comment has score: null, not 0.
Output entities and surfaces
| Situation | Where | Result shape | What to do |
|---|---|---|---|
| Normal post or comment | Dataset | type: post / type: comment | Export or filter by type |
| Subreddit or post does not exist | Dataset | free status: not_found row (a subreddit can also give no_results, see Troubleshooting) | Check the spelling |
| Empty listing or search; user with no posts or no such user | Dataset | free status: no_results row | Try another sort or timeFilter; check the username |
| Invalid input or source failure | Dataset | free status: error row with errorCode | Read message; fix input or retry later |
| Target skipped by a run cost limit (too many missing posts or filter drops) | Dataset | free status: error row, errorCode: NOT_CHECKED | Run these targets again on their own |
| Whole run | Key-value store RUN_SUMMARY | status, reason, counts, targets, warnings | Check which targets returned data |
RUN_SUMMARY.status is complete when all targets were read (some may still have a free NOT_CHECKED row, counted in counts.errors and named in message) and partial when the run stopped early: your charge limit was reached (CHARGE_LIMIT, run still SUCCEEDED), the run timeout was near, or Reddit failed after some rows were saved. Saved rows stay in the Dataset in every case.
Output example
Post from the prefill run (trimmed text):
{
  "type": "post",
  "id": "t3_1x64f49",
  "postId": "t3_1x64f49",
  "parentId": null,
  "depth": null,
  "subreddit": "apify",
  "title": "Weekly: job board",
  "text": "Are you expanding your team or looking to hire a freelancer for a project? ...",
  "author": "<username>",
  "score": 1,
  "upvoteRatio": 1,
  "numComments": 0,
  "url": "https://www.reddit.com/r/apify/comments/1x64f49/weekly_job_board/",
  "linkUrl": null,
  "postType": "text",
  "createdAt": "2026-10-14T22:00:47.863Z",
  "mode": "subreddit",
  "input": "apify",
  "source": "Reddit",
  "fetchedAt": "2026-10-15T04:02:10.190Z"
}
Comment row (post mode):
{
  "type": "comment",
  "id": "t1_pfecihy",
  "postId": "t3_1x3uinu",
  "parentId": "t3_1x3uinu",
  "depth": 0,
  "subreddit": "AskReddit",
  "title": "What previously glorified careers are struggling now?",
  "text": "Graphic design has taken it on the chin",
  "author": "<username>",
  "score": 23359,
  "createdAt": "2026-10-12T06:35:32.317Z",
  "source": "Reddit"
}
Status row:
{
  "type": "status",
  "status": "not_found",
  "input": "zzzzzz9",
  "mode": "post",
  "message": "Post zzzzzz9 was not found: it may be deleted, removed, private or the ID is wrong.",
  "errorCode": null,
  "source": "Reddit"
}
Moving from another Reddit scraper
Field names differ from some other Reddit Actors, so this is not a drop-in replacement. Common mapping: body → text, username → author, communityName → subreddit, upVotes → score, dataType → type, scrapedAt → fetchedAt. There is no html field: text is already plain text.
Pricing
Pricing unit
You pay per event (pay-per-event). Apify platform usage (compute and proxy) is included in these prices.
| Event | Free | Bronze | Silver | Gold and higher |
|---|---|---|---|---|
Run start (apify-actor-start) | $0.02 | $0.02 | $0.02 | $0.02 |
Post row (post) | $0.0015 | $0.0014 | $0.0013 | $0.00125 |
Post from a URL (post-url), post mode, from 2026-11-10 | $0.0029 | $0.0027 | $0.0025 | $0.0022 |
Comment row (comment) | $0.0008 | $0.00075 | $0.0007 | $0.00065 |
statusrows (not_found,no_results,error) are free.- Posts dropped by
postedAfter,postedBeforeorkeywordsare free. - In
postmode each post is a separate Reddit page, so a post row there costs more (post-url). Until 2026-11-10 these rows are charged aspost. - A run that finds nothing pays only the run start, $0.02.
- The start fee scales with run memory (per GB): it is charged once per run up to 1 GB. The Actor picks 256–1024 MB itself; if you set 2048 MB, the start is charged twice.
- Set Maximum cost per run in run options to cap spending. When the cap is reached, the run stops, keeps the saved rows and ends as SUCCEEDED with
partialinRUN_SUMMARY.
Cost examples (Free plan prices)
| Scenario | Input scope | Rows | Charge | Measured time |
|---|---|---|---|---|
| Prefill | 1 subreddit, 10 posts | 10 posts | $0.035 | ~4 s |
| Search | 3 queries × 10 posts | 30 posts | $0.065 | ~20 s |
| Community research | 200 posts + comments | 200 posts + 1,297 comments | $1.36 | ~85 s |
| Nothing found | 6 searches with no matches | 0 (status rows) | $0.02 | ~5 s |
Limits
- Only public content. No login, no private, banned or quarantined subreddits, no private messages.
- In
usermode only the user's posts are collected, not their comments. - This is not the official Reddit API. Reddit can change its pages; the Actor reports missing text or score in the run summary when that happens.
- Up to 50 subreddits, queries, posts or users per run; up to 1,000 posts per target and 500 comments per post.
- Reddit shows at most about 1,000 posts per listing or search (970–995 in our tests); the run summary warns when it lists fewer than
maxPosts. - Reddit ends its RSS feeds on 2026-11-13. After that,
textisnullinsearchrows (score and comments stay), andpostmode rows have nolinkUrlandauthorId. Inpostmode a run checks at most 5 missing posts plus 1 per 10 found posts; further missing posts get a freeNOT_CHECKEDerror row. The run summary warns once when RSS stops answering. - Filters: a run reads at most 250 dropped posts plus 10 per saved post; after that, listings are not read and targets without posts get a free
NOT_CHECKEDrow. Narrow the listing withsort: newandpostedAfter, or withtimeFilter. - Large searches can take several minutes. The default run timeout is 1 hour; the Actor stops 20 seconds before the timeout and keeps all saved rows.
API, export and integrations
- Export: download the Dataset as JSON, CSV, Excel, XML or HTML from the Output tab, or export one view (Post columns, Comment columns, Status columns).
- API: start the Actor with the Apify API or the Apify JavaScript/Python client and read Dataset items; check
RUN_SUMMARYin the default Key-value store. - Scheduling: create a Task with your input and a schedule in Apify Console, for example a daily
searchwithsort: new. - Webhooks / no-code: use Apify integrations (Make, Zapier, n8n, webhooks) to send new rows to another tool.
Use with AI agents (MCP)
- MCP server with only this Actor:
https://mcp.apify.com?tools=cliqtomedia/reddit-scraper - Smallest useful input:
{"mode": "subreddit", "subreddits": ["apify"], "maxPosts": 10, "maxCommentsPerPost": 0} - Key output fields:
type(post, comment or status),title,text,score,numComments,url. - The prefill run takes about 4 seconds and costs $0.035 on the Free plan. Keep
maxPostssmall (10–50) for answers in under a minute; search is slower than subreddit mode.
Troubleshooting
A subreddit returns a not_found row
Symptom: no posts, one status: not_found row, or no_results.
Why both: Reddit RSS proves that a subreddit is missing only after it has given posts in the same run. Before that (or after RSS ends on 2026-11-13), a missing, banned or private subreddit gives no_results.
Likely reason: the subreddit does not exist, is banned or private, or the name has a typo.
Action: open https://www.reddit.com/r/<name>/ in a browser and check the name.
A user returns a no_results row
Reddit shows the same empty page for an account without posts, a suspended account and a name that does not exist. So in user mode all three give status: no_results, not not_found.
Action: open https://www.reddit.com/user/<name>/submitted/ in a browser and check the name.
Fewer posts than maxPosts
Symptom: for example 11 posts when you asked for 30.
Likely reason: Reddit shows only these posts for the chosen sort and timeFilter (for example top of a quiet week). RUN_SUMMARY.warnings says so.
Action: choose a longer timeFilter or sort: new.
Fewer comments than maxCommentsPerPost
Likely reason: the post has fewer comments, or commentSort: new was used — Reddit ends that list early. RUN_SUMMARY.counts.commentsCutShort shows it.
Action: use commentSort: top.
error row with NOT_CHECKED
Likely reason: in post mode the run already met its limit of missing posts (5, plus 1 per 10 found posts), so later posts that are not in Reddit's feed are not checked. This keeps runs with many wrong or deleted IDs cheap. With filters: the filters already dropped the run's limit of posts (250 plus 10 per saved post).
Action: run the NOT_CHECKED posts again on their own, or put uncertain IDs at the end of the list. With filters, use sort: new with postedAfter, or a shorter timeFilter, so fewer posts are dropped.
error row with SOURCE_BLOCKED
Likely reason: Reddit refused every proxy session for this target, or the content needs a login. Action: keep the default residential proxy and retry later. Content behind a login is not collected.
Search results change between runs
Reddit's relevance order can change from page to page and from run to run. Use sort: new or sort: top when you need stable results.
FAQ
Do I need a Reddit account or API key?
No. The Actor reads public pages without login, cookies or an API key.
Why are upvoteRatio and postType empty in search?
Reddit does not show them on search results and single post pages. They are filled in subreddit and user modes.
Why is text empty in search results?
Search reads post text from Reddit RSS, which Reddit ends on 2026-11-13. After that, search rows keep title, score, comment count and links, but text is null. To get the text, put the post URLs into post mode.
Do I pay for empty results?
You pay the run start ($0.02). Rows for missing, empty or invalid targets are free.
Is the data fresh?
Yes. Each row is read at run time; fetchedAt shows when. Scores and comment counts change on Reddit after that.
How does it read Reddit, and is it allowed?
The Actor reads only pages that anyone can open without an account. It uses a browser-like HTTP client and Apify residential proxies. It does not log in, does not use your cookies and does not solve CAPTCHAs or browser challenges; if Reddit asks for a login or shows a challenge, that target gets an error row.
Reddit's User Agreement does not allow scraping without Reddit's written consent. Check whether your use is permitted. You are responsible for how you use the data, including personal data rules such as GDPR.
Related Actors
- Bluesky Scraper — the same kind of posts and threads from Bluesky.
- Threads Scraper — posts, replies and search from Threads.
- Quora Answers Scraper — questions and answers with upvotes and views from Quora.
- Hacker News Scraper: Stories, Comments & Parent IDs — stories and comment threads from Hacker News.
- YouTube Comments Scraper — comments and replies under YouTube videos.
Support
For bugs, questions or feature requests, open an issue on the Issues tab of this Actor. Include the run ID, the mode and the error text. Do not post tokens, cookies or private data.
Changelog
This Actor's version history is a separate document: https://apify.com/cliqtomedia/reddit-scraper/changelog.md
Actor input Schema
mode (type: string):
subreddit: posts from each subreddit in Subreddits. search: posts for each query in Search queries. post: one row per post URL, plus its comments. user: posts submitted by each user in Usernames.
subreddits (type: array):
Subreddit mode: up to 50 subreddit names (apify, r/apify) or URLs (https://www.reddit.com/r/apify/). Private, banned or quarantined subreddits are not read.
searchQueries (type: array):
Search mode: up to 50 keywords or phrases, searched across all public subreddits (for example: web scraping).
postUrls (type: array):
Post mode: up to 50 Reddit post URLs (https://www.reddit.com/r/apify/comments/1x64f49/...) or post IDs (1x64f49). Share links (/s/...) are not supported; open them and copy the full URL.
usernames (type: array):
User mode: up to 50 Reddit usernames (spez, u/spez) or profile URLs. Only posts are collected, not the user's comments.
maxPosts (type: integer):
Max posts for each subreddit, search query or user. Reddit itself may show fewer (for example, top posts of a quiet week). Ignored in post mode.
maxCommentsPerPost (type: integer):
0 = posts only. Otherwise up to this many comments (with replies) for each post. In post mode, set it above 0 to get the comments. Each comment is one row and one paid result.
sort (type: string):
Order of posts. Subreddits: new, hot, top, rising. Search: relevance, new, top, comments. Users: new, hot, top. Another choice falls back to the nearest one (shown in the run summary).
timeFilter (type: string):
Time range for Top sort and for search. Other sorts ignore it.
commentSort (type: string):
Order of comments when Max comments per post is above 0.
postedAfter (type: string):
Optional. Keep only posts created on or after this date (YYYY-MM-DD, UTC). With sort New the listing stops at the first older page. Ignored in post mode. Dropped posts are free.
postedBefore (type: string):
Optional. Keep only posts created before this date (YYYY-MM-DD, UTC; the date itself is excluded). Ignored in post mode.
keywords (type: array):
Optional. Keep only posts whose title or text contains at least one of these words (case-insensitive). In search mode only the title is checked. Ignored in post mode. A run drops at most 250 posts for free (plus 10 per saved post); then it stops reading listings.
proxy (type: object):
Reddit blocks datacenter IPs, so residential Apify Proxy (US) is the default. Change only if you have your own residential proxies.
Actor input object example
{
  "mode": "subreddit",
  "subreddits": [
    "apify"
  ],
  "maxPosts": 10,
  "maxCommentsPerPost": 0,
  "sort": "new",
  "timeFilter": "all",
  "commentSort": "top",
  "proxy": {
    "useApifyProxy": true,
    "apifyProxyGroups": [
      "RESIDENTIAL"
    ],
    "apifyProxyCountry": "US"
  }
}
Actor output Schema
posts (type: string):
All rows with post columns (title, score, numComments, linkUrl). Rows with type = post are posts.
comments (type: string):
All rows with comment columns (parentId, depth, score). Rows with type = comment are comments.
status (type: string):
All rows with status columns (status, message, errorCode). Rows with type = status are not_found, no_results or error rows; they are free.
runSummary (type: string):
Run status, reason, per-target results and request statistics.
API
You can run this Actor programmatically using our API. Below are code examples in JavaScript, Python, and CLI, as well as the OpenAPI specification and MCP server setup.
JavaScript example
import { ApifyClient } from 'apify-client';

// Initialize the ApifyClient with your Apify API token
// Replace the '<YOUR_API_TOKEN>' with your token
const client = new ApifyClient({
    token: '<YOUR_API_TOKEN>',
});

// Prepare Actor input
const input = {
    "mode": "subreddit",
    "subreddits": [
        "apify"
    ],
    "maxPosts": 10,
    "maxCommentsPerPost": 0,
    "proxy": {
        "useApifyProxy": true,
        "apifyProxyGroups": [
            "RESIDENTIAL"
        ],
        "apifyProxyCountry": "US"
    }
};

// Run the Actor and wait for it to finish
const run = await client.actor("cliqtomedia/reddit-scraper").call(input);

// Fetch and print Actor results from the run's dataset (if any)
console.log('Results from dataset');
console.log(`💾 Check your data here: https://console.apify.com/storage/datasets/${run.defaultDatasetId}`);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
items.forEach((item) => {
    console.dir(item);
});

// 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/js/docs
Python example
from apify_client import ApifyClient

# Initialize the ApifyClient with your Apify API token
# Replace '<YOUR_API_TOKEN>' with your token.
client = ApifyClient("<YOUR_API_TOKEN>")

# Prepare the Actor input
run_input = {
    "mode": "subreddit",
    "subreddits": ["apify"],
    "maxPosts": 10,
    "maxCommentsPerPost": 0,
    "proxy": {
        "useApifyProxy": True,
        "apifyProxyGroups": ["RESIDENTIAL"],
        "apifyProxyCountry": "US",
    },
}

# Run the Actor and wait for it to finish
run = client.actor("cliqtomedia/reddit-scraper").call(run_input=run_input)

# Fetch and print Actor results from the run's dataset (if there are any)
print(f"💾 Check your data here: https://console.apify.com/storage/datasets/{run.default_dataset_id}")
for item in client.dataset(run.default_dataset_id).iterate_items():
    print(item)

# 📚 Want to learn more 📖? Go to → https://docs.apify.com/api/client/python/docs/quick-start
CLI example
echo '{
  "mode": "subreddit",
  "subreddits": [
    "apify"
  ],
  "maxPosts": 10,
  "maxCommentsPerPost": 0,
  "proxy": {
    "useApifyProxy": true,
    "apifyProxyGroups": [
      "RESIDENTIAL"
    ],
    "apifyProxyCountry": "US"
  }
}' |
apify call cliqtomedia/reddit-scraper --silent --output-dataset
MCP server setup
{
    "mcpServers": {
        "apify": {
            "type": "http",
            "url": "https://mcp.apify.com/?tools=fetch-actor-details,cliqtomedia/reddit-scraper"
        }
    }
}
The hosted server signs you in with OAuth on first connect, so no API token belongs in this config. Clients without OAuth support can send an Authorization: Bearer <APIFY_API_TOKEN> header instead, using a token from API & Integrations in Apify Console (https://console.apify.com/settings/integrations).
OpenAPI specification
Download the OpenAPI definition: https://api.apify.com/v2/actors/oQzSN0AoB9ik2v6v3/builds/rNLeNoABEqenhGm3e/openapi.json