Playwright E2E MCP
Jalankan, debug, dan periksa tes end-to-end Playwright dari agen AI mana pun: hasil terstruktur dengan diagnostik kegagalan file:line, inspeksi DOM langsung, validasi selektor, perbedaan visual, dan diagnosis tes flaky.
Server MCP Terhosting
npx add-mcp 'https://playwright-e2e-mcp.vercel.app/api/mcp'Terpasang ke Claude Code, Codex, Cursor, dan lainnya
Dokumentasi
playwright-e2e-mcp



An MCP server that diagnoses and fixes failing Playwright tests. It is the layer that sits next to a browser-driving MCP: Playwright MCP gives an agent hands in the browser; this server gives it a test runner, a failure analyst and a verified fixer.
run-test ──▶ get-failure ──▶ suggest-fix (apply + re-run) ──▶ green
   │              │                 └─ refuses when the element is really gone (app bug)
   │              └─ DOM at failure, failed requests, console errors
   └─ background runs, progress ──▶ analyze-history (flaky / broken / regressed)
What it does that a browser-driving MCP or a raw npx playwright test does not:
- Structured runs. Stats plus each failure's
file:line, kind (assertion, timeout, dead dev server, syntax error, crash, full disk…) and a concrete fix hint. Long suites run in the background with live progress. - Diagnosis from the trace. The DOM at the moment of failure, the failed action, the 4xx/5xx requests and console errors, read from Playwright's own trace.
- Fixes that are proven, not guessed.
suggest-fixmatches a broken locator against the DOM at failure, swaps in a Playwright locator proven unique on the page (getByRole('button', { name: 'Proceed to checkout' })), re-runs the test and reverts the edit if it is still red. When nothing on the page plausibly matches, it says the element is missing and does not patch the test to hide a real bug. - Flakiness across runs. Every run is recorded locally;
analyze-historyseparates tests that flip (flaky) from ones that started failing (regressed) or always fail (broken), and groups failures that share one cause. - Pages behind a login. Every page tool accepts a Playwright
storageState, extra headers, and click/fill steps to reach a modal or a later step. - Small on the wire. In the benchmark, diagnosing and fixing one drifted locator cost about 5,300 tokens here against about 7,400 with Playwright MCP plus a shell, and the fix was applied and verified without the agent editing anything.
What it does not do
It does not drive an exploratory browsing session step by step, and it does not replace Playwright's own Test Agents (planner, generator, healer) inside VS Code. Use Playwright MCP for interactive browsing and this server for running, diagnosing and fixing the suite; they work side by side in the same client.
Demo
Hosted endpoint — what an initialize + tools/list round-trip against
https://playwright-e2e-mcp.vercel.app/api/mcp returns for a client that sends the
bearer token (without one, only list-tests and get-failure are listed):
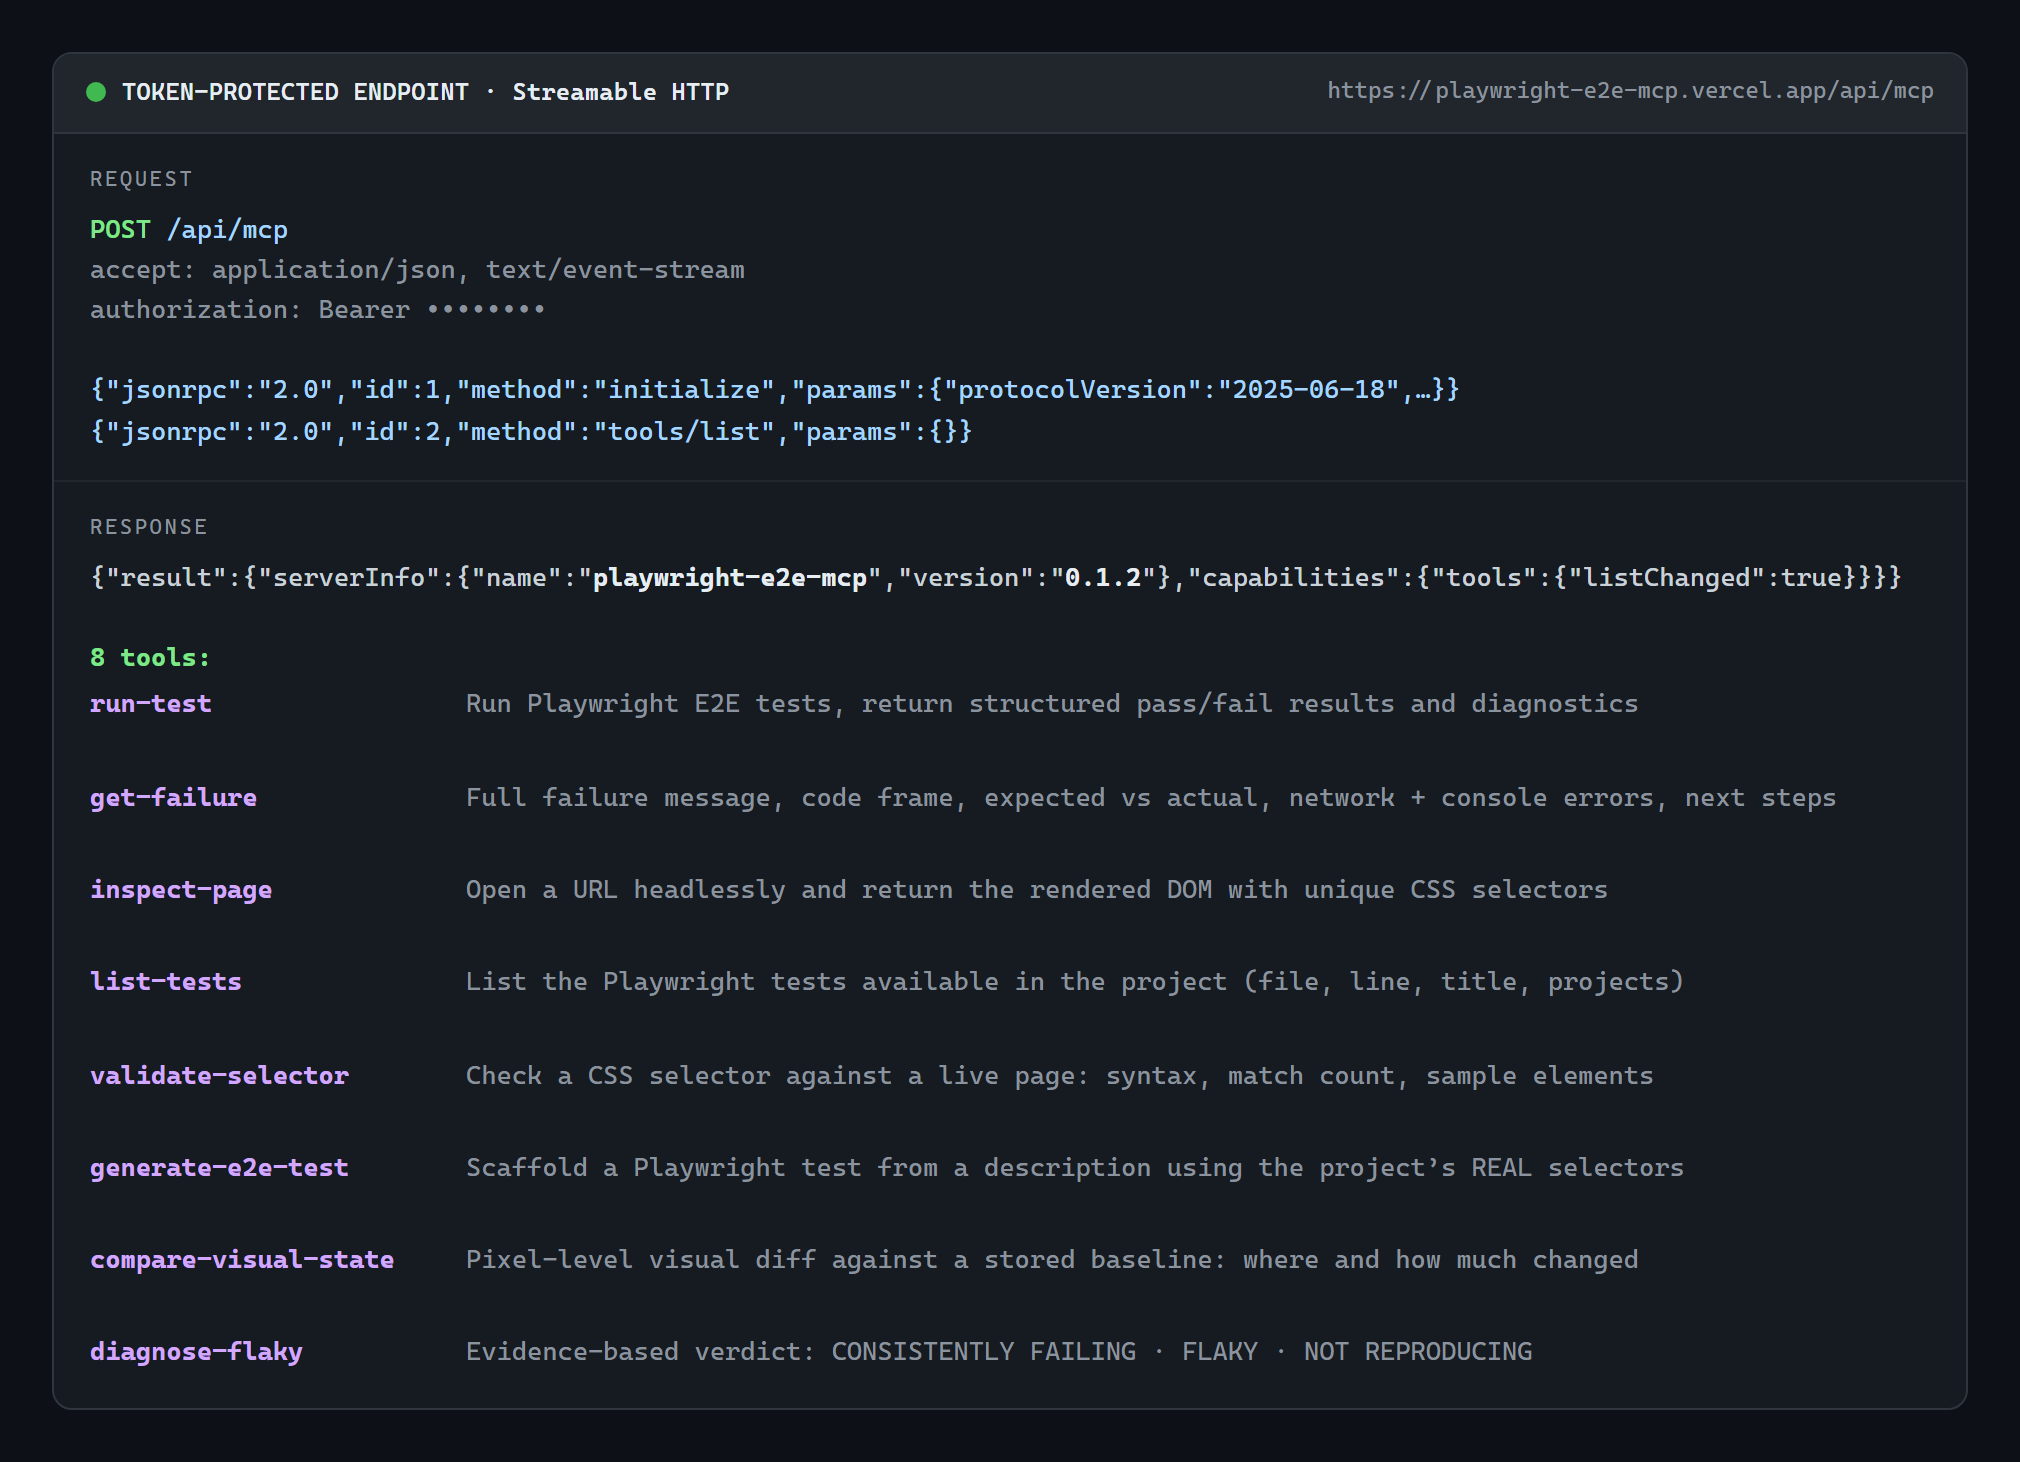
A real test run — run-test served over stdio by npx -y playwright-e2e-mcp
against the bundled examples/sample-test.spec.ts (actual output, unedited):
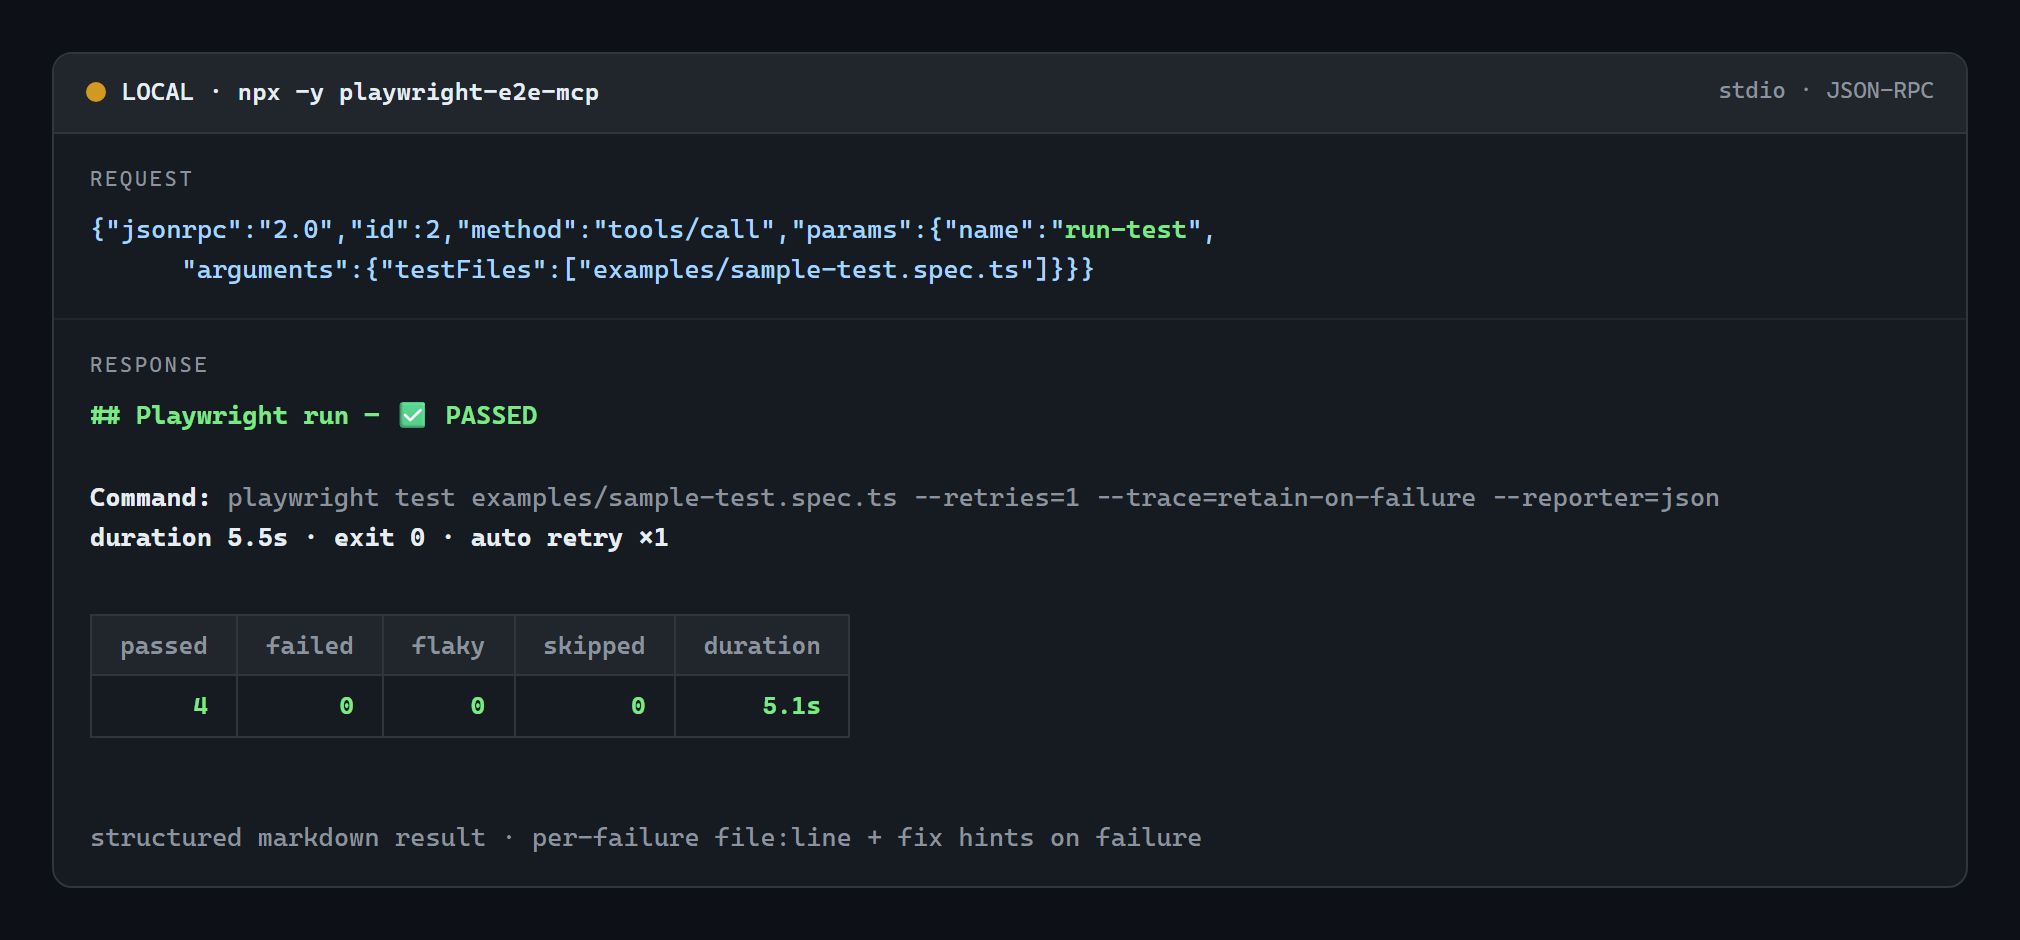
Images are rendered with node scripts/gen-demo-images.mjs: the run-test card is real
captured output; the endpoint card is an illustration of the authenticated listing.
Install
Works with Claude Desktop, Claude Code, Cursor, Windsurf, Codex, Gemini CLI, Freebuff and every other MCP client — pick whichever route fits:
| Route | How |
|---|---|
| npm (canonical, fastest) | npx -y playwright-e2e-mcp |
| MCP Registry (registry-aware clients discover it automatically) | io.github.trajectiq-ai/E2E — listing |
| Any client, no npm account needed | npx -y github:trajectiq-ai/E2E#v0.2.2 (pin a release tag) |
| Claude Desktop, zero Node setup | double-click the .mcpb extension |
| Remote-only clients (ChatGPT connectors) | https://playwright-e2e-mcp.vercel.app/api/mcp |
One line for the common clients:
claude mcp add playwright-e2e -- npx -y playwright-e2e-mcp
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","playwright-e2e-mcp"]}'
Details and per-client config: Installation · MCP client configuration.
Tools
| Tool | Purpose |
|---|---|
run-test | Run Playwright tests and return stats, failures, diagnostics and hints; reports progress, and background: true returns a run id for long suites |
get-run-status | Progress or final result of a background run; can wait for it or cancel it |
get-failure | Deep analysis of one failure: stack, expected/actual, DOM snapshot at failure (from the Playwright trace), failed requests, console errors, next steps |
suggest-fix | Patch a failure: a drifted locator is replaced with one proven unique on the DOM at failure, changed copy gets the new expected text; apply: true writes it, re-runs the test and reverts if still red |
inspect-page | Open a URL headlessly (optionally signed in, after steps) and return elements with verified Playwright locators, CSS selectors, visibility, text and console output |
list-tests | List available tests (file, line, full title, projects) with filtering |
validate-selector | Check a CSS selector, Playwright selector or locator expression against a live page: validity, match count, and a sturdier verified locator for each match |
generate-e2e-test | Scaffold a Playwright test from a description using the project's real selectors and verified locators from the live page |
compare-visual-state | Visual regression: screenshot before/after a change and report what moved and how colors shifted |
diagnose-flaky | Run a failing test 2–10 times with retries disabled and return an evidence verdict: CONSISTENTLY FAILING, FLAKY or NOT REPRODUCING |
analyze-history | Rank flaky, regressed and broken tests from the local run history, group failures by cause, or show one test's timeline |
Two prompts package the main workflows for clients that show them as slash commands:
fix-failing-test (optional test) and triage-flaky-tests.
Page state: signed-in pages, headers and steps
inspect-page, validate-selector and compare-visual-state accept the same page-state
arguments (suggest-fix accepts storageState and headers for a live url):
| Argument | Type | Description |
|---|---|---|
storageState | string | Path inside the project to a Playwright storageState JSON (cookies + localStorage), e.g. playwright/.auth/user.json from your setup project. Defaults to PW_MCP_STORAGE_STATE |
headers | object | Extra HTTP headers for every request, e.g. { "Authorization": "Bearer …" } |
actions | array | Up to 20 steps run after load: { "type": "click" | "dblclick" | "hover" | "fill" | "press" | "check" | "uncheck" | "select" | "wait" | "goto", "locator"?, "value"?, "url"?, "ms"? }. Locators use Playwright syntax, e.g. getByRole('button', { name: 'Open settings' }) |
viewport | object | { "width": 390, "height": 844 } (default 1280×720) |
A failing step reports which one failed and how many ran. When the page lands on a login
screen, the response says so and suggests storageState.
run-test
| Argument | Type | Description |
|---|---|---|
projectRoot | string | Project directory inside the configured root (default: server working directory) |
testFiles | string[] | Files/directories relative to the root; file:line supported. Omit to run everything |
grep | string | Only run tests whose title matches this regex |
browser | chromium | firefox | webkit | Playwright project to run (matched against config project names) |
headed | boolean | Visible browser window |
timeoutMs | number | Hard wall-clock limit for the run (default 120000); the whole process tree is killed past it and partial results are returned |
testTimeoutMs | number | Per-test timeout passed to Playwright |
workers / retries | number | Passed through to Playwright |
config | string | playwright.config path or 1-based index when the project has several |
retryOnFailure | boolean | Auto-retry failures once before reporting them (default true; ignored when retries is set) |
lastFailed | boolean | Only re-run tests that failed in the previous run (Playwright --last-failed) — the fast fix → re-run loop |
args | string[] | Extra Playwright flags from an allowlist (--repeat-each=N, --max-failures=N, --update-snapshots, --shard=1/3, --trace=on, …); values go after = and are checked, and flags that take a path, such as --config or --output, are rejected |
background | boolean | Return a run id at once; poll get-run-status for progress and the result |
Progress: clients that send a progress token get a notification as each test finishes
(3/12 tests done, 1 failed). Every run is appended to the local history used by
analyze-history.
Flakiness handling: by default the server injects --retries=1 (unless the config
already sets retries), so a test that passes on the retry is reported as flaky,
not failed. Traces are captured automatically (--trace=retain-on-failure) so
get-failure can show the DOM at the moment of failure.
Example result:
## Playwright run — ❌ FAILED

**Command:** `playwright test --config playwright.config.ts tests/checkout.spec.ts --reporter=json`
**duration 4.2s · exit 1 · config `playwright.config.ts`**

| passed | failed | flaky | skipped | duration |
| ---: | ---: | ---: | ---: | ---: |
| 0 | 1 | 0 | 0 | 1.1s |

### ❌ 1 failing test(s)

### 1 of 1. checkout.spec.ts › pays with card
**File:** `checkout.spec.ts:5`  |  **failed · server-unreachable**

### ⚠️ SERVER_NOT_RUNNING
Your app (dev server) does not appear to be reachable. Start it in another terminal
(e.g. npm run dev / npm start), keep it running, then retry — or configure `webServer`
in playwright.config.* so Playwright starts it automatically.
get-failure
| Argument | Type | Description |
|---|---|---|
index | number | 1-based failure index from the last run (default 1) |
projectRoot | string | Only used when re-reading the stored report |
Returns the message/code frame, expected vs actual, stack, failure kind with a
diagnosis, the test's console output, the DOM snapshot from the Playwright trace
(plus the failed action, its selector, and the action log leading up to it),
the network requests that failed (4xx/5xx, dead endpoints, no-response — with
method, URL, status and resource type), the console errors/warnings the page
logged before the failure, and
numbered next steps (re-run this single test by file:line, headed/debug mode,
validate-selector when the message mentions a locator, …).
inspect-page
| Argument | Type | Description |
|---|---|---|
url | string | Full http(s) URL to open (required) |
view | elements | locators | locators returns a compact map of interactive elements with verified locators (cheapest); elements (default) the DOM inventory |
projectRoot | string | Project whose Playwright launches the browser |
selector | string | Inspect matches of this selector instead of the whole DOM |
waitFor | string | Wait for a selector (CSS or text=…) before inspecting |
waitUntil | load | domcontentloaded | networkidle | Navigation wait condition |
includeHtml | boolean | Include the rendered HTML (capped) |
maxHtmlChars | number | HTML cap, default 20000 |
timeoutMs | number | Overall limit, default 45000 |
storageState / headers / actions / viewport | — | Page state |
Each element comes with Playwright locators that were checked on the page to resolve to exactly that element, best first (role + accessible name, test id, label, placeholder, text, then CSS), plus its unique CSS selector, visibility, box and text. Console messages are captured, errors first. A locator map looks like:
1. `getByRole('button', { name: 'Proceed to checkout' })` — button "Proceed to checkout" · also `getByTestId('checkout-btn')`
2. `getByLabel('Search')` — searchbox "Search"
list-tests
| Argument | Type | Description |
|---|---|---|
projectRoot | string | Project directory |
config | string | Config path or 1-based index |
testDir | string | Restrict scanning to a directory (must stay inside the project) |
filter | string | Case-insensitive substring filter on file › title |
limit | number | Max tests returned, default 500 |
Uses playwright test --list when Playwright works, and falls back to a source scan
(keeping the reason) when the install or a spec file is broken.
validate-selector
| Argument | Type | Description |
|---|---|---|
url | string | Live page to test against (required) |
selector | string | CSS, a Playwright selector (text=, role=, >>) or a locator expression such as getByRole('button', { name: 'Save' }).first() (required) |
projectRoot | string | Project whose Playwright launches the browser |
timeoutMs | number | Overall limit, default 45000 |
storageState / headers / actions / viewport | — | Page state |
Locator expressions are parsed into a whitelisted call chain (getByRole, getByText,
getByLabel, getByPlaceholder, getByAltText, getByTitle, getByTestId, locator,
first, last, nth, filter) and are never evaluated as code.
Verdicts: ✅ VALID — N matches with a sample of matches and a unique locator for each,
a strict-mode warning when more than one element matches, a hint when a CSS selector is
brittle (:nth-child, long descendant chains, XPath), ✅ VALID — 0 matches with debugging
advice, or ❌ INVALID with the parse error.
generate-e2e-test
| Argument | Type | Description |
|---|---|---|
description | string | What the test should cover (required) |
pageUrl | string | Page the test starts on (default: baseURL / webServer.url from config) |
testDir / file | string | Where to write the spec (default: detected testDir + generated/<slug>.spec.ts); file must end in .spec.* or .test.* |
write | boolean | Write the file to disk (default true) |
overwrite | boolean | Replace an existing spec at the target path; only specs this tool generated can be replaced |
liveInspect | boolean | Cross-check selectors against the live page (default on when a URL is known) |
projectRoot / config | string | As with the other tools |
Reads the agent's recent changes (git status, falling back to git diff HEAD~1,
then recent mtimes), extracts the locators those files actually declare
(data-testid, getByRole, aria-label, placeholder, id, name, element text),
ranks verified-live selectors first, writes a spec built from them, and reports each
selector with its source file:line. When the source has no usable selectors, it uses the
verified locators from the live page that best match the description.
compare-visual-state
| Argument | Type | Description |
|---|---|---|
url | string | Page to capture (required) |
name | string | Baseline id, e.g. checkout-page (letters, digits, . _ -) |
action | compare | baseline | compare (default) diffs; baseline re-captures the reference |
selector | string | Capture just this element |
fullPage | boolean | Capture the full scrollable page |
tolerance | number | Percent of pixels that may differ (default 0.1) |
pixelThreshold | number | Per-pixel channel delta considered different (default 60) |
waitUntil / waitFor / timeoutMs | — | As with inspect-page |
storageState / headers / actions / viewport | — | Page state |
The first call saves a baseline under .pw-mcp/visual/ (add that to .gitignore, or
commit it for CI comparisons). Later calls report changed-pixel counts, merged
regions ((x, y) 120×40 — 1,200 px), the average color shift ("blue → red"),
and write a red-highlighted diff image for review.
diagnose-flaky
| Argument | Type | Description |
|---|---|---|
testFiles | string[] | Tests to diagnose (file:line supported). Defaults to the tests that failed in the most recent run |
runs | number | Times to run them, 2–10 (default 3) |
browser / headed / workers / config | — | As with run-test |
timeoutMs | number | Hard wall-clock limit per run (default 120000) |
projectRoot | string | Project directory |
Every run executes with --retries=0 and auto-retry disabled, so each result is
honest evidence. The response contains a per-run table (status, duration, first
failure), the count of distinct normalized error signatures, and one of:
- ❌ CONSISTENTLY FAILING — failed every run (same error → reproducible bug, different errors → still broken, just noisy). Fix it; it is not flaky.
- ⚠️ FLAKY — some runs passed. Includes
N of Mcounts and whether the failures share one signature (real intermittent bug) or vary (timing/environment instability). - ✅ NOT REPRODUCING — passed every re-run; the original failure was one-off.
The last run is stored, so get-failure can analyze it immediately afterwards.
suggest-fix
| Argument | Type | Description |
|---|---|---|
index | number | 1-based failure index from the last run (default 1) |
apply | boolean | Write the fix into the spec (default false: return the diff only) |
verify | boolean | After applying, re-run the test and revert the file if it still fails (default true) |
allowExpectationUpdate | boolean | Allow applying a changed expected text/value (default false, since it can hide a real regression) |
url | string | Heal against this live page instead of the DOM snapshot in the failure trace |
storageState / headers | — | For url, as in Page state |
config / timeoutMs / projectRoot | — | As with run-test |
Two kinds of fix:
- Locator drift. The broken locator is read from the error, its words are matched
(with synonyms such as btn → button, checkout → proceed to checkout) against every
element in the DOM at failure, and the best match's verified-unique locator replaces it.
Confidence is
highwhen the match is clear,mediumotherwise. - Changed copy. For
toHaveText,toContainText,toHaveValue,toHaveTitle,toHaveURLandtoHaveAttribute, it proposes the value the page actually showed. It is only applied withallowExpectationUpdate: true.
The response is a unified diff. With apply: true the file is written only if it has not
changed since the failure, the single test is re-run (same project, no retries), and the
edit is reverted when it is still red. If nothing on the page shares the locator's
distinctive words, it refuses and reports that the element is most likely missing.
get-run-status
| Argument | Type | Description |
|---|---|---|
runId | string | Run id from run-test with background: true (default: the most recent run) |
waitSeconds | number | Wait up to this long (max 55) for the run to finish |
cancel | boolean | Stop the run and kill its browsers |
While running it reports tests done / total and failures so far; once finished it returns
the full run-test result, which also becomes the last run for get-failure and
suggest-fix. The 20 most recent runs are kept in memory.
analyze-history
| Argument | Type | Description |
|---|---|---|
view | flaky | patterns | test | flaky (default) ranks unstable tests; patterns groups failures by kind and normalized error; test shows one test's timeline |
test | string | Substring of a test's file or title (filters every view) |
lastRuns | number | How many recent runs to analyze (default 30) |
limit | number | Max rows (default 15) |
Every run-test, diagnose-flaky and suggest-fix run appends a line to
<project>/.playwright-e2e-mcp/history.jsonl (the folder carries its own .gitignore;
nothing leaves the machine; PW_MCP_HISTORY=0 turns it off). The flaky view separates
tests that flip between pass and fail, tests that started failing and stayed red
(regressed), and tests that failed every run (broken), each with a PFFP~ timeline.
Installation
Requirements:
- Node.js ≥ 20 (the server is built on MCP SDK v2 — the
2026-07-28spec line) - A project with
@playwright/testinstalled and browsers available (npx playwright install chromium)
No npm account needed — install straight from GitHub (the prepare script
builds dist/ automatically on install). Pin a release tag: an unpinned
github:trajectiq-ai/E2E runs whatever is on the default branch at that moment.
npx -y github:trajectiq-ai/E2E#v0.2.2
npm install -D github:trajectiq-ai/E2E#v0.2.2 @playwright/test   # or as a project dependency
npx playwright install chromium
Or grab the packaged tarball from the repo's GitHub Releases page and install it locally:
npm install -D https://github.com/trajectiq-ai/E2E/releases/download/v0.2.2/playwright-e2e-mcp-0.2.2.tgz
Listed in the official MCP Registry as
io.github.trajectiq-ai/E2E — registry-aware clients discover it there, and every
v* release tag republishes the entry from CI via server.json.
MCP client configuration
Claude Code / generic (project-scoped):
{
  "mcpServers": {
    "playwright-e2e": {
      "command": "npx",
      "args": ["-y", "github:trajectiq-ai/E2E#v0.2.2"],
      "env": { "PW_MCP_PROJECT_ROOT": "/absolute/path/to/your/project" }
    }
  }
}
Claude Desktop / Cursor / Windsurf: add the same block to their MCP config file.
The server uses its working directory as the project root; set PW_MCP_PROJECT_ROOT
when the client launches it somewhere else (e.g. your home directory).
Codex / VS Code / Copilot CLIs:
codex mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.2.2
code --add-mcp '{"name":"playwright-e2e","command":"npx","args":["-y","github:trajectiq-ai/E2E#v0.2.2"]}'
Codex's defaults fight this server: the first launch clones the repo and runs
tsc (measured 30 s on a cold npx cache, against a 10 s
startup_timeout_sec default), and a Playwright run with retries beats the 60 s
tool_timeout_sec default. Raise both in ~/.codex/config.toml:
[mcp_servers.playwright-e2e]
command = "npx"
args = ["-y", "github:trajectiq-ai/E2E#v0.2.2"]
startup_timeout_sec = 60
tool_timeout_sec = 600
Claude Desktop (one-click): download and double-click the .mcpb Desktop
Extension attached to the latest release —
the bundle ships its own dependencies, so no Node setup is required. On install it
asks you to pick your project root (required, no default: choose the project
folder, not your home directory) and wires it
into PW_MCP_PROJECT_ROOT, so the tools point at a real project from the first call.
Claude Code:
claude mcp add playwright-e2e -- npx -y github:trajectiq-ai/E2E#v0.2.2
Gemini CLI / Qwen Code: paste the mcpServers block above into
.gemini/settings.json (Qwen Code: .qwen/settings.json) — both speak the same
MCP settings format.
Freebuff / Codebuff (project-scoped): this repo ships a committed
.agents/mcp.json, so opening the checkout in Freebuff
attaches the server workspace-wide — no global config needed. Your own projects
can do the same: drop an mcp.json with the block above into their .agents/
directory. Freebuff asks you to trust a repository's .agents/ on first run.
All tools ship MCP tool annotations (readOnlyHint, destructiveHint,
idempotentHint, openWorldHint), so clients can show accurate safety prompts
before running anything.
From a local checkout:
{
  "mcpServers": {
    "playwright-e2e": {
      "command": "node",
      "args": ["/path/to/playwright-e2e-mcp/dist/index.js"],
      "env": { "PW_MCP_PROJECT_ROOT": "/path/to/your/project" }
    }
  }
}
Hosted endpoint (ChatGPT & remote clients)
Some clients — ChatGPT custom connectors especially — only accept remote
HTTPS MCP servers and refuse to spawn a local npx process. This repo ships a
Streamable HTTP bridge for exactly that case:
| Endpoint | https://playwright-e2e-mcp.vercel.app/api/mcp |
| Transport | MCP Streamable HTTP (POST JSON in, JSON or SSE out) |
| Auth | bearer token (PW_MCP_HTTP_TOKEN). The deployment at this URL requires it; a bridge started without the variable serves only the read-only tools |
| Source | api/mcp.ts → src/http.ts |
The bridge runs the same createServer() as the stdio transport; the SDK
serves every request with a fresh server instance, which is what a serverless
function wants. test/http-bridge.test.mjs drives the real Node adapter over
node:http so a broken bridge fails in CI, not in ChatGPT.
This deployment is token-protected. https://playwright-e2e-mcp.vercel.app
has PW_MCP_HTTP_TOKEN set, so a request without Authorization: Bearer <token>
— including a ChatGPT connector created with authentication None — gets
401 {"error":"unauthorized"}. Ask the operator for the token, or run your own
bridge (below).
Open vs. token-protected. With PW_MCP_HTTP_TOKEN set (at least 16
characters; use a random value) every tool is served to clients that send
Authorization: Bearer <token>, and every other request gets 401. Without that
variable anyone who reaches the URL can call the bridge, so it degrades to
list-tests and get-failure in restricted mode: list-tests scans sources
instead of running playwright test --list (which would execute the project's
config), callers cannot pick another projectRoot, and nothing spawns a process,
drives a browser or writes a file. Child processes started over HTTP get only an
allowlisted environment. PW_MCP_ALLOWED_HOSTS (comma separated, * for any)
limits the accepted Host header; without a token and without that variable,
only localhost names and the deployment's own Vercel hostnames are accepted
(DNS-rebinding protection).
Add it to ChatGPT: Settings → Connectors → turn on Advanced → Developer
mode → Create custom connector → paste the endpoint above. Authentication
None only works against a bridge with no token (read-only tools), so for this
deployment choose the connector's API key authentication and send
Authorization: Bearer <token> — or point the connector at your own deployment
with PW_MCP_HTTP_TOKEN unset.
To self-host the open, read-only variant, deploy this repo with
PW_MCP_HTTP_TOKEN unset; nothing else changes.
Codex can also take the remote transport instead of spawning npx, if you'd
rather not ship Playwright to every machine. Point it at the token through an
environment variable so the secret stays out of the config file:
export PW_MCP_HTTP_TOKEN=…   # ask the operator for the value
codex mcp add playwright-e2e-remote --url https://playwright-e2e-mcp.vercel.app/api/mcp \
  --bearer-token-env-var PW_MCP_HTTP_TOKEN
What to expect: list-tests works and reports the specs bundled with the
deployment. Even with a token, tools that spawn a browser (run-test,
inspect-page, validate-selector, diagnose-flaky, …) cannot download
Chromium in a serverless function, so they return their normal NO_PLAYWRIGHT
hint. Use the stdio install for real runs; the hosted endpoint is for discovery
and for clients that cannot run local processes.
# verify the handshake without any client (the live deployment needs the token;
# drop the authorization header and it answers 401 instead)
curl -X POST https://playwright-e2e-mcp.vercel.app/api/mcp \
  -H 'content-type: application/json' \
  -H 'accept: application/json, text/event-stream' \
  -H "authorization: Bearer $PW_MCP_HTTP_TOKEN" \
  -d '{"jsonrpc":"2.0","id":1,"method":"initialize","params":{"protocolVersion":"2025-06-18","capabilities":{},"clientInfo":{"name":"curl","version":"1.0"}}}'
Redeploy after a change: merge to main. Vercel's Git integration deploys
every push, so there is no token to manage and no CLI step — watch the
Vercel commit status for the deployment result.
Configuration
| Environment variable | Default | Purpose |
|---|---|---|
PW_MCP_PROJECT_ROOT | server cwd | Default project root for every tool |
PW_MCP_STORAGE_STATE | — | Default storageState file (inside the project) for the page tools |
PW_MCP_HISTORY | on | 0 stops recording runs to .playwright-e2e-mcp/history.jsonl |
PW_MCP_ALLOWED_ROOTS | — | Extra directories a caller may pass as projectRoot (:-separated, ; on Windows). Anything outside these and the default root is rejected |
PW_MCP_HTTP_TOKEN | — | HTTP bridge only: bearer token (16+ characters) that unlocks all tools (see above) |
PW_MCP_ALLOWED_HOSTS | localhost + Vercel hostnames when there is no token | HTTP bridge only: comma-separated Host allowlist; * accepts any |
PW_MCP_PASSTHROUGH_ENV | — | HTTP bridge only: comma-separated extra variables passed to test runs (e.g. BASE_URL) |
PW_MCP_MAX_CHILDREN | 4 | HTTP bridge only: how many test runs and browser probes may run at once |
PW_MCP_BLOCK_PRIVATE_URLS | off (on for the HTTP bridge) | 1 makes the URL tools refuse loopback, private-network and cloud-metadata addresses, including redirects and subresources |
LOG_LEVEL / MCP_LOG_LEVEL | info | debug | info | warn | error | silent; LOG_LEVEL wins when both are set |
LOG_FORMAT / MCP_LOG_FORMAT | text | text, or json (also ndjson) for one structured JSON object per line — ready for a log ingester |
Logs always go to stderr — stdout is reserved for the MCP protocol. Unrecognized values
fall back to the default, so a typo in LOG_LEVEL logs at info and one in LOG_FORMAT
logs as text rather than silencing the server. With LOG_FORMAT=json each line is a single
object (time, level, message plus context):
{"time":"2026-10-07T08:00:00.000Z","level":"info","message":"server ready","name":"playwright-e2e-mcp"}
Typical workflow
run-test{ "testFiles": ["tests/checkout.spec.ts"] }, or{ "background": true }for a long suite andget-run-status{ "waitSeconds": 30 }until it finishes.get-failure{ "index": 1 }to read the code frame, expected/actual, the DOM snapshot at failure, the failed network requests and the page's console errors.suggest-fix{ "index": 1 }for a locator or copy change: review the diff, then{ "index": 1, "apply": true }to write it and verify with a re-run. If it reports the element is missing, fix the app, not the test.- For anything it cannot patch:
inspect-page{ "url": "…", "view": "locators" }(addstorageStateoractionsto reach the right screen), thenvalidate-selectorto prove the new locator before editing. - If a failure looks intermittent:
diagnose-flaky{ "runs": 3 }for fresh evidence, andanalyze-historyto see how the test behaved across earlier runs. - After changing CSS or components:
compare-visual-state{ "url": "…", "name": "checkout" }. - Re-run only what failed with
run-test{ "lastFailed": true }until green.
To write a new test, start with generate-e2e-test { "description": "checkout with a saved card" }.
Benchmark
bench/token-benchmark.mjs breaks a checkout button's test id
on a storefront page and fixes it two ways: with this server (run-test → suggest-fix →
apply) and with Playwright MCP plus a shell (playwright test, browser_navigate +
browser_snapshot, edit, re-run). Latest result (full output):
| Step | playwright-e2e-mcp | Playwright MCP + shell |
|---|---|---|
| Tool definitions (sent with every request) | 4,565 | 4,726 |
| Run the failing test | 246 | 325 |
| Find the element / propose the fix | 260 | 2,286 |
| Apply + verify (re-run) | 257 | 34 |
| Total for one fix | 5,328 | 7,371 |
Tokens are characters ÷ 4. The Playwright MCP route is a lower bound: it assumes the agent picks the right locator from the snapshot on the first try, which the server does for it here.
Edge cases handled
| Situation | Behaviour |
|---|---|
| No Playwright installed | NO_PLAYWRIGHT error with the exact install commands for your package manager |
| Dev server not running | Failure classified server-unreachable / SERVER_NOT_RUNNING with a "start your dev server" hint (and webServer advice) |
Test exceeds timeoutMs | Process group is killed (SIGINT→SIGKILL on POSIX, taskkill /T /F on Windows) and partial results are returned |
| Browser crashes | Classified browser-crash with retry / reinstall guidance |
| Windows backslashes | All paths normalized lexically (C:\a\..\b → C:/b); unit-tested on both platforms |
| Flaky tests | Failing tests are automatically retried once (--retries=1) before being reported; passes surface as flaky with a stability warning; diagnose-flaky decides flaky-vs-broken with multi-run evidence |
| Trace/DOM context | --trace=retain-on-failure is passed automatically, so get-failure can show the exact DOM at the moment of failure — plus the failed network requests (*.network logs) and console errors from the same trace |
| Slow re-runs after a fix | run-test with lastFailed: true re-runs only the tests that failed last time (--last-failed) |
Several playwright.config files | Returns a numbered menu (MULTIPLE_CONFIGS); pick with config: "2" or a path |
| Syntax error in a spec | SYNTAX_ERROR with file:line; nothing crashes; list-tests falls back to a source scan |
| MCP client disconnects | Per-request AbortSignal kills the run; stdin end triggers shutdown, and every tracked child tree is force-killed (killActiveChildren) |
| Disk full | ENOSPC detected → DISK_FULL with a "free space" hint; logging never throws |
| Malicious paths | ../../etc/passwd, absolute paths outside the root, a projectRoot outside the allowed roots, symlinks that leave the root, URLs and null bytes are rejected with INVALID_PATH; extra CLI args must be allowlisted Playwright flags |
Security notes
- No shell: Playwright is spawned as
node <playwright/cli.js> …with an argument array — no command interpolation. Extraargsare limited to an allowlist of Playwright flags, each with a checked value (--flag=value), so a caller cannot swap in another--configor--outputor hand git an option through--only-changed. Paths with a segment starting with-are rejected, so a test file name cannot be read as a flag. - Path sandbox: user paths must stay inside the project root, checked lexically
and again with symlinks resolved. A caller-supplied
projectRootmust sit insidePW_MCP_PROJECT_ROOT(or aPW_MCP_ALLOWED_ROOTSentry). - Generated code:
generate-e2e-testonly writes*.spec.*/*.test.*files, only overwrites specs whose header it wrote itself, never writes through a symlink, and escapes every value it puts into strings or comments. - HTTP bridge: read-only tools unless
PW_MCP_HTTP_TOKENis set; child processes started over HTTP get only an allowlisted environment (PATH,HOME, temp dirs, locale,CI,PLAYWRIGHT_*,npm_config_*without embedded credentials, plus anything inPW_MCP_PASSTHROUGH_ENV), at mostPW_MCP_MAX_CHILDRENrun at once (a disconnected client frees its slot immediately), and internal error messages are not returned to clients. The allowlist only covers the child's own environment: test code runs as the same OS user, so on Linux it could still read the server's startup environment from/proc. That is why only token holders can run project code; keep other secrets out of the bridge's environment, or run it under a separate user. - SSRF guard: on the HTTP bridge (or with
PW_MCP_BLOCK_PRIVATE_URLS=1) the URL tools refuse hosts that resolve to loopback, private, link-local/metadata or reserved addresses, and route the browser through a local proxy that applies the same check to every redirect hop and subresource; IPv6 forms that embed an IPv4 address (mapped, NAT64, 6to4, Teredo) are blocked too, and WebRTC UDP is disabled so a page cannot reach the network around the proxy. It is off for stdio by default because openinghttp://localhostdev servers is what these tools are for. - Cleanup: temp report/script files are written to the OS temp dir and removed; child processes are tracked and killed on shutdown. Trace decompression has one size budget per archive, and PNGs are capped at 16,384 px per side and 50 M pixels.
Development
src/
├── index.ts            # bin entry point (--version/--help, main-module guard)
├── server.ts           # McpServer setup, tool registration, shutdown handling
├── tools/              # the eleven tools, the probe script + shared plumbing
├── prompts.ts          # fix-failing-test, triage-flaky-tests
├── utils/              # playwright-runner, report-parser, project-detector, path-utils,
│                       # logger, trace-reader (trace.zip → DOM/network/console),
│                       # image-diff (PNG codec + pixel diff), change-analyzer,
│                       # locator-expr, run-history, run-registry
└── types/              # shared interfaces and the ErrorKind taxonomy
Built on @modelcontextprotocol/server v2 (the 2026-07-28 MCP spec line) with
Zod v4 standard schemas; every tool declares spec tool annotations.
npm install
npm run build   # tsc → dist/ (zero errors)
npm test        # build + test/run-tests.mjs (unit tests, any Node ≥20)
npm run e2e     # build + e2e/run.mjs: live MCP ↔ Playwright integration suite
npm run mcpb    # build + bundle dist/ into playwright-e2e-mcp-<version>.mcpb (+ .sha256)
npm run mcpb:smoke   # ...then install that bundle in a temp dir, launch it and assert the handshake
npm run mcpb:sign    # ...then sign it with MCPB_CERT/MCPB_KEY → <version>.signed.mcpb
npm run skill:zip    # just the archive: dist-skill/playwright-e2e-mcp.zip
npm run skill:package # the uploadable folder: ../agensi-skill-<version>/ (skill copy, README, zip)
npm run skill:check  # build, then fail if a packaged copy has drifted from skill/
Tests cover the report parser (sample Playwright JSON, trace attachments), path utils
(Windows and macOS paths, sandboxing), the project detector (temp-dir fixtures: config
discovery, multiple configs, missing install, test-file scanning), the shared tool
helpers, the trace reader (synthetic trace.zip: error, failed action, DOM snapshot,
*.network failed-request parsing, console error/warning events), the image diff
(PNG round-trip, regions, color shift, dimension changes), the change analyzer
(selector extraction, git + mtime paths), the flaky verdict logic
(failure signatures, CONSISTENTLY FAILING / FLAKY / NOT REPRODUCING / NO TESTS RAN),
the HTTP bridge (token, restricted mode, Host allowlist), the security
regressions (sandbox escapes, argument smuggling, symlink writes, code injection,
SSRF ranges, env scrubbing, decode limits), the .mcpb manifest, the .mcpb zip
extractor, the skill package (byte-identical rebuilds, a CRLF checkout hashing the
same, refusal of junk/binary/symlinks, and drift detection between skill/ and a
packaged copy), and the MCP config files.
Integration suite (npm run e2e)
Unit tests prove the logic; the integration suite proves the loop. It boots the real
server over stdio against a live fixture app and a Playwright project under
e2e/fixture/, then drives it exactly like an MCP client and asserts ~40 behaviours
that only appear end-to-end:
- initialize handshake, 11 tools, 2 prompts, spec tool annotations and object input schemas,
- verified locators, locator validation, signed-in pages (
storageState) and page steps, - background runs with progress, run history views, and
suggest-fixhealing a drifted locator and verifying it with a re-run (and refusing when the element is missing), - live DOM inspection, CSS selector validation (matches, zero matches, engine syntax, parse errors), dead-server detection,
- visual regression: baseline → unchanged compare →
blue → reddiff detection, run-testpass/fail/lastFailedstats and meta lines,get-failuretrace diagnostics: DOM at failure, the 404 network request, theconsole.errormessage, diagnosis and next steps,- auto-retry turning a first-run failure into
PASSED (1 flaky), diagnose-flakyverdict FLAKY (2 of 3 runs) with retries disabled,generate-e2e-testwriting its scaffold, plus error paths (missing test path, unknown tool, unreachable server).
First run needs the browser once: npx playwright install chromium.
CI runs the suite on Ubuntu and Windows (see .github/workflows/ci.yml).
Signing the bundle
MCPB_CERT=~/signing/cert.pem MCPB_KEY=~/signing/key.pem npm run mcpb:sign
Signing appends a PKCS#7 signature block to the bundle, so the signed file is
the reproducible bundle plus that block. That ordering is the point: the bytes
CI proved identical across platforms stay inside the signed file, and
mcpb unsign returns them exactly. scripts/sign-mcpb.mjs asserts that round
trip on every run and deletes its output if it fails, which is what keeps
<version>.signed.mcpb tied to <version>.mcpb.
The private key is read from a path you pass in (--cert/--key or
MCPB_CERT/MCPB_KEY) and never from the repository — keep it outside version
control, and back it up: the same key across releases is what makes the signer
recognisable.
What signing does and does not buy you is decided by the certificate, not by
this script. mcpb verify and mcpb info accept a signature only when the
certificate chains to something in the OS trust store, so with a self-signed
certificate a host still reports Not signed — the signature is real
integrity and key continuity, verifiable by the fingerprint the script prints,
but not third-party identity. A certificate issued by a public CA, or an
internal one installed on your machines, is what makes hosts report it as
signed.
Assembling a release
npm run mcpb && npm pack                  # the bundle, then the npm tarball
npm run release:assemble -- --tag v0.2.3  # sign, checksum and write the notes
npm run release:publish -- --tag v0.2.3 --assets dist-release/assets \
  --title-file dist-release/RELEASE_TITLE.txt \
  --body-file dist-release/RELEASE_BODY.md --download dist-release/downloaded
npm run release:verify -- v0.2.3 --dir dist-release/downloaded
npm run release:publish -- --tag v0.2.3 --publish
Pushing a v* tag runs exactly that sequence in
.github/workflows/release.yml. The release used to be assembled by hand, and
the notes were written from what those commands printed: every hash in them was
a copy, and nothing compared the bundle hash printed there with the bundle that
shipped.
scripts/assemble-release.mjs stages the whole release into
dist-release/assets/: the bundle and its sidecar, the signed bundle and the
signing certificate when a key is configured, the npm tarball, the skill package
built by the same writer as npm run skill:zip, and SHA256SUMS.txt covering
every file it staged. It empties that directory first, so a file left over from
an earlier run cannot be hashed and published as if this run had produced it.
The notes are half written, half generated. release-notes/<tag>.md holds the
prose — its H1 becomes the release title and has to name the tag — and the script
appends the asset table, the reproduction recipe carrying the real bundle hash,
the signer and fingerprint, and the commit list. The prose is held to the same
rule: a 64-character hex string in it has to be a hash this release publishes,
and writing an ### Assets section of your own fails the assembly rather than
shipping a second, staler table. See release-notes/README.md.
scripts/publish-release.mjs fills the release as a draft, uploads the
assets, downloads every one of them back and compares it byte for byte, and only
--publish makes it public — after release:verify has re-derived the release
from the tag. Re-running is safe: a draft this workflow assembled is refreshed in
place, while a release it did not assemble, or one already published, is refused
by name instead of overwritten.
Signing is optional and its absence is stated rather than hidden: without the
MCPB_KEY and MCPB_CERT repository secrets the release is assembled and
published unsigned, with a notice in the run and a line saying so in the
notes. Add both — the private key stays out of the repository and out of the logs:
gh secret set MCPB_KEY  --repo trajectiq-ai/E2E < ~/signing/key.pem
gh secret set MCPB_CERT --repo trajectiq-ai/E2E < ~/signing/cert.pem
Creating the release and uploading its assets needs contents: write, which the
job requests for itself; if it is refused, the run names the setting to change.
Verifying a published release
git checkout v0.2.2 && npm ci && npm run mcpb
npm run release:verify -- v0.2.2
The release notes promise that the tag rebuilds the published bundle byte for
byte. scripts/verify-release.mjs checks that promise from a checkout of the
tag: the published bundle against your fresh build, every checksum the release
publishes (and that nothing shippable is missing from SHA256SUMS.txt), a
signed bundle against the bytes its signature wraps, the skill package
against a rebuild from the same tag, and that the published archive still
extracts with that version's manifest. The skill package is required of a tag
whose tree carries the publishing workflow; older tags predate it, so there it
is checked when present and skipped when not, like the signing certificate.
.github/workflows/verify-release.yml runs it on demand for any past tag, and by
itself for a release published by hand. A release assembled by
.github/workflows/release.yml runs the same check on its own assets before
it is published — GitHub does not raise release: published for a release created
with the repository's own token, so the check is a step there rather than a
trigger. The .tgz is checked for download integrity only: npm
records the packer's line endings, so a tarball packed locally on another OS is
legitimately different.
Packaging the agent skill
npm run skill:package                    # ../agensi-skill-<version>/, ready to upload
npm run skill:zip                        # only the archive: dist-skill/playwright-e2e-mcp.zip
npm run skill:check                      # build, then compare every copy
npm run skill:check -- ../agensi-skill-0.2.2
skill/ is an Agent Skill — the
instructions an agent follows to drive this server — and the marketplace gets
the same Markdown as a zip with playwright-e2e-mcp/ at its root.
scripts/package-skill.mjs produces that zip, so the uploaded copy is built
rather than assembled by hand, and it refuses what the marketplace rejects: a
missing SKILL.md, a non-text file, a symlink, Thumbs.db.
skill:package writes the whole folder a release would otherwise assemble by
hand — the skill copy, skill/README.md and the archive — to
../agensi-skill-<version> (or --out <dir>), then verifies it with the same
comparison check uses, so a successful exit means the folder really is the
skill tree. It is idempotent: a folder that already matches is left untouched.
A folder that has drifted is refused instead of overwritten, because it may
already be published — bump version for a new package, or pass --force to
replace that one.
The archive comes from the same deterministic writer as the .mcpb, so the
same tree always hashes the same, and text payloads are LF-normalised first:
a CRLF checkout builds the bytes an LF one does. CI runs skill:check, generates
a package folder, and uploads the built zip as an artifact
(.github/workflows/ci.yml).
Every release publishes the package too. Assembling a release builds it from
the release tag and attaches it as <name>-<version>-skill.zip, and the
.github/workflows/release.yml run downloads that asset back off the draft and
byte-compares it with the build before anything is published. The marketplace
upload is that asset, not a folder someone assembled — a deterministic archive
means "the same build as the tagged release" is an exact statement, and
release:verify checks it again against a rebuild from the tag.
.github/workflows/publish-skill-package.yml stays for the repair path: run it
by hand to attach or rebuild the package for a release that is missing it.
skill:check is the other half of that, and the part that matters when a
package has already been uploaded. It builds twice (the bytes must agree),
reads the archive back and compares its contents with skill/ file by file,
then compares a packaged copy — ../agensi-skill-<version> by default, or a
path you pass: the package folder, the bare playwright-e2e-mcp/ folder, or
the zip on its own. Comparisons are by content, never by archive bytes, because
a zip written by a platform zip tool carries real timestamps that say nothing
about whether the Markdown inside it is current. Any file that differs, is
missing or is extra is named on stderr and the command exits 1 — the repository
copy and the uploaded copy are the same document, so an edit to either one
should not be invisible.
Try the example
With Playwright installed in your project:
npx playwright test examples/sample-test.spec.ts
or ask your agent to call run-test with
"testFiles": ["examples/sample-test.spec.ts"] — it hits the public
example.com page, so it verifies browsers, network and the MCP
pipeline in one shot.
License
MIT